
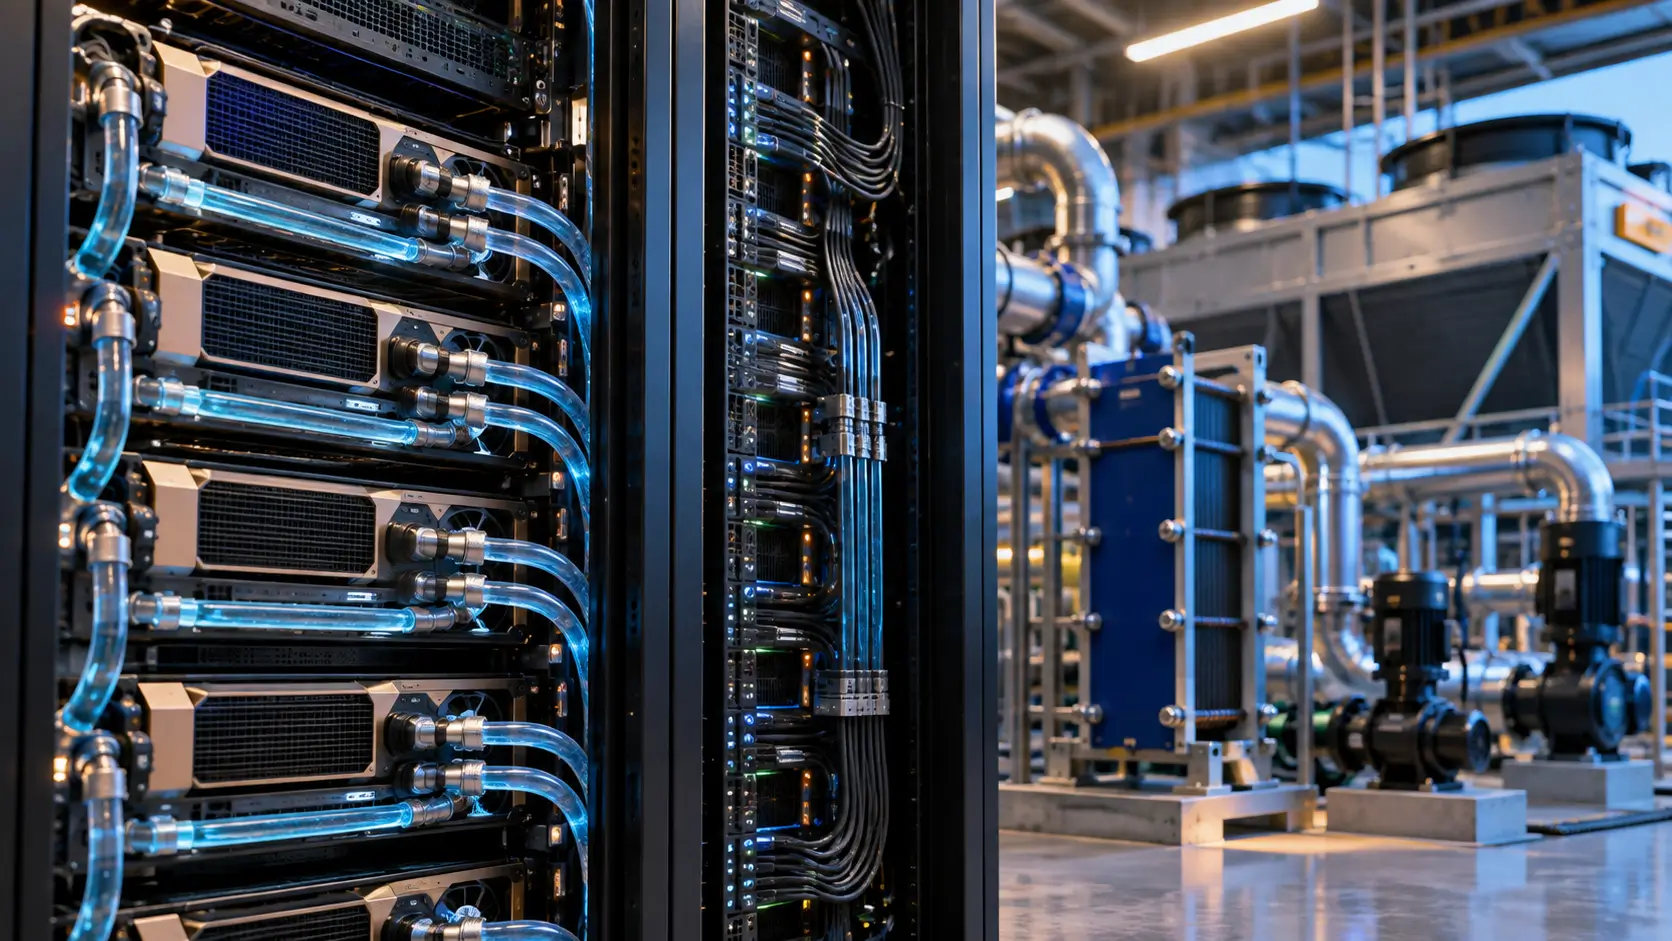
A contracted GPU count does not establish how much compute a facility can actually deploy. High-density accelerator systems also depend on compatible power, networking, racks, coolant distribution, and heat-rejection infrastructure. Those dependencies become critical when hardware requires specific thermal conditions at its intended operating profile. Newer AI systems increasingly combine large accelerator counts with dense rack-scale designs built around engineered liquid loops. NVIDIA’s GB300 NVL72, for example, combines 72 Blackwell Ultra GPUs and 36 Grace CPUs in a fully liquid-cooled rack-scale system. For customers, this means processor inventory matters only when the surrounding infrastructure can support the intended workload configuration.

Contracted GPUs Do Not Automatically Equal Deployable Compute
GPU procurement and infrastructure procurement may appear separate, but their technical dependencies increasingly overlap. A provider can have accelerator inventory while the deployment still requires adequate power, racks, networking, coolant distribution, pumps, and heat exchangers. Uptime Intelligence notes that liquid cooling is typically used above 50 kW per rack or for systems with specialized cooling requirements. Rack powers approaching 150 kW or higher generally require total or near-total liquid cooling, according to the same research. However, advertising liquid-cooled space does not reveal whether the complete cooling chain can support a particular hardware configuration. Customers therefore need to distinguish accelerator inventory from infrastructure capable of supporting the required rack power and thermal conditions.
That distinction matters more when organizations buy large clusters designed to operate as tightly coupled systems. Leading-edge AI training can use high-performance GPUs arranged in dense racks and massively parallel architectures. For these architectures, infrastructure readiness can affect how much of the intended multi-GPU configuration remains available to a workload. The exact impact depends on the system architecture, workload design, network topology, job scheduling, and cluster configuration. Buyers should ask providers to define capacity using both installed accelerators and the infrastructure required to operate the intended configuration. A contract stating processor quantity alone can leave important physical deployment assumptions outside the headline capacity commitment.
Rack Density Changes the Meaning of Available Capacity
Thermal requirements become easier to understand at rack level, where accelerator platforms can concentrate substantial power within limited space. NVIDIA states that a full GB300 NVL72 rack can require up to 142 kW of power. The rack combines 72 Blackwell Ultra GPUs, 36 Grace CPUs, NVSwitch infrastructure, networking components, and supporting hardware. NVIDIA also incorporates tray-level and rack-level liquid-leak detection into the architecture. A hall designed for conventional racks cannot automatically accommodate the same number of high-density systems simply because floor space remains available. Therefore, buyers should examine how many racks can operate at the required density instead of relying on aggregate GPU inventory.

Electrical capacity alone does not resolve this question because heat must travel through several connected cooling stages. Direct-to-chip designs can involve cold plates, cooling loops, CDUs, facility water systems, pumps, controls, and external heat-rejection equipment. Uptime Intelligence identifies additional piping and redundant CDUs among the infrastructure considerations associated with direct liquid cooling. A site-level cooling figure may not show how much thermal capacity can reach each rack under required operating conditions. CDUs regulate coolant flow through components that include pumps, heat exchangers, controls, and monitoring systems. Buyers should trace the thermal path from processors to final heat rejection instead of treating cooling as one facility-wide number.
The Cooling Chain Can Become the Deployment Bottleneck
AI buyers need to know how much compatible cooling capacity exists for the exact hardware platform they intend to use. Cold-plate support cannot be assumed across every server design because technical requirements can differ between systems. Coolant specifications, operating temperatures, flow conditions, connections, and facility interfaces can influence compatibility. Uptime Intelligence notes that cold-plate or immersion support needs confirmation for each IT hardware type. In addition, a new accelerator generation can introduce different infrastructure requirements from those assumed when an earlier capacity plan was created. Multiyear buyers should examine whether the cooling architecture can accommodate planned hardware changes as well as the initial deployment.
The question becomes more complicated when high-density clusters share facilities with conventional IT equipment. Retrofit designs can require different cooling approaches depending on the infrastructure already available inside the building. Liquid-to-air CDUs can support certain deployments where a suitable facility water system is unavailable. Liquid-to-liquid CDUs can connect high-density systems to compatible facility-side water infrastructure where that capability exists. Customers should identify whether contracted capacity depends on new CDUs, piping, mechanical modifications, or heat-rejection expansion that remains unfinished. Capacity supported by commissioned cooling infrastructure carries a different deployment profile from hardware allocations dependent on future infrastructure work.
Thermal Headroom Needs Its Own Capacity Definition
For procurement purposes, this blog proposes three working categories: installed capacity, commissioned capacity, and workload-ready capacity. Installed capacity describes hardware physically present at the location but does not, by itself, establish deployment readiness. Commissioned capacity describes infrastructure that has completed the electrical, mechanical, and operational readiness processes required for deployment. Workload-ready capacity describes whether that infrastructure and compute configuration can support the customer’s intended deployment requirements. These categories represent an analytical procurement model rather than standardized industry definitions. Buyers can use them to compare rack density, cooling architecture, infrastructure readiness, redundancy, and supported hardware configurations more clearly.
Thermal headroom also matters because infrastructure sized for today’s deployment may not provide sufficient margin for tomorrow’s configuration. Hardware refreshes can alter rack power, coolant flow requirements, and facility integration without significantly changing the physical rack count. Recent high-density designs increasingly connect power, cooling, IT space, and operational controls within the same infrastructure planning process. Meanwhile, longer capacity commitments raise a commercial question about who funds and schedules infrastructure changes when the hardware platform evolves. Customers need to understand whether cooling modifications could affect deployment dates, maintenance windows, capacity commitments, or commercial terms. Thermal headroom should become a visible planning consideration rather than an assumption hidden behind the contracted processor count.
GPU Availability Needs a Thermal Readiness Test
Procurement teams can make capacity comparisons more useful by asking providers how much infrastructure-ready compute exists at the required density. That question differs from asking how many GPUs have been purchased, installed, reserved, or assigned to a customer. A meaningful answer should identify which racks can support the relevant hardware configuration and its required cooling architecture. Buyers also need to understand whether that capability exists now or depends on mechanical work scheduled for a later date. This distinction can help technical teams connect commercial commitments with actual deployment conditions before workloads move into production. It can also give finance teams a clearer view of what portion of purchased capacity is ready to generate useful computing output.
The same assessment should extend beyond the first day of deployment because cooling requirements can change during a contract term. A hardware refresh may preserve the promised GPU quantity while changing the physical infrastructure needed to operate those accelerators. Rack power, coolant temperatures, flow rates, connections, and CDU requirements may differ between platforms or server configurations. Buyers should establish how the provider handles those changes before a future refresh becomes an urgent infrastructure project. Contract discussions can then address responsibility for upgrades, commissioning work, deployment delays, and any changes to available capacity. This approach connects the hardware lifecycle with the physical infrastructure lifecycle instead of treating them as separate planning exercises.
Capacity Contracts Need to Follow the Physical Infrastructure
Contract language can reduce ambiguity by connecting computing commitments with measurable infrastructure readiness. Buyers can request clarity on supported rack configurations, cooling methods, commissioning status, operating conditions, and outstanding infrastructure dependencies. They can also separate capacity available today from capacity scheduled after mechanical or electrical expansion. This does not require customers to dictate how a provider designs or operates its facilities. Instead, procurement teams gain a clearer basis for understanding the conditions behind the capacity being offered. Finance and technical leaders can then distinguish immediately usable resources from future capacity that still depends on infrastructure completion.
The larger lesson is that AI infrastructure capacity cannot be understood through processor inventory alone. GPUs need power, networking, rack infrastructure, controls, and heat removal to operate under the conditions required by a workload. High-density platforms make those relationships more visible because their thermal requirements directly shape facility and rack design. Customers evaluating large compute agreements should examine thermal readiness alongside accelerator models, processor counts, network architecture, and deployment schedules. In infrastructure-constrained deployments, allocated GPU numbers can exceed the quantity that available supporting infrastructure is ready to operate in the intended configuration. A stronger capacity commitment explains both the hardware being allocated and the infrastructure available to put that hardware to work.











