
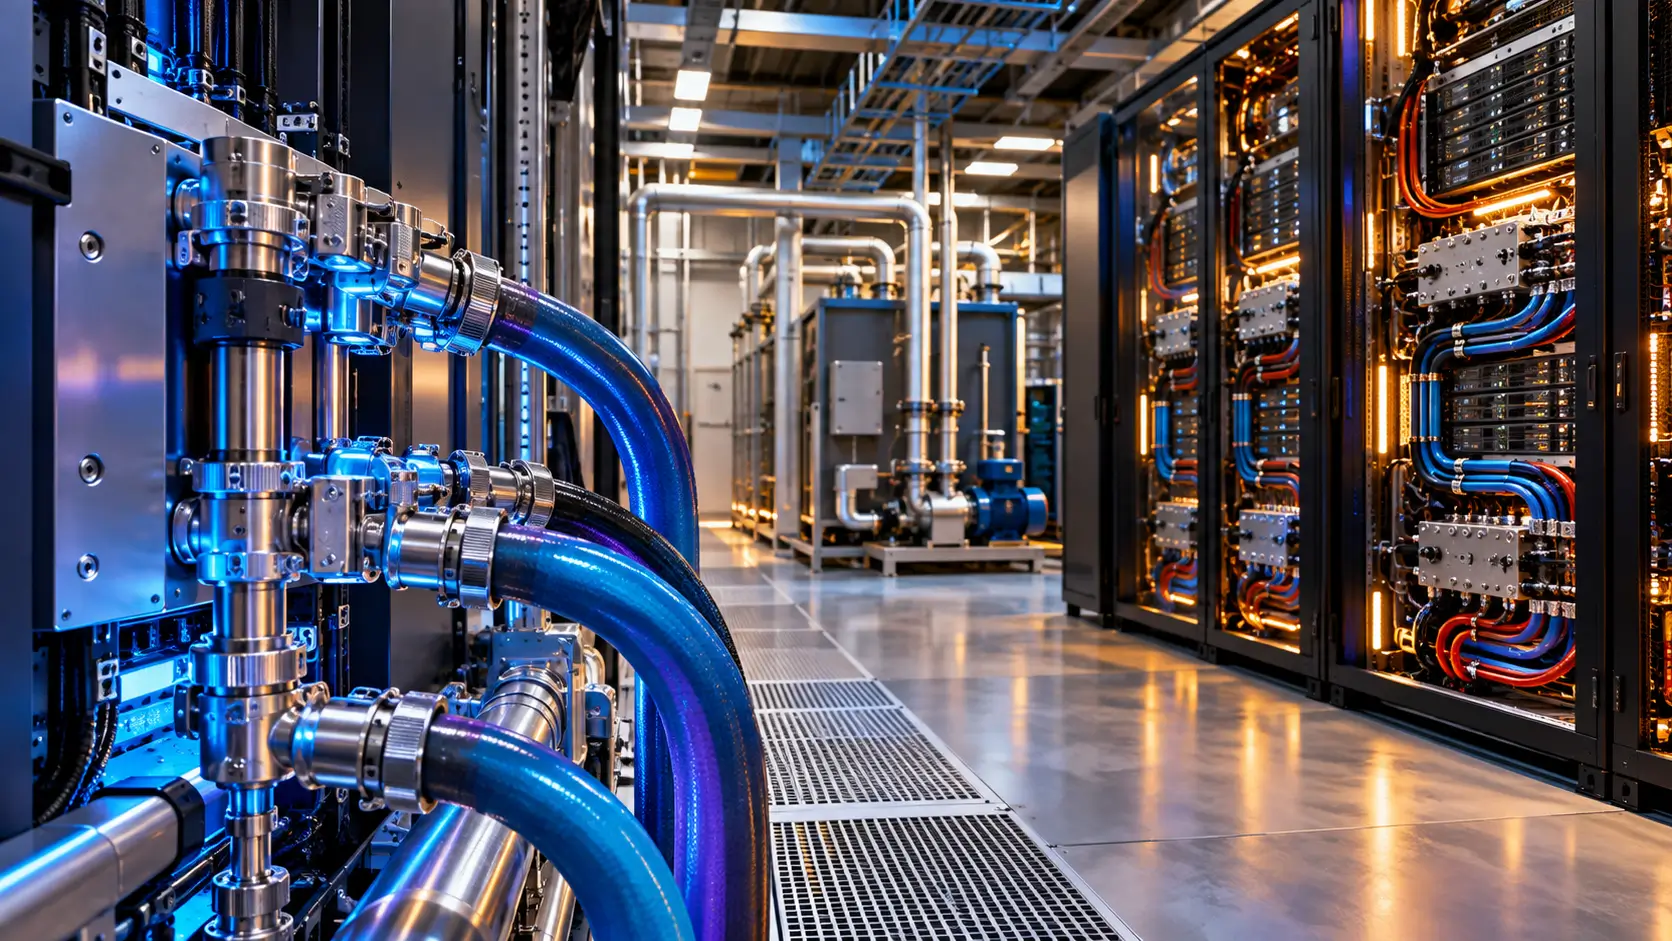
Buying AI capacity can appear straightforward when procurement teams compare accelerator models, hourly prices, reservation periods, and available clusters. Yet the physical environment behind those accelerators can determine whether purchased capacity remains flexible throughout its commercial life. A workload may move between clusters, but its hardware still depends on defined cooling temperatures and flow conditions. Pressure requirements, connectors, manifolds, and heat-rejection systems can also affect where that hardware can operate. These dependencies matter when buyers expand deployments, move equipment, replace providers, or introduce a newer accelerator generation. C-level buyers should therefore consider cooling architecture when assessing the long-term economics surrounding AI capacity.

Cooling conditions can become commercial dependencies
Direct liquid cooling creates a close technical relationship between IT equipment and the infrastructure that supports it. Coolant delivery reaches the IT environment and depends on coordinated components operating within defined technical conditions. Cold-plate systems can include CDUs, manifolds, tubing, quick disconnects, cold plates, pumps, facility interfaces, and controls. Open Compute Project work covers the technology cooling system from the cold plate through the CDU. Each interface can introduce requirements that another facility must satisfy before equipment operates under comparable conditions. Procurement teams should establish whether those requirements use interoperable specifications or depend heavily on a particular site configuration.
Portability Begins With the Cooling Interface
The compute resource represents only one part of a physical deployment supporting liquid-cooled AI hardware. Cooling equipment, liquid distribution, connectors, and defined operating conditions also influence how that hardware can run. OCP cooling-loop guidance identifies cooling capacity, liquid volume, approach temperature, pressure-flow behavior, power draw, and connector specifications. Connection location also matters because the cooling system must integrate correctly with the surrounding infrastructure. Two facilities offering liquid cooling should not automatically be considered technically interchangeable simply because both have sufficient capacity. Buyers evaluating relocation should request enough engineering information to identify requirements beyond electrical power and available rack space.
Interfaces determine how much work migration requires
Portability becomes easier to assess when procurement separates the technology cooling loop from the facility cooling infrastructure. A CDU can provide an interface between these domains while controlling liquid conditions required by IT equipment. Its design and supported operating envelope still influence whether a particular deployment can function correctly. However, moving equipment may require changes to pipework, controls, heat exchangers, CDU capacity, connectors, or facility-side arrangements. Those changes can turn a compute migration into an infrastructure integration project requiring engineering, commissioning, and careful scheduling. Buyers should determine whether another site can reproduce required thermal conditions within an acceptable implementation period.

Migration Costs Extend Beyond Moving Servers
A relocation decision can introduce costs that remain difficult to see when procurement focuses primarily on compute rates. Different cooling architectures may require changes to liquid distribution, CDU integration, rack connection points, connectors, or other interfaces. The commercial effect depends partly on how each agreement assigns cooling infrastructure, integration work, and service responsibilities. Therefore, buyers should model a thermal migration scenario instead of treating physical movement as a routine operational transfer. A universal cost per rack would provide limited value because requirements vary between facilities and cooling designs. Procurement should identify potential physical changes, responsible parties, and infrastructure work that could delay usable compute capacity.
Time can matter as much as equipment expense
Migration economics also depend on how quickly another site can support the thermal configuration required by the equipment. Google has described a rack-mounted liquid-to-air system designed for liquid-cooled equipment inside existing air-cooled facilities. Its 2026 description says conventional facility updates can take months, while its approach supports incremental rack-level installation. That example does not establish a universal migration timeline, because facilities and cooling architectures can differ substantially. It does show why the thermal path can influence deployment choices and the time required for implementation. Buyers should distinguish available electrical capacity from infrastructure that can accept equipment without substantial cooling modifications.
Hardware Refreshes Can Change the Thermal Requirement
Cooling infrastructure designed for current equipment may later need to accommodate hardware with different thermal characteristics. Higher-power components can increase heat-removal requirements and change the supporting conditions needed around the IT equipment. Flow, pressure, temperature, and infrastructure requirements can shift even when the physical rack footprint remains broadly familiar. OCP guidance states that CDU sizing depends on aggregated IT heat load and should consider future thermal margin. That guidance makes cooling headroom relevant when buyers assess infrastructure intended to support later hardware generations. Procurement teams can reduce uncertainty by documenting operating envelopes and procedures for equipment that exceeds existing limits.
Standardization can reduce friction without eliminating engineering work
Industry efforts to standardize cooling interfaces can improve interoperability without making every liquid-cooled deployment automatically interchangeable. OCP cold-plate work addresses standardized interfaces, technical recommendations, quick disconnects, cooling fluids, manifolds, tubing, cold plates, and CDUs. Meanwhile, current work includes a second-generation Universal Quick Disconnect specification covering hand-mate and blind-mate versions. That development shows how liquid-cooling interface specifications can continue evolving as the supporting ecosystem develops. Procurement teams should identify the standards, specifications, and connector generations supported by equipment before assuming permanent compatibility. They should also determine whether connectors, manifolds, tubing, or liquid-distribution components require changes between cooling environments.
Contracts Should Define the Thermal Boundary
AI capacity agreements can become harder to interpret when responsibility changes somewhere along the physical cooling chain. One party may control IT hardware, while another operates the CDU or manages the facility cooling loop. A separate operator could also control building systems that ultimately remove heat from the environment. Failure or insufficient capacity at an interface can affect compute availability despite healthy accelerators and network resources. Uptime Institute has highlighted resiliency considerations as direct liquid cooling enters installations with demanding availability requirements. Procurement teams should identify responsibility for operation, maintenance, monitoring, repair, and replacement across relevant cooling components.
Exit clauses should address more than data movement
Exit planning for liquid-cooled AI deployments should consider physical dependencies alongside workload, data, software, and commercial requirements. Replacement infrastructure must either accept existing equipment or provide suitable conditions for replacement compute hardware. Buyers should examine differences in coolant conditions, connectors, facility-water arrangements, CDU architecture, and heat-rejection capabilities. Contracts can assign responsibility for engineering assessments, transition support, technical information, and required infrastructure modifications. This approach does not require customers to dictate provider facility designs or unnecessarily interfere with operational decisions. Instead, buyers gain enough visibility to estimate the consequences of leaving one infrastructure environment for another.
Procurement Needs a Price for Future Flexibility
A useful procurement model can compare several future states instead of reducing cooling flexibility to one theoretical metric. Teams can examine staying at one site, expanding there, moving elsewhere, or entering infrastructure requiring thermal modifications. Each scenario can account for engineering effort, equipment requirements, commissioning, contractual charges, transition periods, and overlapping capacity. Ultimately, this analysis can show why similar accelerator economics do not always create identical long-term infrastructure exposure. It can also separate commercially negotiable costs from engineering constraints that require physical work regardless of contract terms. Procurement can then evaluate future deployment flexibility as an economic variable alongside the advertised price of compute capacity.
The cheapest compute option may not have the lowest lifecycle cost
C-level buyers need visibility into infrastructure dependencies that can change the economics of an AI capacity agreement. Procurement teams can request operating envelopes, interface specifications, supported cooling architectures, migration responsibilities, upgrade procedures, and documented constraints. Those details clarify what could change when business requirements, hardware generations, or deployment locations evolve. They also show whether promised flexibility accounts for physical cooling requirements across different infrastructure environments. Buyers need not maximize mobility when a stable deployment provides sufficient value despite tighter infrastructure dependencies. The stronger purchasing approach identifies those dependencies early and prices their potential effects alongside the required compute capacity.











