Skip to content

A hardware fault and a thermal maintenance requirement can create very different operational problems inside the same AI environment. Compute platforms use modular components and documented procedures that allow technicians to address defined hardware faults through targeted service work. Liquid infrastructure has a broader physical footprint and includes pumps, heat exchangers, valves, controls, piping, sensors, manifolds, and facility-water interfaces. Some of these components may support several racks, which creates dependencies beyond an individual server or hardware module. A server component and a shared thermal component can therefore sit within different maintenance domains while supporting the same workload. For end users, the critical question is whether operators can maintain thermal capacity without restricting the compute that customers expect to use.
Rack-scale AI architectures make that distinction more important because liquid loops now carry substantial responsibility for removing heat from high-density hardware. NVIDIA, for example, describes its DGX GB rack-scale architecture as modular and designed to improve serviceability. Facility infrastructure follows another maintenance model because technicians may need to isolate pumps, valves, branches, heat exchangers, or distribution sections. However, hardware modularity does not automatically provide equivalent serviceability across every part of the supporting thermal chain. AI capacity remains dependent on infrastructure meeting required operating conditions while individual components or subsystems leave service. Buyers evaluating reserved GPU resources should examine those maintenance conditions alongside the nominal thermal capacity available at a site.
GPU Serviceability Does Not Define Infrastructure Serviceability
AI hardware increasingly includes defined service procedures that allow technicians to identify and maintain specific components within a larger system. NVIDIA identifies several customer-replaceable components within its DGX GB200 service documentation. These include power supply modules, power-shelf management modules, and E1.S cache drives. Those procedures demonstrate component-level serviceability, although they do not establish that technicians can replace every compute component independently. Thermal infrastructure can span a wider physical boundary because one distribution path may interact with several racks, branches, valves, pumps, and heat exchangers. Contractual availability assumptions should recognize these different maintenance boundaries rather than treating every infrastructure intervention as equivalent.
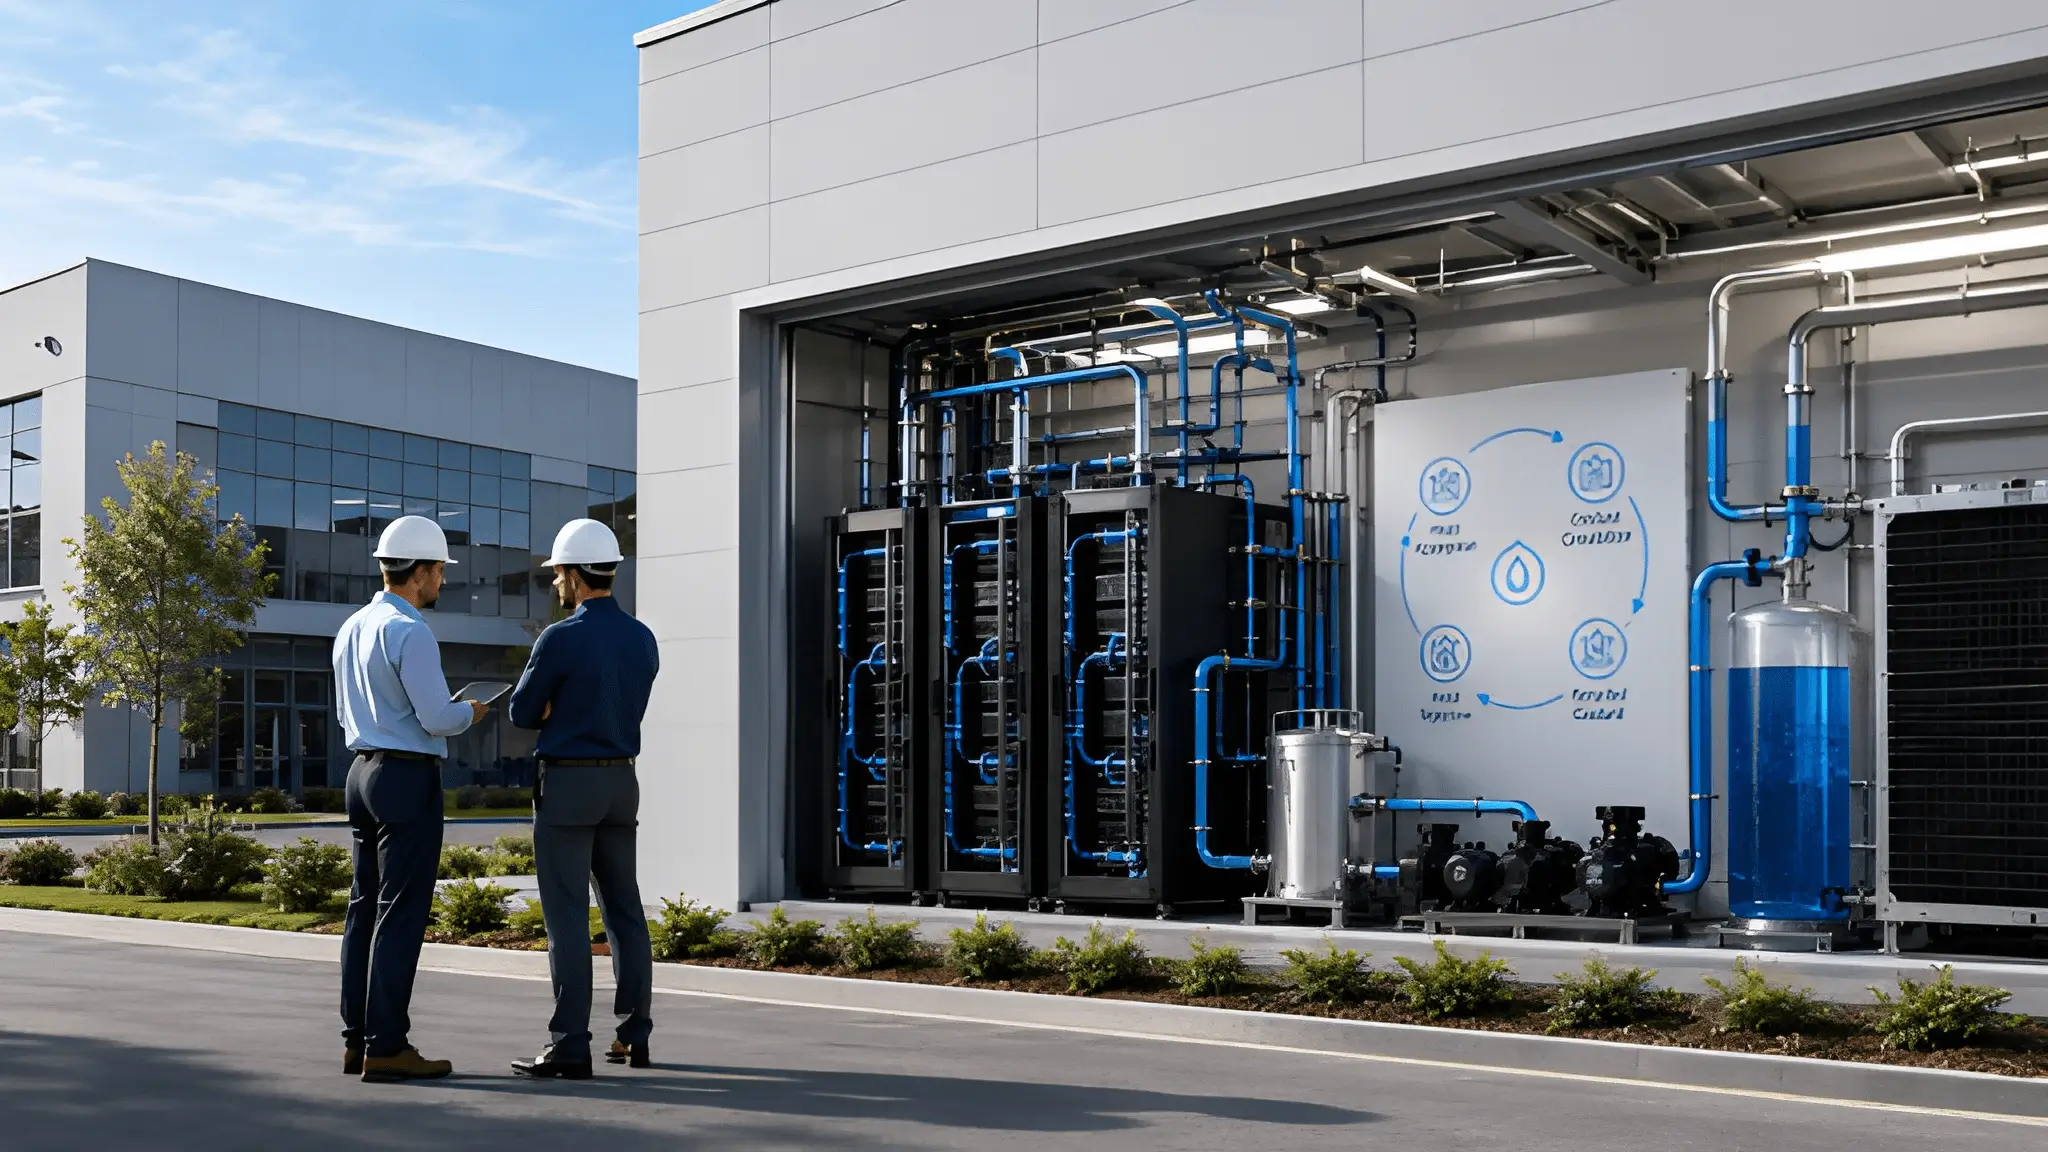
Liquid-cooled deployments also introduce infrastructure interfaces that differ from conventional component-level hardware maintenance. A cooling distribution unit can contain pumps, valves, heat exchangers, monitoring equipment, controls, and connections between separate liquid loops. Maintenance flexibility depends partly on whether operators can isolate individual elements while the remaining infrastructure continues supporting the required load. Engineering guidance supports distribution arrangements that allow equipment modification or repair without requiring a complete system shutdown. Installed heat-removal capacity alone cannot therefore describe how resilient a facility will remain during maintenance. Facilities with similar thermal capacity may provide different maintenance options because their isolation arrangements and redundancy architectures can differ substantially.
Shared Thermal Components Can Expand the Maintenance Boundary
Operators can assess thermal resilience by identifying how much IT capacity depends on each component that may require maintenance or isolation. Rack-level equipment may create a narrow dependency, while shared distribution infrastructure can connect service activity to several downstream loads. The actual impact depends on topology, redundancy, valve placement, bypass paths, control architecture, and the condition of parallel equipment. Therefore, buyers should not assume that plant-level redundancy automatically describes the maintainability of every downstream distribution branch. Redundant pumps cannot establish whole-system maintainability if another required component lacks suitable redundancy or isolation. Mapping these dependencies against compute capacity helps decision-makers identify maintenance activities that could affect the usable capacity of a cluster.
Serviceable designs can reduce that exposure through redundant components, isolation capability, monitoring, and equipment intended for field replacement. Commercial CDU designs already use features such as redundant pumps, continuous monitoring, and replaceable pumps, sensors, fans, or piping components. These features cannot guarantee uninterrupted operation because overall performance still depends on upstream and downstream infrastructure. They demonstrate that designers can treat maintenance flexibility as an engineering characteristic rather than an informal operational expectation. Procurement teams should distinguish between redundancy intended for equipment failure and arrangements that support planned maintenance while carrying the required load. That distinction helps reveal designs where component redundancy exists but maintenance can still restrict commercially usable capacity.
Planned Maintenance Can Become a Compute-Capacity Event
Thermal maintenance becomes commercially important when removing a component changes the amount or location of compute that operators can safely support. Some architectures may have rack groups that depend on defined distribution paths rather than the facility’s total available cooling capacity. Maintenance on one path could then affect specific loads while other parts of the thermal plant continue operating normally. Customers may encounter an infrastructure constraint in that situation even when their GPUs remain functional. Depending on the design, operators may use redundant equipment, adjust supported IT load, or schedule maintenance around workload requirements. Customers purchasing reserved capacity should understand whether planned thermal work can change the amount of compute that remains operationally available.
Different thermal components also require different procedures for isolation, inspection, cleaning, replacement, recommissioning, and verification. Engineering guidance addresses valve servicing and distribution arrangements that can permit repairs without shutting down an entire system. These considerations move maintenance analysis beyond simple redundancy counts and toward the procedures needed to remove equipment safely. Meanwhile, AI platforms can combine component-level service procedures with broader rack-level procedures for particular maintenance activities. Commercial compute commitments may become harder to interpret when the underlying infrastructure dependencies remain less visible to customers. A stronger capacity review maps maintenance procedures to the racks, clusters, and workloads that an intervention could potentially affect.
Redundancy Must Be Tested Against Maintenance Conditions
Redundancy diagrams can appear robust when every component remains available, but planned maintenance deliberately removes equipment from the operating configuration. Operators must determine whether the remaining pumps, heat exchangers, controls, piping routes, and heat-rejection equipment can still support the required IT load. They also need to consider the consequences of another component failing while planned work is underway. This analysis differs from simply confirming the presence of redundant equipment because it examines the system after planned component removal. Concurrent maintainability requires infrastructure to leave service for maintenance while required operating conditions remain available to dependent computing equipment. Customers can use that principle to ask providers how much redundancy and usable capacity remain during actual maintenance.
The analysis should extend beyond pumps because thermal availability depends on an interconnected infrastructure chain. Heat exchangers, controls, valves, filters, strainers, sensors, secondary loops, facility-water connections, and heat-rejection equipment can influence overall serviceability. Even a highly reliable component matters when operators cannot isolate it without affecting substantial downstream capacity. Instead, procurement teams can ask providers to describe credible maintenance states and specify the contracted capacity available during each state. This approach keeps the discussion tied to operating conditions rather than relying only on broad redundancy labels. It also helps customers compare facilities that advertise similar capacity but use substantially different thermal architectures.
Maintenance Flexibility Belongs in AI Capacity Planning
C-level buyers do not need to design thermal networks, but they need enough information to understand the maintenance dependencies beneath purchased compute. Due diligence can map critical thermal components against GPU racks and identify which infrastructure elements operators can isolate independently. Buyers can also determine whether planned work requires capacity reduction, workload movement, temporary operating changes, or coordinated downtime. The review should establish who controls maintenance schedules and how much notice customers receive before work affects supporting infrastructure. These questions turn a mechanical engineering issue into an availability and capacity-planning issue that business leaders can evaluate. They also prevent installed GPU counts from becoming a substitute for understanding the infrastructure required to keep those GPUs operational.
Contract language can become more precise when customers understand the thermal maintenance boundaries beneath their compute allocation. Agreements can define notification requirements, maintenance windows, capacity reporting, escalation procedures, and treatment of planned work that reduces usable infrastructure. Technical schedules can document the cooling dependencies serving contracted rack groups without requiring customers to dictate facility design. This transparency matters because modular compute hardware cannot compensate for every restriction created by shared mechanical infrastructure. Hardware service may involve a defined component procedure, while thermal-network maintenance may require broader isolation, verification, and restoration activities. Durable AI capacity therefore depends partly on whether supporting infrastructure can undergo required maintenance while customer workloads continue operating.