Skip to content
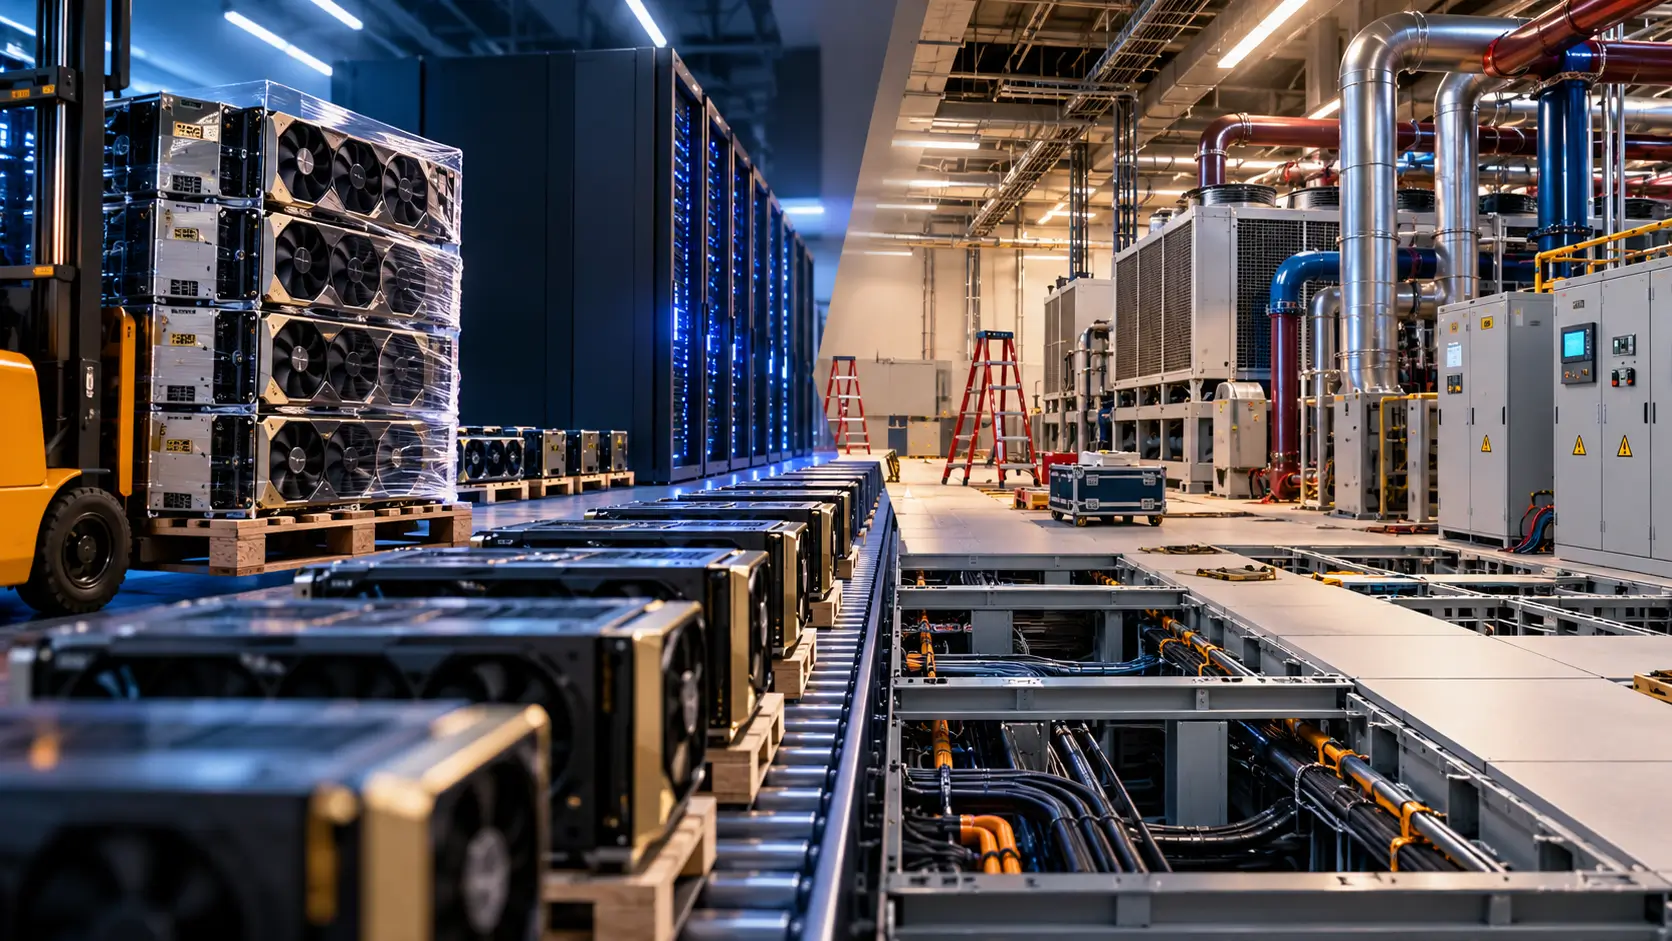
GPU acquisition and supporting infrastructure can progress on very different schedules during an AI capacity expansion. A provider may secure accelerators, servers, or complete rack-scale systems before the physical environment is ready to operate them. For an AI customer, that difference changes what “capacity” should mean during procurement. Ownership or delivery of compute hardware does not establish that every accelerator can immediately support production workloads at its intended operating profile. Modern accelerated clusters depend on electrical distribution, heat removal, high-speed network fabrics, storage throughput, and management systems. These elements must function together rather than as separate resources.
NVIDIA’s current reference architectures illustrate the scale of this dependency. A DGX GB200 scalable unit consists of eight rack systems and carries a thermal design power requirement of 1.2 MW. The architecture combines direct liquid cooling with air cooling. Its wider design also incorporates networking, management nodes, and high-performance storage instead of treating GPU racks as independent assets. Customers evaluating new capacity therefore need to know which supporting systems have reached operational readiness. They also need visibility into infrastructure that remains part of the deployment schedule. The commercially important question extends beyond the number of GPUs a provider has obtained. Buyers need to understand how much inventory can operate as a complete, tested cluster under the promised service conditions.
GPU Supply and Facility Capacity Follow Different Expansion Paths
GPU capacity and data center infrastructure do not expand through identical engineering or procurement processes. Servers can arrive as manufactured products, but the facility accepting them needs suitable rack positions and electrical capacity. It also needs cooling capability, network connectivity, cable pathways, storage access, and operational controls at the intended density. However, infrastructure requirements can change when a provider moves to a newer generation of accelerated computing hardware. Different system architectures can alter the electrical and thermal profile that the data hall must support. The facility must consequently match the characteristics of the system that will actually occupy it.
NVIDIA’s reference architectures across successive accelerated-computing platforms document different combinations of rack configuration, power requirements, cooling design, and networking. These differences show why infrastructure compatibility must be evaluated against the intended compute system. Requirements from an earlier platform cannot automatically define readiness for its replacement. A provider may have physical rack space without equivalent capacity in deliverable power or heat removal. Customers should include this physical compatibility in capacity diligence rather than assuming that every available position can support future accelerators. The expansion schedule should also connect compute delivery with the readiness of power, cooling, networking, and storage. Commissioning work needs a place in that schedule as well.
Power Can Become the Boundary Around Installed Compute
Electrical capacity creates a clear distinction between GPU inventory and operational compute capacity. Every expansion must ultimately connect to a power system that can support the planned equipment. Site-level megawatts alone do not establish how much capacity can reach a particular cluster. Usable power depends on distribution through the data hall, row, rack, and equipment configuration. Electrical infrastructure must match the selected architecture, protection scheme, rack density, and operating requirements. A large power figure at the facility boundary does not eliminate these downstream engineering requirements. Customers should therefore examine where the electricity is available and how it reaches their planned systems.
The wider energy system can impose another timing constraint on a new deployment. Some developments require grid connections, substations, transformers, or additional generation resources before they can support their intended load. The International Energy Agency reported in 2026 that AI deployment faced physical bottlenecks involving energy equipment, advanced chips, planning processes, approvals, and grid connections. It also reported pressure in transformer and gas-turbine supply chains. U.S. Department of Energy analysis has documented rapid growth in data center electricity demand. Lawrence Berkeley National Laboratory estimated that U.S. data centers consumed about 176 TWh in 2023. Its analysis estimated consumption could reach between 325 TWh and 580 TWh in 2028.
Therefore, customers should not automatically treat contracted, energized, and rack-deliverable electricity as equivalent measures of capacity. A provider can have a commercial arrangement for power while additional infrastructure remains necessary before that electricity supports a particular rack deployment. The exact circumstances depend on the facility and its electrical design. Buyers need dates and technical boundaries around the power intended to support their allocation. This becomes particularly important when a commercial commitment relies on a facility expansion that has not reached operational readiness. Power diligence should connect the customer’s cluster to the infrastructure that will actually serve it. That approach provides more information than a site-wide megawatt figure alone.
Cooling Capacity Has to Follow the Hardware Architecture
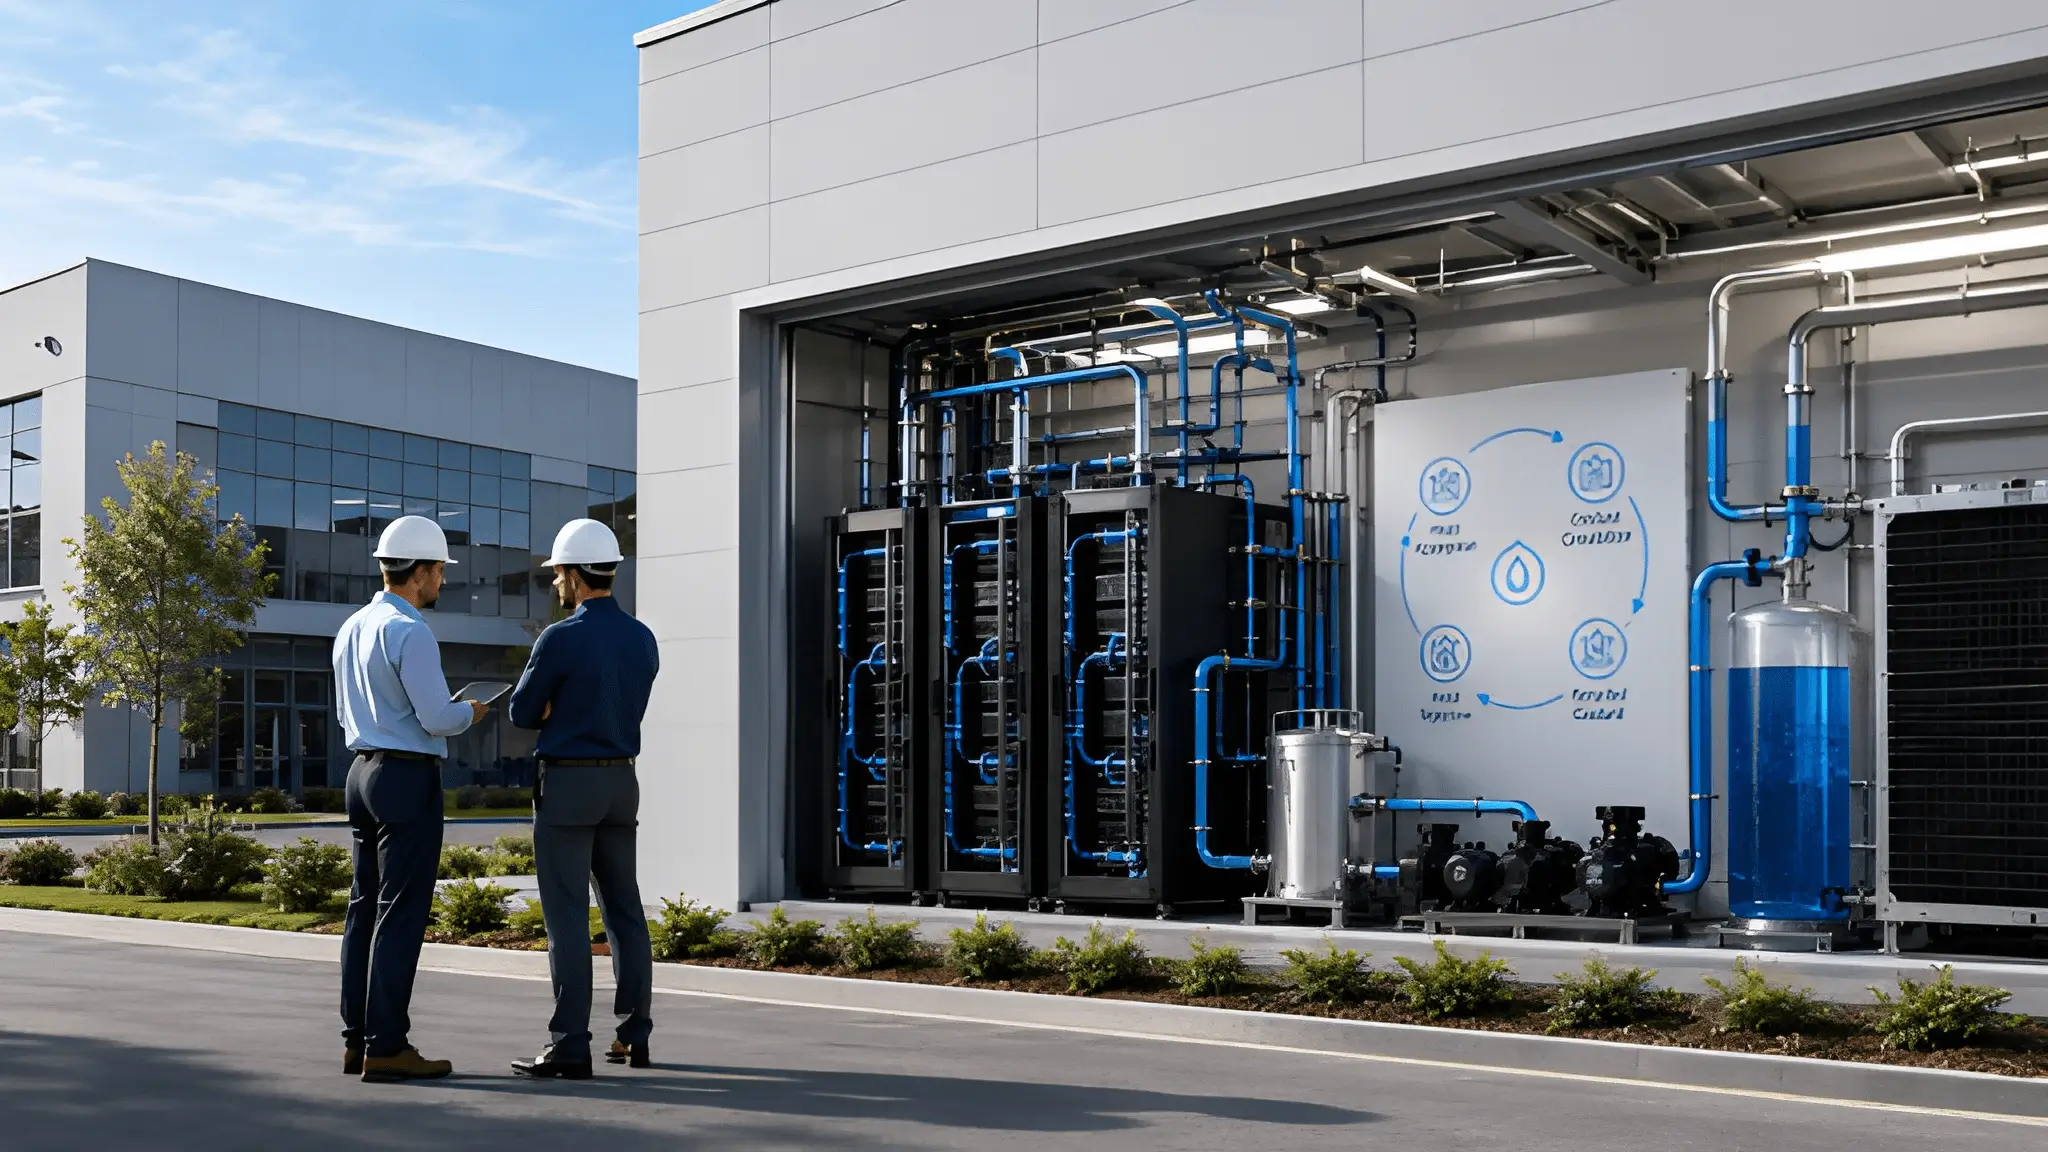
Cooling creates another infrastructure constraint because electrical power consumed by computing equipment ultimately produces heat that must be removed. Modern rack-scale AI systems increasingly integrate liquid cooling for their most power-intensive components. Facility compatibility can therefore depend on more than conventional room-level air cooling. NVIDIA’s GB200 reference design uses a hybrid approach. Direct liquid cooling serves high-power components, while other components remain air cooled. The surrounding environment must support that operating arrangement. A data hall designed for a different thermal profile may require changes before accepting the new configuration.
The GB300 NVL72 platform moves further toward liquid cooling with a fully liquid-cooled rack-scale architecture. The system contains 72 Blackwell Ultra GPUs and 36 Grace CPUs. Supporting such equipment requires a compatible thermal-management design. The exact facility-side equipment and coolant-distribution arrangement depends on the architecture selected for each deployment. A hall may have enough electrical capacity and floor space while still requiring thermal modifications. Customers should ask whether suitable cooling capacity exists at the rows intended for their systems. They should also establish whether that capability has undergone commissioning under conditions representative of the planned load. GPU availability becomes commercially useful when the thermal environment can support the equipment under its required operating conditions.
Network Readiness Determines Whether GPUs Behave Like a Cluster
A collection of accelerators does not automatically function as an effective large-scale training system. Distributed AI workloads depend heavily on communication between compute resources. NVIDIA’s GB200 SuperPOD architecture combines compute racks with an NDR 400 Gbps InfiniBand compute fabric. A separate Ethernet fabric supports storage and in-band management. Networking consequently forms part of the reference system rather than an optional addition after server installation. Each GB200 compute tray includes network interfaces that connect it with these fabrics. The broader topology uses switches and numerous physical connections to extend communication across racks.
Cabling becomes an infrastructure discipline as these systems grow. Deployment teams need documented routes, port mappings, labels, physical support, and serviceable cable arrangements. NVIDIA’s cabling guidance recommends detailed point-to-point schedules covering logical connections, distances, rack positions, and endpoints. Meanwhile, network expansion can require switches, optics, fiber pathways, rack space, power, configuration work, and testing. Those dependencies can progress separately from delivery of the compute hardware. Customers evaluating a promised cluster should ask whether its GPUs are merely installed or connected through the intended production fabric. A capacity commitment becomes more precise when the provider defines the network topology associated with the allocation. Network readiness can then become a measurable component of the deployment rather than an assumed capability.
Storage Can Limit the Value of Available Compute
Storage creates another infrastructure boundary because accelerators require data at rates appropriate for their workloads. Capacity measured only in terabytes or petabytes does not describe that performance. NVIDIA describes its GB200 storage architecture as combining local NVMe with network-connected high-performance shared storage. Local devices can support functions that include caching and temporary checkpoint acceleration. The reference guidance also states that storage requirements vary with workload and dataset characteristics. A single throughput figure therefore cannot describe every AI deployment. Buyers need to consider storage performance in relation to the compute architecture and the workloads they intend to run.
Published guidance for one scalable unit specifies 40 GBps of aggregate read performance for the standard workload category. The enhanced category increases that figure to 125 GBps. Corresponding write guidance stands at 20 GBps and 62 GBps. For a four-unit configuration, the reference read figures rise to 160 GBps and 500 GBps, depending on workload category. These figures demonstrate how storage requirements change with compute scale and workload characteristics. Training environments can lose productive compute time when data access or checkpoint operations cannot keep pace with accelerator demand. Buyers should include throughput assumptions, dataset movement, checkpoint behavior, and shared-storage contention in capacity reviews. GPU quantity alone does not describe the complete performance environment available to a workload.
Commissioning Separates Installed Hardware From Ready Capacity
Installation marks an important deployment milestone, but it does not prove that an entire AI cluster is ready for production. Dense accelerated systems combine compute racks, electrical distribution, cooling equipment, network switches, storage, and management infrastructure. Cabling, monitoring systems, and software add further operational dependencies. These components need to function together under the intended configuration. NVIDIA’s data center design documentation for DGX SuperPOD systems describes deployment as coordination across multiple teams. Its guidance places particular attention on power, cooling, space planning, InfiniBand cabling, and cooling optimization. The complete system therefore extends well beyond the server chassis.
Higher rack density also increases the importance of infrastructure surrounding the compute equipment. A limitation outside the server can restrict the capacity that installed accelerators deliver. Testing should establish whether the electrical and thermal environment supports the planned operating profile. Network, storage, and management layers also need to function according to the deployment design. Instead, treating server arrival as the sole readiness milestone can conceal dependencies elsewhere in the system. An end user can reduce this ambiguity by requesting separate milestones for delivery, installation, infrastructure completion, integration, and acceptance testing. Production availability can then represent a distinct final stage. This framework does not assume that every provider will experience delays; it defines more precisely when acquired compute becomes serviceable capacity.
Hardware Refreshes Can Reopen Infrastructure Questions
Infrastructure planning does not end when the first cluster enters production. Future hardware generations can change the physical assumptions behind an existing deployment. NVIDIA’s reference architectures show that accelerated-computing platforms can differ in rack configuration, power density, cooling design, and networking. Supporting facility requirements can change with those characteristics. These differences do not establish a universal progression for every deployment because facility and system configurations vary. They do show why customers cannot evaluate a refresh through GPU performance alone. A newer accelerator platform may introduce physical requirements that differ from those of the hardware it replaces.
A provider replacing older equipment may need to reassess power distribution, rack layout, cooling capability, network interfaces, and cable management. The balance between compute equipment and supporting infrastructure may also change. Whether an existing facility can accommodate a new platform depends on its electrical, thermal, spatial, and network capabilities. Customers signing multiyear commitments should ask how providers manage infrastructure changes during accelerator refreshes. The answer matters when a promised hardware upgrade depends on facility work that follows a separate deployment schedule. A server delivery date cannot describe those infrastructure dependencies by itself. Capacity planning becomes more durable when the commercial roadmap considers the physical characteristics of expected compute generations. It should not assume that every replacement system fits within the infrastructure envelope of its predecessor.
Customers Need an Infrastructure-Backed Definition of Capacity
For an AI buyer, the practical response is not to discount a provider’s expansion plans. The buyer instead needs enough technical detail to understand what supports those plans. Capacity discussions can distinguish GPUs that have been ordered, delivered, installed, interconnected, commissioned, and released for customer workloads. Each status represents a different stage of deployment. Power diligence can establish whether relevant megawatts are available to the facility and distributed to the required data hall. It can also establish whether the electrical system can deliver that capacity at the rack density assumed by the design. This level of detail provides more context than a single capacity figure.
Cooling diligence can determine whether intended rows have the thermal capability required by the planned equipment. It can also identify whether liquid-cooled systems depend on facility modifications that remain incomplete. Network and storage reviews should connect accelerator allocations to the fabrics and I/O performance required by customer workloads. The need for this broader view is growing as AI-focused infrastructure consumes more electricity. The International Energy Agency projects electricity consumption from AI-focused data centers to triple between 2025 and 2030. Total data center electricity consumption is projected to roughly double over the same period. Those projections do not mean that every provider will encounter identical infrastructure constraints. Facility design, geography, power procurement, workload mix, and deployment strategy create meaningful differences between operators.
Customers gain a more technically accurate picture when they evaluate compute alongside the infrastructure required to operate it. GPU counts remain useful, but they describe only one component of a larger production system. Electrical capacity determines whether the equipment can receive the required power at its intended location. Cooling determines whether the resulting thermal load can remain within the system’s operating requirements. Networking determines whether accelerators can communicate through the architecture intended for distributed workloads. Storage influences whether data and checkpoints can move at rates suited to the compute environment. Commissioning establishes whether these components function together under the planned configuration. A capacity commitment becomes more meaningful when these physical readiness conditions accompany the headline GPU number.