Skip to content

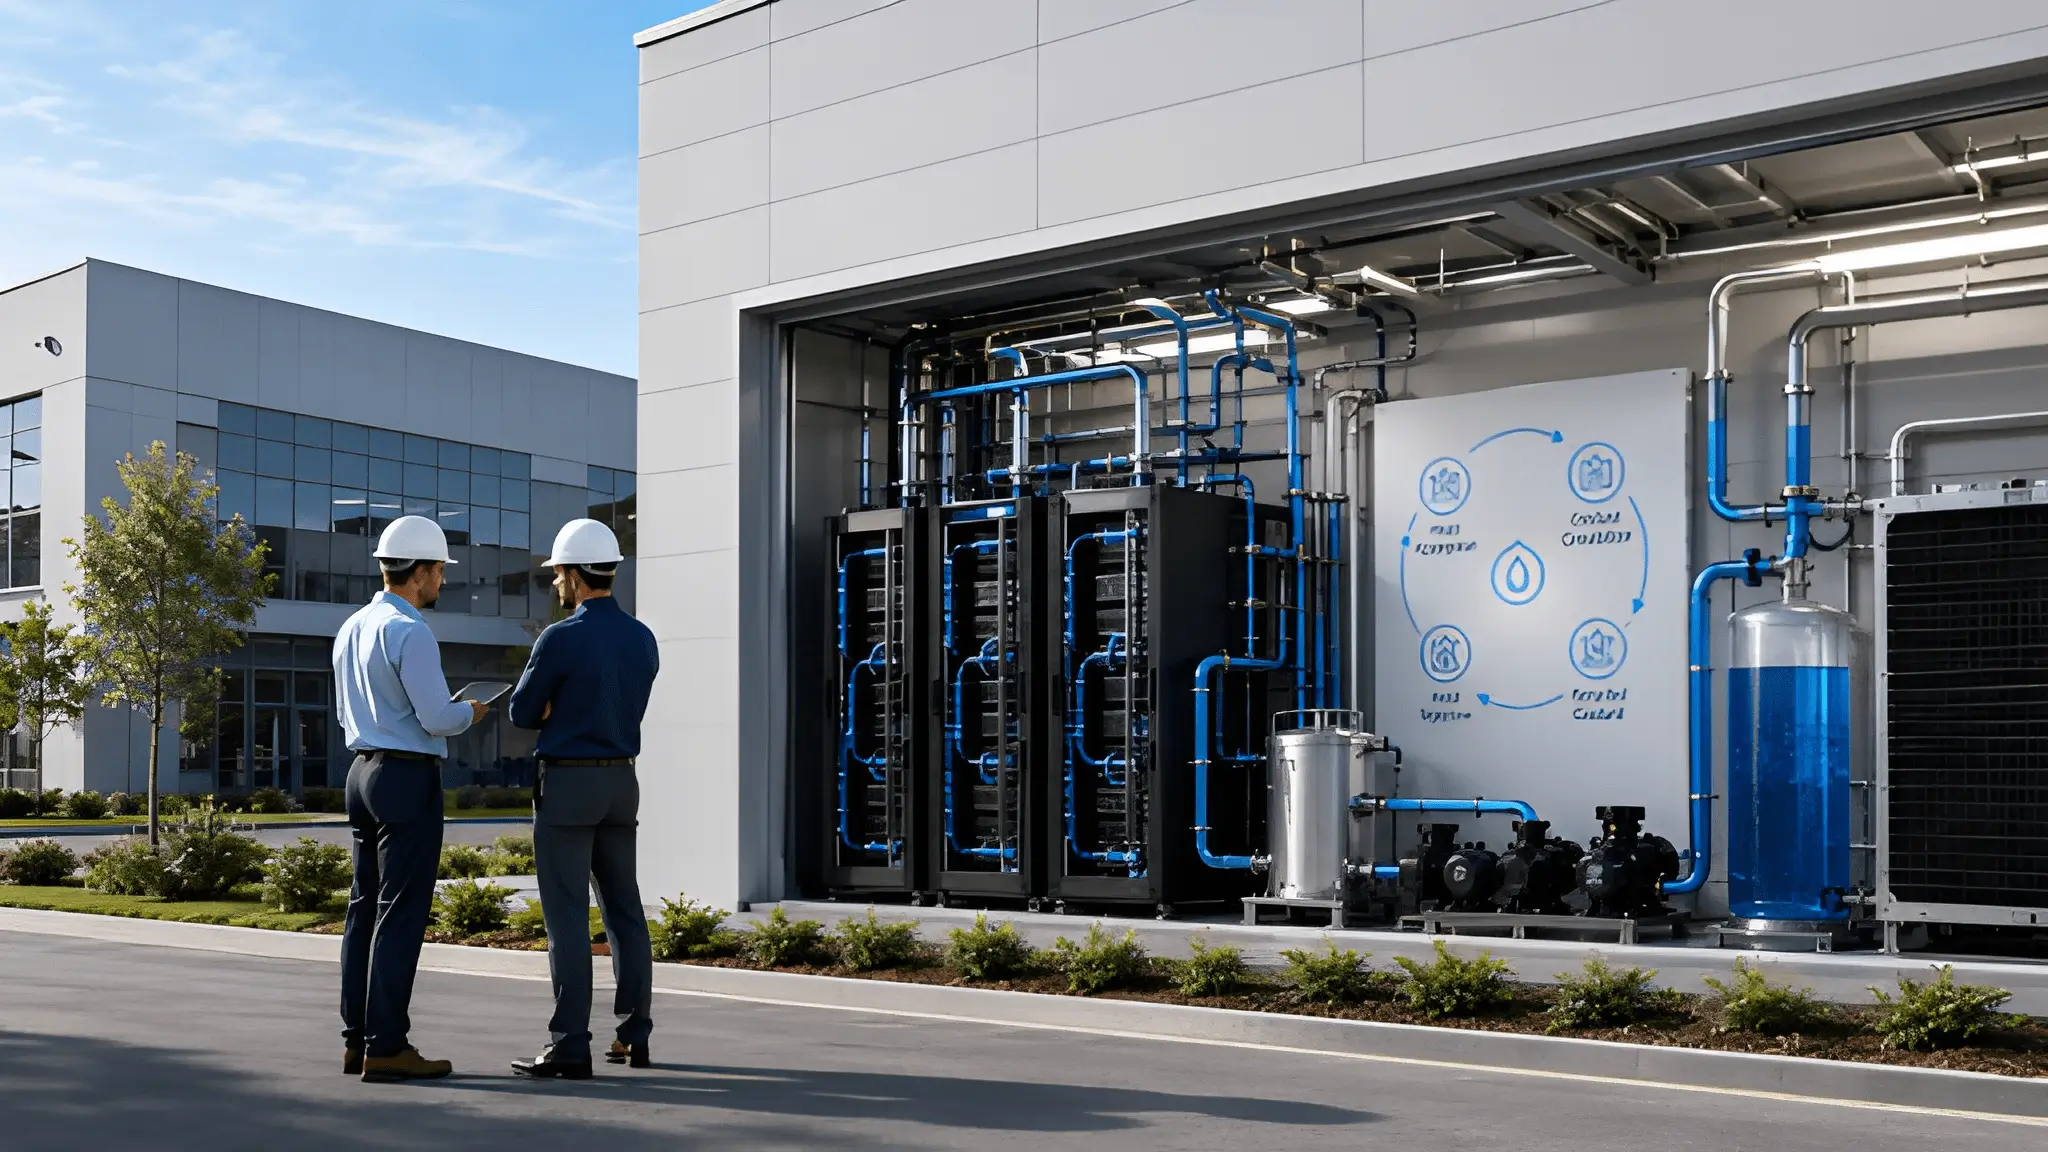
AI customers may soon discover that reserving GPUs and reserving usable AI capacity are not necessarily the same commercial act. High-density systems place greater demands on thermal infrastructure. As a result, the cooling environment supporting a deployment can become part of the capacity equation. A provider may have compute hardware available but still need suitable liquid-cooling infrastructure around the intended racks. Without that infrastructure, the hardware may not support the planned deployment.
That distinction matters because AI capacity reservations can specify resources through GPUs, nodes or clusters alongside deployment dates and contractual terms. Liquid-cooled infrastructure introduces another layer because customers also depend on thermal conditions that cannot move as freely as software workloads. Pumps, heat exchangers, coolant distribution equipment and piping can influence where high-density hardware operates. Facility-side heat-rejection systems can also affect deployment options. The commercial consequence is important: compute availability alone may provide an incomplete picture of deployment readiness. AI buyers therefore have reason to examine whether reserved capacity includes the physical cooling conditions required for operation.
Reserved AI capacity could become increasingly tied to a specific thermal environment.
The concept of reserved capacity works cleanly when infrastructure resources remain relatively interchangeable across a provider’s available footprint. Some agreements give providers control over infrastructure placement. In those cases, providers can determine where contracted compute operates while meeting the applicable service requirements. Higher-density liquid-cooled deployments can complicate that flexibility because supporting infrastructure may differ among halls, rows, rack positions or facilities.
A rack that can physically accommodate servers does not automatically provide every thermal condition required by each hardware configuration. Flow capability, temperature conditions and pressure requirements can affect deployment planning. Heat-exchanger capacity and the broader cooling architecture can matter as well. Customers do not need to manage those engineering details themselves. They do, however, need to understand the commercial consequences when those details restrict placement. Reserved GPUs that depend on a constrained cooling environment may behave differently from capacity available across several technically compatible locations. Thermal compatibility can therefore move from an engineering detail into the AI capacity discussion.
Customers may need to ask what exactly has been reserved for them.
An AI reservation can sound precise while leaving important infrastructure assumptions undefined. A contract might identify compute quantities and service dates without providing much visibility into the supporting physical environment. That arrangement may work when the provider retains enough infrastructure flexibility to satisfy the commitment without affecting the customer. The calculation changes when a workload requires fewer compatible deployment locations because of power density or cooling requirements.
Customers may then want to distinguish hardware allocation from operationally ready capacity rather than treating those concepts as interchangeable. This distinction does not require customers to dictate facility design or interfere with normal provider operations. Instead, it gives procurement teams a clearer basis for understanding the conditions required before reserved compute becomes usable. A reservation with adequate supporting infrastructure offers a different commercial proposition from one that depends on infrastructure becoming available later.
Liquid cooling could make location more important to capacity commitments.
Cloud services can abstract many physical infrastructure details from customers. Workloads can therefore consume computing resources without customers directly managing the underlying servers and facility systems. AI infrastructure can expose limits to that abstraction because increasingly dense hardware may depend on specific power and thermal conditions. Liquid cooling does not eliminate flexibility. However, it can make physical compatibility more important when providers decide where to place equipment.
A compatible rack position may depend on more than available floor space. The surrounding thermal system must also accommodate the intended equipment. Moving a deployment can therefore involve more than relocating servers or changing a logical allocation. The alternative location needs appropriate supporting infrastructure. Providers must account for those requirements while managing other customer commitments. For end users, the location behind a capacity reservation can matter even when the customer never sees the physical rack. The commercial question is whether the provider can preserve promised capacity when the original location cannot support the plan.
Portability may depend on cooling compatibility as much as compute availability.
Capacity portability becomes important when customers expect providers to shift resources within a broader infrastructure portfolio. Another available cluster might appear to offer an obvious substitute when the original capacity cannot arrive as planned. Yet comparable compute hardware does not mean that every deployment location provides identical infrastructure conditions. A substitute location must support the relevant hardware configuration and network requirements. It must also accommodate the necessary power demand and thermal characteristics.
Liquid cooling adds another compatibility consideration because cooling architecture and available thermal capacity can vary between deployments. Customers evaluating portability may therefore need to ask whether an alternative capacity pool is operationally equivalent. Simply knowing that spare GPUs exist elsewhere may not answer that question. The issue becomes more important when reservation agreements span hardware generations or extend across long deployment periods. Aggregate compute availability does not establish deployment readiness by itself. A target location must also satisfy the hardware’s applicable power, networking and cooling requirements.
The reservation conversation may need to move beyond GPU counts.
GPU quantities remain important because customers need a clear understanding of the compute resources available to their workloads. Yet a raw hardware count says little about whether every unit can operate under the required facility conditions. AI procurement teams may increasingly need to treat capacity as a stack of dependencies rather than a single inventory number. That stack can include compute hardware, networking and electrical capacity. Rack infrastructure and cooling resources also form part of the operating environment.
Those dependencies do not automatically mean that a reservation carries unusual risk. Their presence alone does not establish whether a provider can meet a specific capacity commitment. The issue emerges when a commercial promise describes only the compute layer while delivery depends on constrained or unfinished infrastructure. Customers need enough transparency to understand that distinction without receiving an engineering manual for the facility. A stronger reservation model would connect the promised compute quantity with the infrastructure conditions needed to make that capacity operational.
AI buyers may need clearer answers about what happens when thermal conditions change.
Hardware road maps can create another complication when capacity commitments extend across equipment changes. New equipment may introduce different infrastructure requirements. A future system can bring different rack densities, power characteristics or cooling requirements from those considered during initial capacity planning. Providers can engineer for those changes. Customers, however, should not automatically assume that every reserved location will support every future configuration without modification.
This matters when an agreement creates upgrade expectations or capacity planning assumes later hardware will occupy an existing footprint. The relevant question is not whether liquid cooling can support future AI hardware in general. Customers need to know whether the specific reserved environment can support the configuration promised to them. If upgrades require infrastructure work, the timing of that work can become relevant to deployment planning. Customers may consequently want reservation terms that explain how material infrastructure changes affect delivery schedules or replacement capacity. Such clarity can make thermal evolution part of normal capacity governance instead of an issue discovered close to deployment.
Liquid-cooled capacity could become a distinct commercial resource.
High-density AI systems depend on more than individual compute components. Deployment also requires compatible power, networking, rack and cooling infrastructure. In that context, a GPU inside a compatible liquid-cooled deployment may have a different capacity profile from identical hardware awaiting suitable infrastructure. Providers will still manage the engineering complexity. Customers will care about the outcome when it affects deployment timing, portability or upgrades.
That dynamic could encourage the market to describe reservations with greater precision around readiness instead of relying mainly on hardware counts. Buyers might ask whether capacity is physically deployable and whether supporting infrastructure has already been allocated. They might also ask whether equivalent replacement environments exist. Those questions do not diminish the value of GPU reservations. Instead, they connect hardware availability with operational conditions. Liquid cooling therefore has the potential to change AI procurement without becoming a procurement product itself. Customers may begin thinking about reservations as complete operating environments rather than processors in isolation.
The strongest reservation may be the one that defines usable capacity.
End users ultimately buy AI capacity because they need workloads to run, not because they need ownership of a particular thermal architecture. That practical objective should shape how customers evaluate increasingly dense infrastructure commitments. A useful reservation should provide confidence that promised compute can operate within the agreed deployment window and service conditions. When liquid cooling becomes essential to that outcome, its availability becomes commercially relevant. The customer does not need to manage the cooling system directly for that dependency to matter.
Buyers do not need every pump specification, pipe diameter or facility schematic to protect that interest. They need clear definitions of readiness, replacement options and dependencies that could materially affect access to contracted compute. AI infrastructure now incorporates increasingly specific power and cooling requirements. Clear definitions can therefore help customers determine whether headline GPU quantities correspond to capacity that can operate under agreed conditions. Liquid cooling could ultimately change capacity reservations by forcing the industry to answer a deceptively simple question. When a customer reserves AI capacity, what exactly is ready for that customer to use?