Skip to content
A data center can run its electrical and mechanical systems efficiently while its computing equipment delivers less productive output than expected. Power usage effectiveness remains valuable because it compares total facility energy with the energy delivered to IT equipment. This gives operators a consistent view of infrastructure overhead without measuring the productivity of the computing systems themselves. Processor utilization, memory performance, network behavior, and application execution therefore sit outside the scope of that facility metric. For an AI customer, those conditions matter because the commercial objective rarely centers on consuming electricity or occupying accelerator hours. Customers need completed training runs, generated tokens, processed requests, simulations, or other workload results delivered within defined performance requirements.
Looking Beyond Installed Hardware
This distinction becomes important as AI systems combine accelerators, CPUs, memory, storage, networking, power conversion, and cooling. A high-performance accelerator cannot deliver expected application output when another system component restricts data movement or sustained operation. NVIDIA, for example, specifies its H100 SXM accelerator with configurable thermal design power reaching 700 watts. The accelerator also provides substantial memory bandwidth and specialized computational capabilities for demanding workloads. Those specifications describe component capabilities, but they do not establish how efficiently a customer workload converts resources into completed computation. A stronger measurement approach would retain facility metrics while adding workload indicators that show what customers receive from the supporting infrastructure.
PUE Solves a Different Measurement Problem
PUE became influential because it gave operators a relatively simple method for understanding facility energy overhead. The metric compares total data center energy with the energy consumed by ICT equipment. This makes it useful for examining energy associated with cooling, electrical distribution, and other supporting infrastructure. Uptime Institute has also explained that PUE does not measure the energy performance of IT systems themselves. Its 2024 survey reported an average PUE of 1.56 among respondents reporting on their largest owned or operated facility. Reducing infrastructure losses therefore does not automatically demonstrate that applications produce more computational output from the energy entering the site.
Facility Efficiency Is Only One Layer
A lightly productive server environment can coexist with efficient facility infrastructure because PUE does not measure useful application work. That limitation does not make PUE obsolete, since cooling and electrical losses still affect operating requirements. Customers instead need another measurement layer that follows resource consumption into the computing environment. Uptime Institute has discussed the long-running challenge of connecting IT work with the energy consumed by computing and supporting infrastructure. Proposals for measuring work relative to energy have existed for years without achieving the widespread adoption of PUE. Any customer metric therefore needs defined computational units, workloads, measurement boundaries, and operating conditions to support meaningful comparisons.
AI Makes the Measurement Gap More Expensive
AI infrastructure makes workload-level measurement more important because accelerators operate as components of much larger systems. Performance can depend on communication, memory movement, software execution, networking, and coordinated processing across many devices. NVIDIA’s GB200 NVL72 demonstrates this approach by combining 72 Blackwell GPUs with 36 Grace CPUs in a rack-scale architecture. The design connects those computing resources through a large NVLink domain and uses liquid cooling for major components. Accelerator quantity alone cannot describe sustained application throughput because installed hardware represents capacity rather than completed workload output. Software configuration, communication patterns, batch sizes, model architecture, and utilization can influence the computational output obtained from that hardware.
Benchmarks Show Another Approach
Benchmarking already shows that performance and energy can be examined together when measurement conditions remain clearly defined. MLCommons maintains MLPerf Inference benchmarks for reproducible evaluation across machine-learning systems and also supports power measurement. SPEC applies a similar principle to conventional servers by evaluating energy efficiency alongside server performance under specified conditions. These approaches do not provide a universal production metric because their results depend on particular workloads, configurations, and measurement rules. They do show that resource consumption and computational output can be evaluated together under controlled boundaries. Buyers can apply that principle operationally without assuming that one benchmark score represents every workload they intend to deploy.
The Customer Metric Should Start With the Workload
A more useful measurement model would begin by defining the output that matters for a particular workload. Resource consumption could then be attached to that output through electricity, cooling, hardware time, or infrastructure capacity. An inference service might track successfully completed requests under specified latency and quality requirements. A training environment could instead examine completed workloads under defined model, accuracy, and execution conditions. Storage, scientific computing, rendering, analytics, and transactional systems would require measures suited to their individual computational objectives. This workload-first approach avoids comparing fundamentally different activities through one abstract efficiency number that conceals important application differences.
Service Quality Changes the Result
Measurement boundaries also need to remain explicit because excluding supporting resources can distort an efficiency calculation. Networking, storage, host processors, and supporting infrastructure may all contribute to the resources required for completed computation. Quality and service constraints should sit beside throughput because additional operations have limited value when required service conditions are missed. An inference platform may increase request throughput while failing a response-time requirement that matters to the customer. High resource utilization can also contribute to queuing or contention under certain workload and scheduling conditions. Customers consequently need indicators bounded by the service characteristics that determine whether computational work remains commercially usable.
Utilization Needs Context Before It Becomes Meaningful
Utilization appears attractive because idle computing equipment consumes resources without producing the same output as equipment performing productive work. Yet a high utilization percentage does not prove that hardware performs valuable work efficiently. Processors can remain busy while bottlenecks, retries, poor scheduling, or unsuitable workload placement reduce useful application progress. Uptime Institute distinguishes facility efficiency from IT efficiency and notes that PUE does not account for IT equipment efficiency. Additional IT-level measurements are therefore necessary when organizations want to understand computational performance. Buyers should treat utilization as diagnostic evidence rather than the final measure of resource productivity.
Time Adds Another Efficiency Dimension
Combining utilization with workload completion, energy consumption, elapsed time, and service outcomes can provide customers with a broader operational picture. Time matters because lower-energy infrastructure may still create trade-offs when it takes substantially longer to complete the same workload. Extended execution can occupy accelerators for additional hours and delay dependent workflows. Its effect on future capacity reservations depends on the customer’s scheduling, utilization, and procurement model. Conversely, maximizing speed without considering energy consumption can favor configurations that use substantially more resources for modest performance gains. Executives need visibility into these trade-offs so they can balance cost, performance, sustainability, and deployment priorities.
Resource Boundaries Must Extend Beyond the Accelerator
GPU energy represents only one part of the resource chain supporting an AI workload. Host processors, memory, networking, storage, power conversion, and cooling also contribute to operating the overall system. Rack-scale designs make these dependencies visible by integrating many accelerators with specialized interconnects and cooling infrastructure. NVIDIA documents the GB200 NVL72 as a system containing 72 GPUs and 36 Grace CPUs. Its technical guidance also describes liquid cooling across major computing and switching components. Measuring accelerator energy alone would consequently describe only part of the physical system required to sustain the workload.
Measurement Boundaries Need Transparency
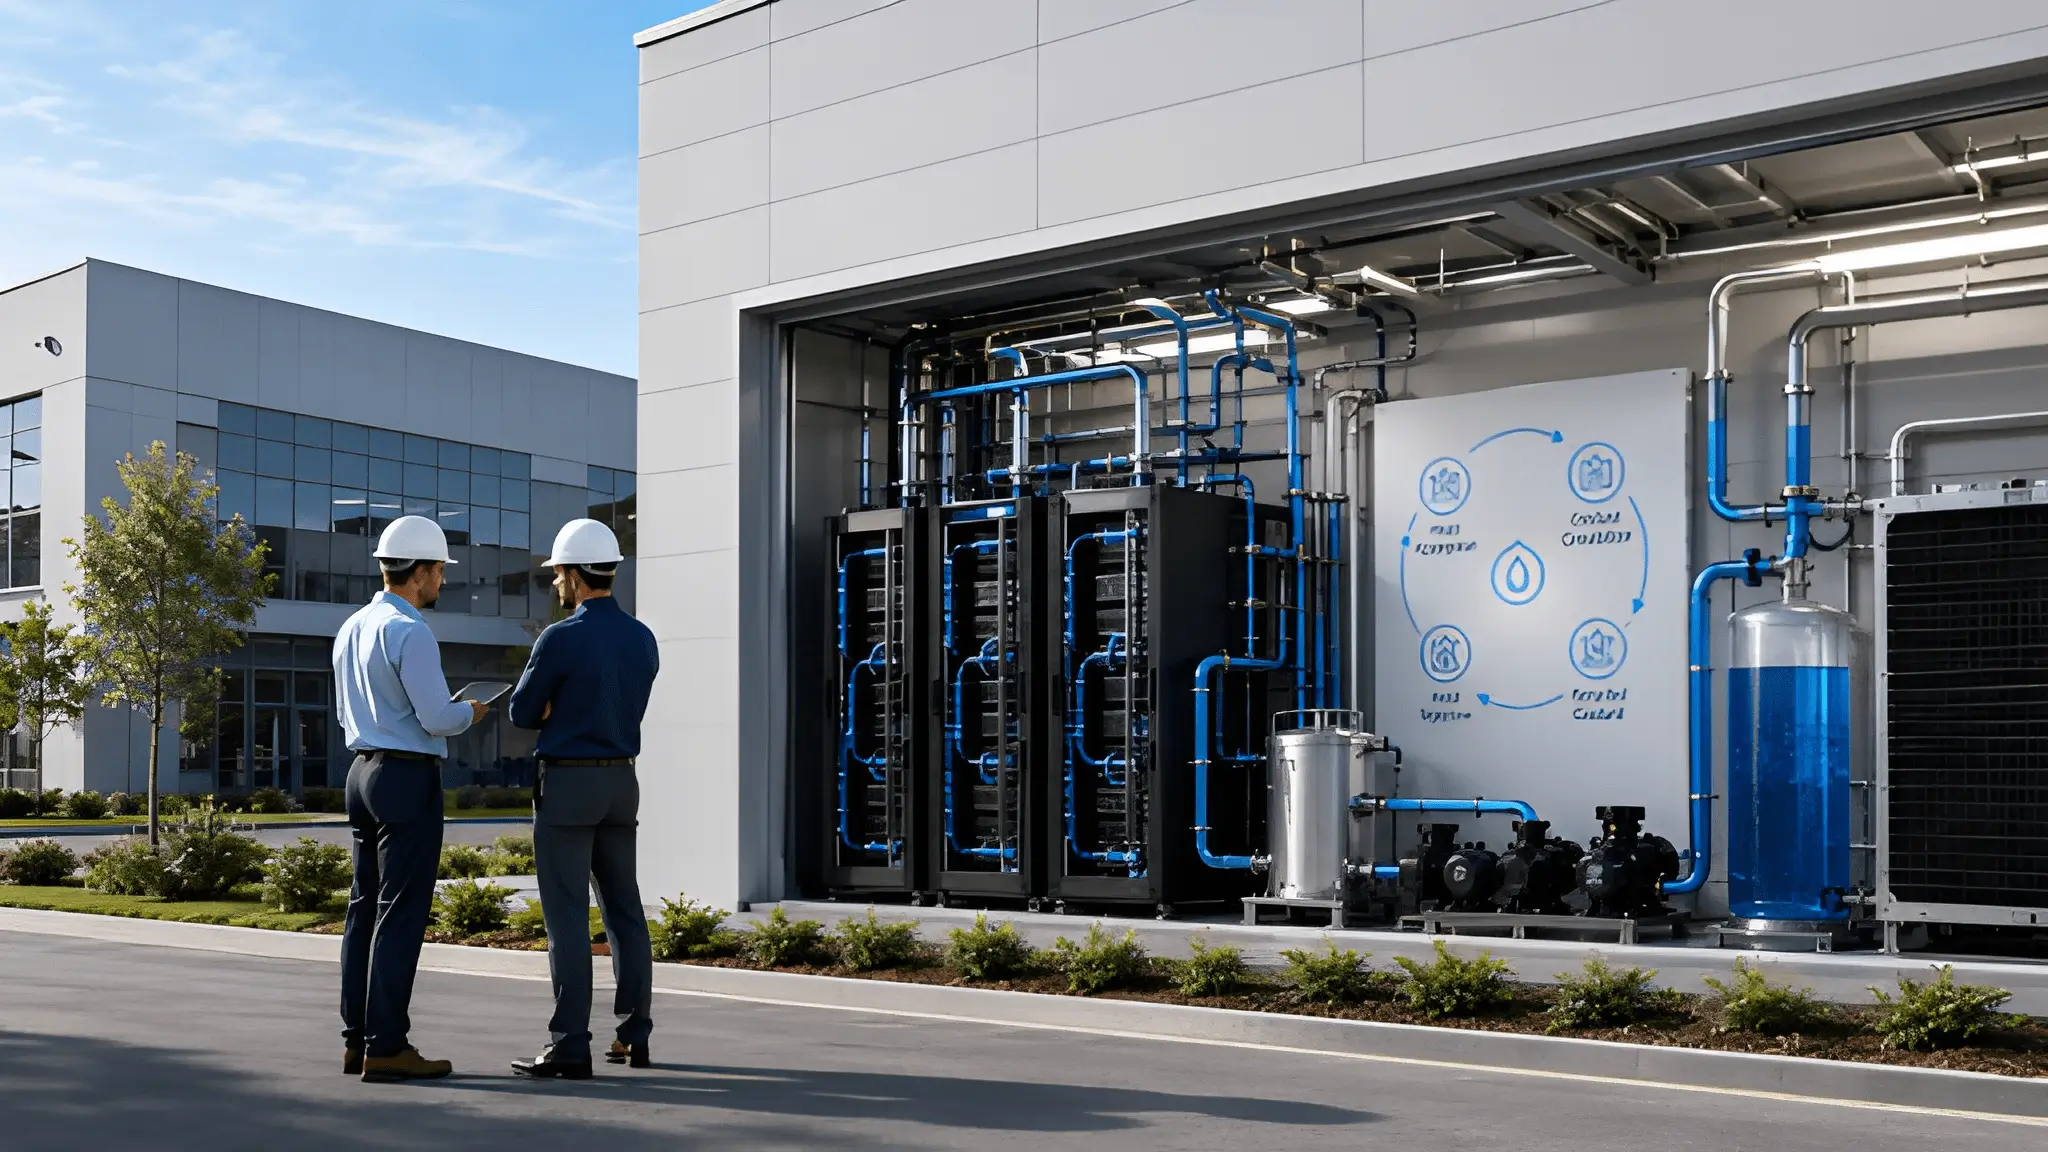
The appropriate measurement boundary may vary by commercial model, but providers should state that boundary clearly. Customers need to understand which resources appear in an efficiency calculation before comparing results across different environments. Two apparently similar measurements could represent different portions of the infrastructure stack when their boundaries differ. Facility resources should also remain visible because shifting consumption between computing and supporting systems does not necessarily reduce total demand. Direct liquid cooling changes the relationship between IT equipment and heat-removal infrastructure, which can influence how conventional facility metrics are interpreted. Uptime Institute has noted that PUE does not account for factors such as water consumption and IT efficiency.
Procurement Can Turn Measurement Into Accountability
AI infrastructure capacity can be described through several measurable inputs and service characteristics. These can include installed accelerators, available electrical capacity, performance specifications, and availability commitments, depending on the commercial arrangement. A buyer reserving substantial compute capacity ultimately depends on what that capacity accomplishes during the contracted period. Workload-specific reporting could help procurement teams compare configurations, software improvements, hardware generations, and operating environments on equivalent application terms. The definitions must remain controlled so efficiency does not appear to improve merely because measurement boundaries or performance requirements changed. Independent benchmark methodologies demonstrate why consistent test conditions and reporting rules matter when organizations compare energy and performance.
Reporting Can Strengthen Capacity Planning
Contracts do not need to reduce every workload to a rigid efficiency guarantee because applications change over time. Models, datasets, software stacks, and user demand can all alter the behavior of the underlying workload. Reporting requirements may instead help customers understand resource consumption relative to completed computational outcomes. Historical baselines could reveal changes after hardware migrations, software updates, infrastructure reconfiguration, or workload growth. Consistent workload definitions could also help planners examine whether additional infrastructure corresponds with changes in usable computational output. Procurement would then gain evidence that connects infrastructure decisions more closely with the economic purpose behind the capacity purchase.
Useful Output Should Shape the Next Efficiency Conversation
No single metric can fully describe AI infrastructure because different measurements answer different operational questions. Facility efficiency, application performance, reliability, energy consumption, water use, utilization, and capacity availability each reveal a different part of the system. The industry already has mature measurements for several of these areas, but customers still need stronger connections between them. A practical framework could retain existing infrastructure indicators while adding workload-specific measures tied to clearly defined resource boundaries. Such an approach would avoid forcing unrelated AI workloads into a misleading universal measurement. It could still give individual buyers a consistent method for evaluating comparable applications and infrastructure configurations over time.
Measure What the Customer Actually Receives
Standardized benchmarks demonstrate that performance and power can be measured together when conditions and methodologies receive careful definition. Production reporting can adopt that discipline while recognizing variables that controlled benchmarks intentionally restrict. Electrical efficiency, cooling design, hardware performance, and utilization would remain important because each describes part of infrastructure behavior. The broader measurement model would connect those inputs with application output under explicit performance and quality conditions. Executives could then examine whether additional infrastructure corresponds with additional usable computation rather than looking only at installed capacity. AI infrastructure becomes more informative to customers when measurement captures both the resources entering the system and the computational outcomes leaving it.