Skip to content

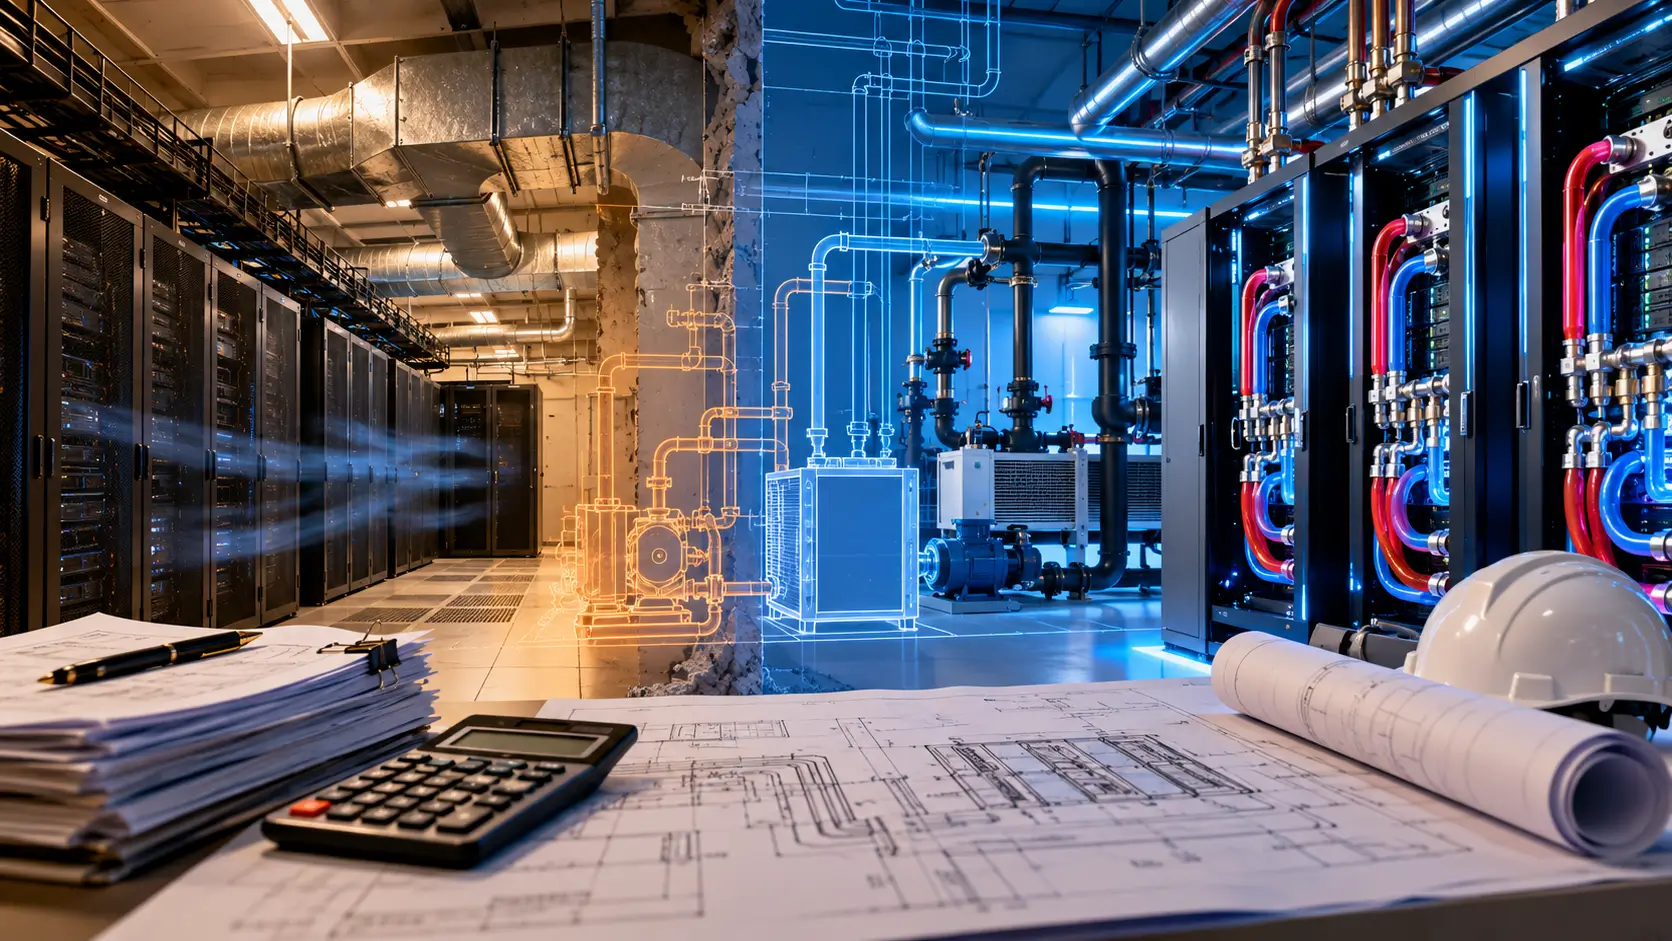
The expensive part of an AI deployment does not always appear when the hardware order receives approval. Some costs stay hidden until that hardware meets the infrastructure expected to keep it operating. Cooling can create this delayed exposure when compute architecture changes faster than the thermal systems supporting it. A deployment may have power, network connectivity, floor space, and an agreed hardware schedule but still need significant thermal changes. Those changes can involve piping, controls, commissioning, operating procedures, and different methods of carrying heat away from the compute. C-level planning therefore needs to separate normal cooling expenditure from the cost of changing the cooling architecture itself.

Cooling transition risk does not mean every AI deployment needs an immediate replacement of existing thermal infrastructure. Air cooling also remains relevant across many compute environments and can continue working alongside liquid cooling. Risk emerges when the current cooling path no longer matches the thermal requirements of planned equipment. Some environments can address that mismatch through targeted modifications, while others may need deeper changes across the heat-removal path. Each change can affect installation, testing, maintenance, resilience planning, and future hardware decisions. A dedicated budget line makes this exposure visible before individual thermal requirements become urgent project costs.
The distinction matters because compute hardware and supporting infrastructure do not necessarily change on the same schedule. A cooling system can remain functional while becoming less suitable for a new generation of equipment. Existing and emerging cooling approaches may therefore need to coexist during parts of the transition. Engineering reviews, connection changes, monitoring, controls, commissioning, and maintenance preparation can all follow from that overlap. These requirements do not automatically indicate poor planning because the final scope often depends on the hardware and architecture selected. The important budgeting question is what the journey from the current thermal state to the required state could demand.
Cooling Transition Risk Starts Before Physical Conversion
Cooling transition risk can begin while the existing thermal system continues to operate normally. The first exposure often comes from a mismatch between future compute requirements and assumptions embedded in the current environment. Hardware selection can establish new requirements for heat removal, coolant delivery, interfaces, and residual air cooling. These conditions make thermal compatibility an early planning issue rather than a task that starts after servers arrive. Delaying detailed analysis can reduce the number of practical choices available when deployment commitments become harder to change. Budget planning should therefore recognize thermal uncertainty before physical cooling modifications begin.

Future compute can change the thermal conditions that supporting infrastructure must accommodate. The resulting work may extend beyond installing racks or connecting new cooling equipment. Distribution changes, connection points, controls, monitoring, or retained air cooling can become part of the deployment. The exact requirements depend on the selected hardware and cooling architecture rather than one universal liquid-cooling design. That distinction matters because thermal spending can spread across several infrastructure layers instead of appearing as one equipment purchase. A transition allowance gives leadership room to manage those dependencies without funding speculative modifications before technical requirements become clear.
Cooling Readiness Is Not a Binary Condition
An environment should not be considered ready simply because one part of its cooling chain supports the intended hardware. Rack connections can exist while distribution, controls, heat exchange, or another part of the thermal path still needs work. Readiness therefore depends on how the applicable components function together under expected operating conditions. Testing and commissioning provide evidence that installation has produced a usable cooling system rather than a collection of completed components. This distinction helps budget owners identify work that remains between equipment delivery and operational acceptance. Cooling transition risk becomes easier to manage when readiness reflects system behavior instead of installation progress alone.
A useful cooling budget starts near the compute but cannot stop at the rack. Heat captured from processors still needs a controlled route through the applicable thermal architecture. Depending on the design, that route can involve manifolds, distribution equipment, piping, pumps, heat exchange, controls, and upstream cooling. Some components can also continue rejecting heat into the surrounding air. A rack-level cooling solution can therefore appear complete while another part of the thermal path remains constrained. Financial planning needs to follow the complete applicable heat path rather than the most visible cooling component.
Interfaces Can Hide Transition Costs
Cooling interfaces deserve particular attention because they connect systems that may have different operating requirements. Distribution equipment must work with the temperature, pressure, flow, fluid, and control conditions defined for the chosen architecture. Upstream cooling must also provide conditions that allow the downstream technology loop to perform as intended. Monitoring and control interfaces add another dependency because operators need visibility across relevant parts of the thermal path. A problem at one interface can require corrective work elsewhere in the cooling system. Transition budgets should therefore recognize integration work instead of assuming that compatible individual components guarantee a compatible assembled system.
Cooling work also has to occur in a practical sequence around the wider AI deployment. Piping may need installation before racks occupy an area, while controls can require staged integration and testing. Existing air cooling may need to remain active while a new liquid-cooled configuration enters operation. These dependencies affect when compute can be installed, commissioned, and accepted for sustained use. Poor sequencing can create additional engineering, temporary arrangements, repeated testing, or delayed hardware acceptance. Treating sequence as part of cooling transition risk helps leadership connect thermal preparation with the schedule for usable compute.
Cooling Compatibility Is a Lifecycle Question
Cooling compatibility should not be judged only against the first hardware configuration scheduled for installation. Compute can change while substantial parts of the supporting thermal architecture remain in service. A design suited to the immediate deployment may become restrictive if later equipment needs different thermal conditions. Fluid requirements, connections, controls, distribution, and residual air cooling can all influence that future compatibility. Unlimited flexibility would be expensive and unnecessary, but excessively narrow design can create another difficult conversion later. Budget owners should therefore examine whether current cooling decisions preserve reasonable room for hardware change.
The phrase liquid cooling can hide meaningful differences between thermal architectures. Different implementations can place different requirements on fluids, temperatures, flow, heat exchange, controls, and maintenance. An environment described broadly as liquid ready may therefore support some configurations more easily than others. Technical teams need to evaluate the actual interfaces required by the planned compute rather than rely on the label alone. Leadership does not need to predict every future hardware configuration to recognize this constraint. The transition budget can instead preserve flexibility around unresolved compatibility questions until engineering provides clearer answers.
Maintainability Affects Future Flexibility
A successful installation should also remain practical to maintain, isolate, modify, and expand. Service teams need appropriate access to components that may carry coolant near valuable electronics. Isolation arrangements should support maintenance while meeting the resilience objectives defined for the deployment. Monitoring and controls need to provide useful information during normal operation and relevant abnormal states. Expansion can create new dependencies when additional cooling demand reaches shared parts of the thermal path. Lifecycle planning should therefore consider whether today’s architecture makes tomorrow’s hardware change easier or more disruptive.
The simplest budget assumes that one cooling method ends when another begins. Actual transitions can be more complicated because air and liquid cooling may operate at the same time. Some direct-to-chip systems capture heat from selected components while other components continue releasing heat into surrounding air. Older compute may also remain air cooled while newer equipment uses a liquid circuit. Room-level cooling can consequently retain an important role after liquid cooling reaches parts of the compute environment. Financial planning should account for this coexistence whenever the selected architecture requires it.
Hybrid Cooling Has Its Own Requirements
Hybrid cooling should not automatically be treated as a brief intermediate state. It can become a sustained architecture when air and liquid paths continue serving different thermal requirements. Operators then need to understand how those paths behave as workloads, equipment states, and maintenance conditions change. Monitoring becomes important because remaining room heat still has to stay within the intended operating conditions. The liquid side introduces its own distribution, controls, connections, and maintenance requirements. Transition budgets should recognize the cost of managing coexistence rather than assuming liquid cooling immediately replaces the existing thermal environment.
A staged transition can allow new compute to arrive without forcing every existing rack through the same conversion schedule. This flexibility can help when hardware delivery, workload migration, thermal preparation, and maintenance windows do not align. Parallel cooling approaches can still introduce additional operational knowledge, controls, service procedures, and commissioning work. Budget owners should separate the value of staged migration from the cost of supporting that migration. Planned overlap can preserve options, while unmanaged overlap can leave unnecessary complexity in the operating environment. A clear transition budget gives leadership a way to distinguish between those two conditions.
Temporary Cooling Can Outlive the Transition
Temporary infrastructure deserves careful attention because deployment schedules can extend the life of an intended bridge solution. A cooling arrangement installed for early compute may remain after additional hardware enters service. Removing it can become harder once operating workloads depend on the surrounding thermal architecture. Teams can then inherit a system assembled through several deployment decisions instead of one coordinated design. Documentation, isolation, monitoring, maintenance access, and operating limits become increasingly important under those conditions. Budget planning should consider what happens if a temporary thermal arrangement remains longer than originally expected.
A temporary component should have a defined technical purpose and a clear operating boundary. Its maintenance needs also matter if the equipment remains in service beyond the initial transition period. Some temporary arrangements may justify permanent integration because they continue providing useful flexibility or resilience. Others may create unnecessary complexity once the original deployment constraint disappears. Leadership needs a decision point for determining which outcome applies. Cooling transition risk includes the future work required to formalize, modify, or retire infrastructure that began as a temporary solution.
Transition Maps Prevent Architecture Drift
A transition map can identify which cooling elements are permanent and which remain provisional. It can also define the technical conditions that trigger another conversion stage. This approach prevents additional compute from accumulating around temporary infrastructure without deliberate review. Money alone cannot solve the problem if physical access or maintenance opportunities disappear as deployment progresses. The map should therefore connect budget decisions with the intended technical path toward the future cooling state. Leadership can then assess whether each capacity addition supports or complicates that path.
A cooling transition can look complete on a project schedule while remaining unfinished operationally. Installed components still need to demonstrate that the assembled system performs against defined requirements. Liquid-cooled architectures can introduce dependencies across distribution, piping, pumps, heat exchange, sensors, controls, and compute interfaces. The exact component chain varies according to the chosen design, so commissioning requirements should reflect that architecture. Discovering an integration issue during testing can lead to engineering changes or another validation cycle. Transition budgets should preserve enough flexibility to resolve legitimate commissioning findings before production operation depends on the system.
Component Testing Is Not System Testing
A distribution unit can perform correctly on its own without proving that the complete cooling chain is ready. Its real operating behavior depends on the conditions created by the systems connected around it. Piping, valves, pumps, flow resistance, controls, coolant conditions, sensors, and connected loads can influence that behavior. Commissioning therefore needs to examine relevant interactions rather than rely only on independent equipment checks. A symptom can appear in one location even when the corrective work belongs elsewhere in the thermal path. Budgeting for integrated testing recognizes this difference before an interface problem becomes a deployment delay.
Production compute should not become the first meaningful proof that a new cooling path works whenever another practical testing approach exists. Representative thermal testing can help verify portions of the system before valuable hardware depends on them. Teams can then investigate flow, controls, alarms, piping, distribution, and heat rejection with greater testing freedom. Corrective work is also easier to manage before production workloads create additional operational constraints. Temporary test arrangements can therefore represent useful transition expenditure rather than unnecessary project overhead. Their purpose is to replace assumptions with evidence before the final compute environment relies on the cooling architecture.
Acceptance Criteria Need to Measure Outcomes
Cooling acceptance should describe what the system needs to demonstrate rather than merely confirm that specified equipment has arrived. Relevant criteria can include coolant delivery, monitoring, controls, alarms, isolation, and selected maintenance or failure states. Hybrid architectures may also need evidence that liquid and air cooling operate together as intended. The exact criteria should follow the approved design instead of applying one generic checklist to every deployment. Outcome-based acceptance makes integration problems easier to identify before they move into routine operations. It also gives budget owners a clearer point at which transition spending can begin moving toward closure.
Mechanical completion and operational readiness are not the same project state. Installed piping can still require preparation, controls can require validation, and alarms can require testing. Operating teams may also need procedures and documentation before they can safely inherit the system. A readiness milestone can collect these requirements into a defined decision point before sustained compute operation begins. Leadership then gains evidence about what remains unfinished instead of relying on broad percentage-complete reporting. Cooling transition risk becomes more transparent when the project can explain which technical evidence still stands between installation and use.
Findings Need Financial Room
Commissioning findings do not automatically mean the cooling design has failed. Integration testing exists partly to reveal conditions that component-level work could not demonstrate. Some findings may require control changes, configuration adjustments, revised procedures, or limited physical modifications. A transition reserve can fund justified corrections without turning every finding into a new capital approval exercise. Governance should still require a clear explanation of what changed and why the spending belongs to the thermal transition. This approach protects commissioning without allowing the risk budget to become an unrestricted contingency.
The transition does not end when the cooling system passes commissioning. The architecture immediately enters a maintenance lifecycle that can differ from the previous thermal environment. Liquid loops can introduce distribution equipment, valves, filters, hoses, manifolds, connections, sensors, and fluid-management requirements. The exact maintenance scope depends on the system rather than one universal liquid-cooling model. Responsibility becomes especially important where mechanical infrastructure approaches or enters the compute environment. C-level planning should therefore treat maintenance readiness as part of the transition instead of assuming existing practices will absorb every new requirement.
Serviceability Starts With Physical Design
Technicians need practical ways to reach, isolate, inspect, service, and restore relevant cooling components. A design can perform well during normal operation while remaining difficult to maintain. Poor access or weak isolation can turn routine service into a larger operational event. Valve placement, branch design, equipment position, and instrumentation can therefore influence lifecycle operating risk. These characteristics become harder to change once racks and supporting infrastructure occupy the surrounding area. Transition budgets should recognize serviceability before construction decisions make later improvement expensive or disruptive.
Coolant chemistry and condition can affect materials, corrosion behavior, contamination, and heat-transfer surfaces. Management practices should therefore follow the actual fluid, equipment, and materials used in the selected system. Procedures may cover filling, draining, sampling, filtration, handling, storage, or fluid-condition verification where applicable. Material compatibility also requires attention because liquid paths can contain metals, seals, hoses, and other wetted components. These requirements do not mean liquid cooling is inherently unreliable. They show why introducing a managed fluid circuit can create operational work that deserves explicit planning and funding.
Spare Parts and Ownership Need Early Decisions
Maintenance planning also needs to consider how component availability affects the cooling path. Holding replacements for every item would waste capital, while ignoring important components can extend recovery time. Teams should understand which parts affect shared distribution and which can be isolated locally. The resilience architecture also determines whether maintenance can proceed while other cooling equipment remains available. These relationships help distinguish routine consumables from strategic spares. Cooling transition risk can include appropriate readiness without turning the spare-parts plan into indiscriminate inventory.
Liquid cooling can blur the line between teams responsible for mechanical infrastructure and teams responsible for compute. Practical questions then arise around alarms, maintenance authorization, leaks, coolant condition, and distribution controls. Leaving those questions unanswered until operation begins can create duplicated work or responsibility gaps. Ownership should therefore be defined while the thermal architecture remains under development. Controls, documentation, training, and maintenance procedures can then reflect the teams expected to use them. Organizational preparation becomes part of the transition because the physical architecture can change established operating boundaries.
Documentation Preserves Operational Knowledge
Technical knowledge should survive beyond the engineers who designed and commissioned the initial cooling conversion. Piping arrangements, isolation points, controls, coolant requirements, alarms, maintenance procedures, and operating limits need accurate records. Documentation becomes even more important when staged conversion creates a configuration that differs from the original design. Future engineering teams need that information before changing distribution, controls, equipment, or operating conditions. Treating documentation as a deliverable also strengthens the handover from project teams to operators. The resulting record protects part of the cooling investment by making later maintenance and modification more deliberate.
Cooling architecture becomes more useful when operators can identify relevant changes and respond before they develop into larger problems. Liquid cooling can introduce variables such as temperature, flow, pressure, equipment state, fluid condition, and leak status. The instrumentation required for those variables depends on the chosen architecture. Controls work can therefore become a meaningful part of the cooling transition even when mechanical equipment dominates the initial budget. Operators need to understand which conditions require alarms, investigation, automatic response, or intervention. Transition funding should recognize this integration instead of assuming an existing monitoring environment automatically understands the new thermal system.
Failure Planning Should Follow the Heat Path
Failure analysis becomes more useful when it follows heat through the applicable cooling chain. A pump problem, valve issue, control malfunction, sensor failure, or upstream cooling problem can produce different consequences. The outcome depends on architecture, operating state, load, redundancy, and the behavior of unaffected cooling components. Some events may allow operation to continue, while others may require intervention. Generic failure assumptions therefore cannot replace engineering analysis of the selected cooling design. The transition budget should support the work needed to understand credible failure paths and define appropriate responses.
Cooling failures do not create identical response times across every compute environment. Available intervention time depends on the system, connected hardware, operating load, remaining cooling paths, and control behavior. Engineering and commissioning should therefore establish relevant response characteristics for the actual deployment. This information can influence alarms, automated actions, escalation procedures, and workload response. Testing may also expose a need for changes in controls or operating procedures before production workloads depend on them. Cooling transition risk includes this preparation because normal cooling capacity alone does not describe behavior during abnormal conditions.
Redundancy Has to Work in Practice
Duplicate equipment on a drawing does not automatically prove that usable redundancy exists under every intended operating condition. Remaining cooling components must be able to support the required function when another component becomes unavailable. Controls, valves, isolation, and operating sequences can determine whether that transition works as intended. Relevant scenarios should therefore receive appropriate verification during commissioning. Findings can lead to changes in instrumentation, logic, configuration, or operating procedures. Budgeting for this verification connects resilience spending with demonstrated behavior rather than equipment count alone.
An effective failure strategy should avoid treating every cooling alarm as an identical operational event. Some alarms can indicate a component problem while adequate cooling remains available elsewhere. Other conditions may signal a meaningful reduction in the ability to remove heat. Operators need enough context to distinguish between those states. Escalation procedures should also identify the team capable of acting on the relevant part of the thermal path. Better alarm design supports appropriate intervention without making every abnormal reading a reason for unnecessary compute interruption.
Monitoring Should Support Decisions
Collecting more cooling data does not automatically improve operational control. Teams need measurements that help them understand system state and make practical decisions. Useful information can include temperatures, flow, pressure, equipment status, and alarms where those variables matter to the architecture. Monitoring should also make ownership clear so abnormal conditions reach the right operational team. Data without context can increase noise while leaving the underlying thermal condition difficult to interpret. Cooling transition budgets should therefore fund observability that supports decisions rather than instrumentation for its own sake.
Thermal behavior can change as workloads, equipment condition, valve positions, filtration, and maintenance states evolve. Historical data can help teams distinguish sudden events from changes that develop gradually. This information can support troubleshooting and maintenance planning after commissioning has ended. The project should therefore decide which operating data needs to remain accessible during the cooling lifecycle. Data retention and monitoring tools carry costs that should be visible in the transition plan. Their value comes from helping operators understand how the installed thermal system actually behaves.
Trends Can Reveal Developing Constraints
An isolated alarm shows that a configured condition occurred at one point in time. Trend information can provide additional context about how the system reached that condition. Operators may then investigate developing issues before they materially restrict cooling capability. The usefulness of this approach depends on appropriate measurements and sensible interpretation rather than collecting unlimited data. Engineering teams should identify which variables provide meaningful insight into the selected cooling architecture. Transition planning can then include the instrumentation and operational processes required to use those variables effectively.
Actual operating behavior can also inform later capacity decisions. Teams considering more compute can examine how existing distribution and heat-rejection paths behave under current loads. This evidence does not replace engineering analysis, but it gives that analysis a stronger operational foundation. Without suitable monitoring, teams may know nominal design capability while remaining uncertain about practical expansion flexibility. Additional investigation may then be required before another deployment can proceed. Observability therefore supports future optionality as well as day-to-day cooling operations.
Cooling Readiness Can Affect Compute Timing
AI hardware becomes useful only when supporting infrastructure can sustain its operation. Hardware delivery and usable compute availability can therefore occur at different times when cooling preparation remains incomplete. Engineering, piping, controls, testing, commissioning, and operating preparation can all influence that gap. These activities follow dependencies that cannot always be compressed simply because hardware arrives earlier than expected. A budget focused primarily on compute procurement can hide this timing exposure. Cooling transition risk gives leadership a way to connect thermal readiness directly with the schedule for usable capacity.
A thermal-readiness milestone can define what the cooling architecture should demonstrate before hardware becomes dependent on it. Requirements may include completed connections, loop preparation, controls, monitoring, functional testing, and operating procedures. The exact milestone should follow the selected architecture and deployment plan. This distinction separates hardware that has physically arrived from hardware that can progress toward dependable operation. Budget owners can then identify which infrastructure dependency is holding back deployment. Readiness becomes an evidence-based project state rather than an assumption attached to the delivery schedule.
Early Delivery Can Create New Pressure
Receiving compute earlier than planned does not automatically create an economic advantage. Hardware may need staging when the thermal environment cannot yet accept it. Teams can also face pressure to accelerate infrastructure work and reduce the time available for controlled testing. A transition reserve gives leadership options for justified acceleration without treating commissioning discipline as expendable. Additional engineering or alternative sequencing may sometimes improve the usable-capacity date. The budget should support those choices only when they produce a credible improvement in readiness.
Several compute deployments can depend on the same portion of a cooling architecture. Shared distribution, controls, heat exchange, pumping, or heat rejection can therefore affect more than one installation sequence. An unresolved common dependency may delay several groups of hardware even when their rack-level cooling is ready. Budget owners should identify these shared elements because resolving one bottleneck can have a broad deployment effect. Progress should not be measured only by the number of cooling components installed. The important measure is whether the applicable thermal path can support the compute scheduled to use it.
Schedule Risk Can Become Cost Risk
A cooling-related delay does not require a hardware failure to create financial exposure. Compute can remain unavailable while teams resolve an interface, repeat testing, modify controls, or complete thermal work. Project resources may remain engaged longer, while temporary infrastructure can stay in service beyond its intended period. Later deployment activities can also become compressed as teams attempt to recover schedule. These effects can occur even when every major component ultimately performs correctly. Cooling transition risk captures this timing exposure more clearly than a contingency focused only on failed equipment.
Pressure to recover deployment time can encourage teams to accept temporary thermal arrangements. Such decisions can be reasonable when their purpose, limits, maintenance needs, and retirement conditions remain explicit. Risk increases when temporary arrangements become normal operation without deliberate lifecycle review. Future teams can then inherit complexity whose original purpose is no longer obvious. Transition budgets should track temporary measures closely enough that leadership can see the obligation accompanying them. This discipline protects future thermal work from disappearing merely because the immediate deployment milestone was achieved.
Usable Capacity Needs One Shared Definition
Different project teams can reach their own readiness milestones at different times. Procurement may confirm hardware availability while mechanical teams confirm installation and controls teams confirm integration. Operations can still require procedures, documentation, and verified support conditions before sustained use begins. Compute becomes usable only when enough of these requirements overlap for the hardware to operate as intended. A cooling transition budget makes unresolved thermal work visible during that process. Leadership can then distinguish between delivered compute, installed compute, commissioned compute, and capacity that is genuinely ready for use.
A transition reserve should not remain static from project approval through operational handover. Its purpose changes as engineering replaces assumptions with verified conditions. Known work can move into committed project scope, while unresolved interfaces remain protected by the risk allocation. Commissioning should retire additional uncertainty as system behavior becomes demonstrated rather than assumed. Operational preparation can close risks related to ownership, procedures, documentation, and maintenance. The budget becomes more useful when it follows this risk retirement instead of behaving like one permanent contingency amount.
Unused Risk Capital Should Be Released
A transition allowance needs an endpoint as well as a reason for existing. Leadership can release portions once major interfaces are validated and relevant commissioning findings are closed. Maintenance procedures, operational ownership, and temporary configurations should also reach defined states before final release. This creates a financial signal that technical uncertainty has genuinely declined. It also reduces pressure to spend remaining contingency simply because the project still has access to it. Future cooling changes can establish a new risk allowance when they introduce another meaningful architectural transition.
The most important cooling decision may concern hardware that has not yet been selected. Compute refreshes can alter thermal interfaces, fluid requirements, flow conditions, controls, and residual air-cooling needs. Supporting infrastructure should therefore avoid unnecessary constraints on future hardware choices where practical. Unlimited flexibility would waste capital, so the objective is not to design for every imaginable configuration. The better goal is to preserve adaptability at interfaces where future changes would otherwise cause significant disruption. Cooling transition risk can help fund that practical optionality without turning uncertain future requirements into immediate overbuilding.
Adaptability Belongs at Key Interfaces
Distribution branches, connection points, isolation, controls, monitoring, and service access can determine how difficult a later cooling change becomes. Interfaces that teams can isolate and modify create more practical upgrade paths. Deeply embedded shared components can be harder to change once operating compute depends on them. Budget reviews should therefore examine where the design intentionally creates changeable boundaries. This approach focuses capital on useful adaptability rather than unused equipment. Future engineering teams then gain practical places to modify the thermal architecture without reopening every layer of the cooling chain.
Future flexibility also depends on whether technicians can physically reach the equipment that may require modification. Piping, valves, distribution equipment, sensors, and heat exchangers need suitable access for their intended maintenance model. Installation can appear simple before racks, cabling, and supporting infrastructure fill the surrounding space. Later replacement may become much harder when the same area supports active compute. Planning service paths early can therefore reduce future disruption without requiring speculative equipment purchases. Cooling transition risk should consider maintainable physical geometry alongside nominal thermal capability.
Controls Need Room to Evolve
Future cooling configurations can introduce equipment states that the original control architecture did not need to understand. A mechanically simple expansion may become difficult if controls require extensive reengineering around existing logic. Clear control boundaries can reduce that problem and make future modifications easier to understand. Documentation should explain relationships between sensors, alarms, equipment states, and automated responses. Teams do not need to predict the exact hardware that will arrive later to create understandable control architecture today. Transition spending on this layer can preserve operational flexibility as effectively as some physical infrastructure investments.
Leadership can preserve future options without installing every future cooling component in advance. Space, connection strategy, controls, isolation, and documentation can create readiness for later expansion. This distinction matters because future compute plans may change before procurement begins. Installing unnecessary equipment early can consume capital without guaranteeing that it will match the eventual thermal requirement. A transition-risk allocation can protect defined future conversion work while immediate capital supports committed compute. Budgeting becomes stronger when it separates readiness to expand from money already spent on expansion.
Upgrade Decisions Need Defined Gates
A thermal upgrade path works better when it contains explicit decision points. Teams can review whether distribution remains adequate before another compute deployment proceeds. They can also decide whether temporary equipment should remain, change, or retire. Observed operating conditions and confirmed hardware requirements should guide those decisions. This approach reduces pressure to commit future cooling capital before enough technical information exists. Decision gates also reduce the opposite risk of waiting until new hardware arrives before confronting a known thermal constraint.
An interim cooling arrangement should not remain indefinitely simply because removing it receives less attention than deploying new compute. Each temporary element should have a technical reason to remain after the condition that created it changes. Some components may prove useful enough to justify permanent integration. Others may create maintenance and control complexity without continuing to provide meaningful value. Review points can make that distinction explicit before temporary architecture becomes invisible within normal operations. The cooling transition budget should include the work required to make these lifecycle decisions real.
Overbuilding Is Not the Same as Readiness
Preserving future choice does not require installing the maximum possible cooling configuration. Future thermal requirements should receive capital when credible compute plans justify them. Connection strategy, space, controls, isolation, and upgrade paths can preserve flexibility without unnecessary equipment. This keeps immediate spending tied to committed capacity while protecting sensible options for later conversion. The distinction also helps leadership challenge cooling investments that rely only on uncertain future demand. Cooling transition risk should support adaptability, not become an argument for speculative infrastructure.
A cooling transition reserve should not permanently cover every later hardware generation. Once the current transition reaches defined operational maturity, its remaining risk allocation can close. A future compute change may create another thermal transition with different interfaces and constraints. That change can receive a new assessment based on the architecture and requirements known at that time. This approach keeps financial exposure tied to identifiable technical change instead of turning it into a permanent budget category. Cooling transition risk remains useful because each allowance has a clear purpose and lifecycle.
Cooling Transition Risk Belongs in the Investment Model
It becomes useful to C-level planning when it moves from an engineering concern into capital governance. The purpose is not to imply that cooling costs are inherently unpredictable. It separates defined thermal spending from uncertainty created by changing the operating architecture. Base capital can fund equipment and work already established by the approved design. A transition allocation can cover unresolved integration, commissioning, coexistence, controls, and adaptation requirements within defined boundaries. Leadership then gains visibility into why additional thermal spending exists instead of seeing one broad infrastructure contingency.
A transition reserve loses value when it becomes a place for every infrastructure overrun. Eligible spending should relate directly to moving the cooling environment toward the state required by the approved deployment. Integration, commissioning, temporary arrangements, and justified corrective work can fit that purpose. Unrelated improvements and discretionary enhancements should remain outside the category. Clear boundaries allow leadership to see which thermal uncertainties actually consumed the reserve. The budget then behaves like managed exposure rather than an unrestricted pool of project capital.
Every Use Should Explain What Changed
Material use of the transition allocation should identify the technical assumption or condition that changed. Commissioning may reveal a control issue, while installation can expose an access or routing constraint. Operating preparation can uncover a maintenance requirement that earlier project stages had not resolved. Hardware changes can also alter the cooling interface expected at the rack. Recording these causes helps leadership distinguish reasonable transition discovery from recurring planning weaknesses. Repeated requirements can eventually move into standard project scope rather than remaining permanent contingency items.
Cooling transition risk changes as a project moves from design through installation and commissioning. Early uncertainty can center on architecture, routing, interfaces, coolant requirements, and existing infrastructure constraints. Installation replaces some assumptions with physical evidence while creating new integration questions. Commissioning should then retire uncertainty around controls, monitoring, flow behavior, alarms, and other tested system functions. Handover shifts attention toward maintenance, documentation, ownership, and operating procedures. Financial governance should follow this progression instead of treating transition risk as one static amount.
Finance and Engineering Need the Same Milestones
A structured transition budget can improve the conversation between finance and engineering. Engineering can identify which assumptions remain open and what evidence will close them. Finance can assess whether the reserve still corresponds to unresolved technical exposure. Both groups can then distinguish readiness work from spending that belongs elsewhere in the project. Later deployments also benefit because recurring requirements become easier to recognize. Cooling transition risk becomes a bridge between technical uncertainty and capital governance rather than a request for unlimited contingency.
The transition reserve should become smaller as uncertainty disappears. Engineering resolves design questions, installation confirms physical conditions, and commissioning demonstrates system behavior. Operational handover can close further questions about maintenance, ownership, alarms, and documentation. Remaining capital should correspond to identifiable unresolved exposure rather than the original level of uncertainty. This creates pressure to close technical questions instead of carrying them indefinitely. It also gives leadership a clear financial signal that the cooling architecture is moving toward operational maturity.
Conclusion: Budget the Transition, Not Just the Equipment
An AI infrastructure budget can account carefully for compute hardware and still remain incomplete. The gap appears when it assumes the cooling architecture can change without meaningful transition work. Exposure can arise through interfaces, hybrid operation, controls, commissioning, maintenance, temporary arrangements, and future modification. Separating that exposure into a cooling transition-risk line makes the difference between thermal equipment and thermal readiness visible. Projects can then retire uncertainty through engineering, testing, documentation, and operating preparation. The budget becomes stronger because it recognizes the work required to turn cooling capability into usable support for compute.
The strongest budgets will not attempt to predict every future valve, control adjustment, maintenance requirement, or cooling configuration. They will identify where uncertainty remains and define the evidence needed to resolve it. Capital can then remain proportional to the technical exposure rather than expanding into a generalized contingency. This approach also strengthens the relationship between infrastructure readiness and compute readiness. Delivered hardware should not automatically be treated as usable capacity when the supporting thermal path remains unfinished. Financial discipline improves when the project distinguishes equipment ownership from the ability to operate that equipment as intended.
Cooling transition risk describes the financial consequence of changing thermal architecture without assuming every AI deployment will become difficult. Some environments may need limited modifications, while others can require deeper changes across distribution, controls, commissioning, and maintenance. Leadership needs those differences visible before cooling becomes an unplanned constraint on deployment. A dedicated budget line provides room to manage legitimate transition work while maintaining pressure to close technical uncertainty. Unused capital can return once the cooling system reaches its defined operational state. The AI infrastructure budget is therefore more complete when it funds both the required cooling capability and the controlled transition needed to reach it.