 Skip to content

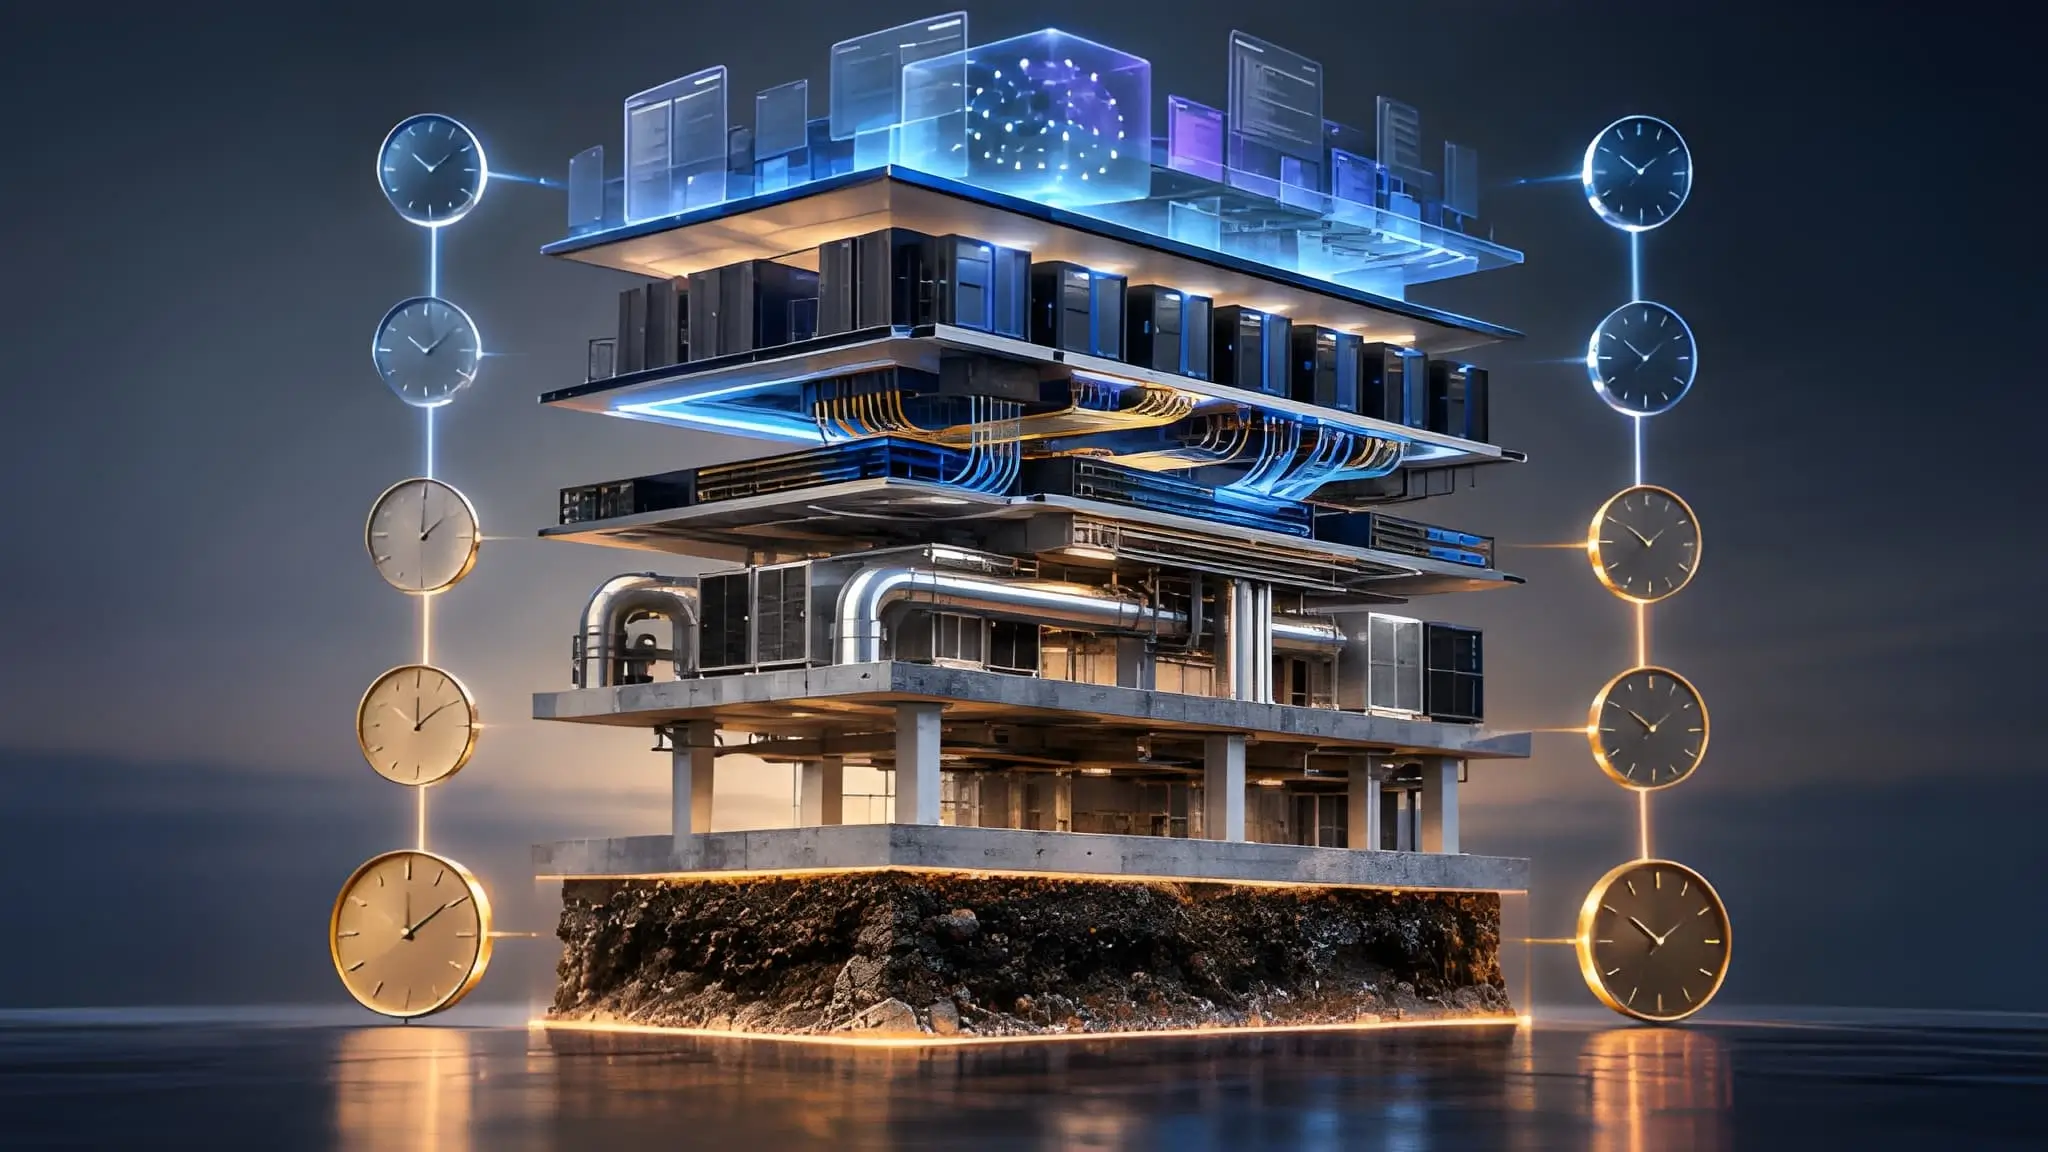
A building can remain standing while almost everything that once justified its design changes, and that simple fact is becoming harder to ignore as computing workloads evolve faster than physical infrastructure can change. The economic life of an AI infrastructure asset therefore cannot rely on viewing the building as one indivisible investment. A site can remain strategically useful while its internal architecture becomes constrained, while a network pathway can lose relevance before the surrounding structure requires replacement. Software-driven workload changes can alter requirements for computing equipment, cooling, networking and physical configuration, creating downstream constraints that may eventually affect the physical infrastructure supporting those workloads. The seven-layer asset stack provides a way to examine those clocks separately and understand where value survives, where it decays and where mismatches between them can turn adaptability into a financial question.

The underlying idea does not assume that every layer follows a fixed expiration date, because service life depends on design, maintenance, operating conditions, technology requirements and the ability to modify the surrounding architecture. Instead, each layer has an economic clock that describes how long its existing configuration remains useful for the workloads it must support. Location sits at the slowest end because land, access relationships, network adjacency and market positioning can remain relevant through multiple generations of technology. Software sits at the fastest end because models, frameworks, deployment methods and workload behavior can change while the physical infrastructure beneath them remains substantially unchanged.
Location Is the Longest-Duration Layer
The first layer is the site itself: the physical location, its relationship with communications routes, its access to relevant markets and the surrounding infrastructure that makes a particular piece of land useful for digital infrastructure. Unlike most engineered components above it, a site’s geographic position does not become technologically obsolete simply because a new generation of processors, networking equipment or software arrives, although surrounding infrastructure, market requirements and development conditions can change its usefulness. A well-positioned site can continue supporting different infrastructure configurations when those conditions remain favorable.
A site near established network routes can remain relevant to successive computing configurations because connectivity and access to network ecosystems remain important considerations in data-center site selection. That relationship creates an unusual connection between physical permanence and economic adaptability because the asset does not need reconstruction to participate in a new technology cycle. The site instead provides the fixed geographic reference around which successive infrastructure configurations can develop as technology and workload requirements change.

The Site Outlives the Architecture
A site gains value through relationships that sit outside the land itself, including proximity to network ecosystems, routes into important markets, transport access and the surrounding development pattern. Those relationships can deepen over time as additional infrastructure accumulates around the location, creating a form of geographic optionality that a building component cannot easily reproduce elsewhere. Network-rich locations illustrate this principle particularly clearly because physical fiber pathways connect a site to broader digital ecosystems and can expand the range of workloads that the location can support. A site that maintains connections to multiple pathways can accommodate changes in workload sensitivity without requiring changes to the underlying geography. The same principle applies to market access because the value of proximity depends on what the surrounding digital economy needs rather than on the original purpose for which the site was selected.
The important point is not that every well-connected site automatically appreciates, because location value remains dependent on changing demand, regulation, surrounding infrastructure and the ability to use the site effectively. The stronger thesis is that location can accumulate relevance while most technical layers primarily consume relevance as their assumptions age. A fiber route can change, network equipment can leave service and software can move to another configuration, but the underlying geographic relationship remains available for another deployment if the site still satisfies the required conditions. This makes site selection different from a conventional equipment procurement decision because the decision establishes a physical position from which later technology generations must operate.
Why Site Selection Becomes a Duration Bet
The financial significance of location appears when the rest of the stack starts changing faster than the site itself. A physical structure may require modification when equipment geometries, cooling requirements or service arrangements change, while network equipment can often undergo refresh without replacing the geographic position or the entire building that supports it. None of those changes necessarily invalidates the site because the geographic layer can continue supporting another configuration. The site therefore acts as the anchor around which the economic life of every other layer undergoes repeated reassessment. This makes site selection more than an early construction decision, since it establishes the range of future architectures that can plausibly occupy the same location. A site with strong external relationships gives future investment more paths to adapt, while a constrained site can force every later generation to work around conditions that operators cannot redesign economically.
That optionality becomes especially important when workload requirements become less predictable because the economic value of a site increasingly depends on how many different infrastructure configurations it can support over time. A location that works only for one narrowly defined deployment may perform well under its original assumptions but lose relevance when the workload mix changes. A location that preserves access to multiple network paths, markets and future development possibilities can continue serving new configurations without requiring anyone to revisit the geographic decision. The difference between physical permanence and technological adaptability therefore begins at the site layer, where the asset can remain useful even as the architecture above it changes repeatedly. This also explains why current site-selection discussions increasingly consider connectivity, market access, expansion potential and surrounding infrastructure alongside the basic question of whether construction can occur.
The Shell Remembers Every Generation It Has Hosted
The third layer is the facility shell, whose economic usefulness depends not only on structural condition but also on whether its loading capacity, clearances, equipment zones, service routes and physical arrangement can accommodate changing infrastructure requirements. A shell includes the structural frame, floor system, clearances, equipment zones, service routes, loading assumptions and physical arrangement that determine what teams can actually install inside the building. Concrete does not understand a processor generation, but the structure still carries the consequences of every processor generation that has occupied it because each hardware configuration imposes requirements on weight, geometry, access, cooling distribution and maintenance space.
A previous deployment can leave physical constraints because changes to equipment arrangements, service routes and supporting systems can affect the configuration available to subsequent technology generations. Structural loading must account for both total and concentrated loads, while equipment movement introduces additional demands that can matter during installation and replacement rather than during steady operation. The shell consequently retains the physical consequences of earlier infrastructure decisions, and those consequences can influence whether a future technology configuration fits naturally, requires modification or creates additional engineering constraints.
Structural Memory Becomes a Technology Constraint
A building designed around one equipment geometry does not automatically become adaptable merely because empty space surrounds the existing racks, since the usable envelope also includes structural capacity, pathways, service clearances distribution arrangements hidden beneath that apparent openness. Changes in rack form can alter how loads reach the floor, while changes in cooling architecture can introduce piping, manifolds, distribution equipment and service zones that never formed part of the original layout. The structural question therefore moves beyond whether the slab can carry a replacement rack and toward whether the entire path from delivery to final installation can accommodate the new equipment without creating conflicts elsewhere in the building. High-performance computing programs have long recognized that computing systems and their supporting infrastructure must receive joint planning because floor loading, cooling, equipment dimensions and facility configuration interact rather than operate independently.
That accumulated record can create stranded value even when the underlying structure remains serviceable, because the cost of adapting a shell can rise when several independent constraints require resolution at the same time. A rack change may require floor reinforcement, which may interfere with underfloor distribution, while a different cooling arrangement may require new service pathways that compete with existing electrical or network routes. The building can therefore reach a point where each individual modification appears manageable but the combined intervention begins to undermine the economic case for retaining the original configuration. Current work on liquid-cooled infrastructure illustrates this broader problem because new cooling approaches can affect not only the cooling plant but also the white-space arrangement, piping, equipment interfaces and commissioning process.
The Fabric Between the Clocks
The fifth layer is the network fabric, and its role becomes clearer when engineers separate it from the equipment that generates and consumes traffic. Fiber pathways, physical routes, termination spaces, distribution architecture and switching relationships create the connective tissue through which computing workloads move between systems and locations. Network technology generally undergoes more frequent technological change than the underlying building structure, while physical pathways can remain useful across multiple generations of active equipment when their capacity, routing and accessibility remain suitable. This gives the network layer an intermediate economic clock that can preserve value through several technology cycles while still becoming restrictive when its physical topology no longer supports the architecture that newer workloads demand.
NIST describes network technologies as undergoing fundamental changes while emphasizing that future network infrastructure requires greater agility as scale and complexity evolve, which captures the unusual position of the fabric between long-lived physical infrastructure and rapidly changing digital workloads. The network therefore functions as an intermediate layer between long-lived physical infrastructure and changing computing requirements because its physical pathways can remain in service while active equipment and workload patterns around them evolve.
Fiber Pathways Age Differently From Models
The physical network layer follows a different replacement logic from the software layer because a pathway can retain value even when the equipment using it changes repeatedly. Conduit, fiber routes, distribution spaces and physical separation can provide continuity across hardware generations, but that continuity depends on whether the pathway remains accessible, expandable and compatible with the topology that the next architecture requires. A network fabric that served one traffic pattern can become difficult to adapt if new requirements demand different physical routes, additional redundancy or tighter relationships between compute clusters and their supporting systems. The challenge involves more than bandwidth because topology, latency behavior, path diversity, equipment placement and serviceability can all affect whether the fabric continues supporting the architecture above it.
The fabric becomes financially significant when network decisions become embedded in the physical design and cannot undergo independent refresh without disturbing adjacent layers. A cable can undergo replacement more readily than a slab, but a pathway may still prove difficult to alter once it passes through constrained structural zones, shared service corridors or densely occupied technical areas. That makes network architecture an intermediate commitment rather than a purely replaceable technology purchase, because the physical organization of the fabric determines how easily teams can introduce future equipment. The usefulness of that arrangement depends on whether the network can accommodate changes in equipment, topology and traffic requirements without requiring major changes to the surrounding physical infrastructure.
When Software Starts Dictating Concrete
The seventh layer is software, including models, frameworks, orchestration logic and workload behavior that ultimately determines what the physical infrastructure must support. Software occupies the fastest-changing layer in the stack because models, frameworks, deployment methods and workload behavior can change without requiring teams to replace the underlying physical infrastructure. That speed creates a growing dependency between software-driven workload requirements and physical infrastructure because changes in computing characteristics can expose limitations in equipment capacity, thermal arrangements, networking and physical configuration. Software does not directly design a building, but workload characteristics can influence equipment selection and operating conditions that subsequently affect cooling, networking, spatial arrangement and other physical requirements.
Workload Volatility Becomes a Physical Design Problem
A workload does not remain an abstract software object once its execution pattern begins imposing requirements on physical systems, because computation produces heat, traffic, equipment loading and operating behavior that the surrounding infrastructure must accommodate. Training and inference can place different demands on systems, while changes in model architecture can alter the relationship between compute resources, memory, networking and cooling requirements. Current research into liquid-cooled commissioning illustrates the issue because AI workloads can create synchronized changes in IT load that commissioning teams must consider when they validate the infrastructure supporting them. Software behavior can therefore influence the physical testing regime that teams need before a system enters operation, even though the software itself remains several layers above the equipment under test.
The inversion becomes more consequential when software-driven workload changes propagate downward through several layers at once, because each layer follows a different replacement cycle. A new framework can change how compute teams schedule workloads, which can change equipment utilization, which can change thermal behavior, which can alter cooling requirements and eventually expose structural or spatial limitations. None of those changes necessarily makes the original building defective, but they can reduce the range of workloads that the building can accommodate without intervention. The U.S. Department of Energy has noted that computing requirements can remain difficult to specify precisely in advance while also emphasizing the need to incorporate flexibility and scalability into long-lived infrastructure decisions. That principle becomes increasingly relevant when software evolves faster than the physical systems underneath it because uncertainty no longer remains confined to the equipment procurement stage.
The Stack Starts Running Backward
The traditional sequence of infrastructure planning often moves from the physical site toward the computing workload, but rapidly changing AI systems increasingly force requirements back down the stack from software toward structure. That reverse pressure appears whenever a workload requires a different thermal interface, equipment arrangement, network topology or service configuration than the building originally anticipated. Cooling research now treats advanced systems as infrastructure that must evolve alongside high-power computing rather than as an isolated mechanical subsystem, while current commissioning work shows that workload behavior can affect how teams test the supporting systems. The implication for the seven-layer asset stack is that the fastest layer can create requirements for the slowest layers without sharing their replacement clock. Software may change without physical disruption, but the consequences of that change can become expensive once they reach components that require construction, structural intervention or reconfiguration.
The seven-layer stack becomes most useful when teams consider these different clocks together rather than evaluate them as separate procurement categories. Location can remain useful while the shell becomes constrained, the network can remain serviceable while its topology becomes difficult to adapt, and software can remain deployable while the physical environment beneath it becomes unsuitable for the workload it needs to run. The economic life of the overall asset therefore does not equal the average life of its components because one restrictive layer can limit the value of several longer-lived layers around it. Research into existing high-performance computing environments repeatedly points toward the interaction between computing systems and supporting infrastructure, reinforcing the need to consider those dependencies before procurement rather than after equipment arrives. The stack therefore requires evaluation as a sequence of clocks whose mismatches can either create flexibility or trap capital.
The Middle Layers Where Value Gets Stuck
The middle of the seven-layer stack contains the systems that translate a physical structure into a functioning computing environment, and this is where adaptability becomes hardest to preserve. Layers three, four and five connect the shell to the network and determine whether the infrastructure can accommodate changes without forcing a wholesale reconstruction. The structural layer establishes what can physically fit, the thermal layer determines how the resulting heat can be managed, and the network layer determines how the resulting computing resources communicate.
Each layer can remain operational while another becomes restrictive, creating a condition in which the asset appears healthy when teams assess each component separately but becomes less useful when they assess the complete system. Current industry research describes the transition toward high-density AI infrastructure as a complex modernization problem because existing infrastructure can carry legacy assumptions that do not align neatly with newer workloads. The financial consequence is that value can become trapped in the middle of the stack even when the site below remains attractive and the software above remains commercially important.
Thermal, Structural and Network Decisions Interlock
The thermal layer illustrates the problem particularly well because cooling stops functioning as an isolated mechanical system once designers physically integrate it with computing equipment. Direct liquid cooling creates a tighter relationship between IT equipment and the supporting cooling infrastructure, so changes in the computing environment can affect the design, operation and testing of systems outside the rack itself. Recent industry analysis notes that operators increasingly need cooling systems that can accommodate multiple hardware technology cycles rather than serve a single generation of equipment. That requirement changes the economic question from whether a cooling system can support today’s hardware to whether its interfaces can survive successive equipment changes without forcing operators to replace the surrounding infrastructure.
This interdependence makes the middle of the stack different from both ends because neither permanence nor rapid replacement provides an easy escape route. The site can remain useful without changing its geographic position, while software can change without requiring anyone to reconstruct the building, but thermal, structural and network systems often require physical intervention before they can accommodate a materially different architecture. A cooling loop can remain functional yet become poorly matched to new equipment, a floor can remain structurally sound yet become difficult to use efficiently, and a network pathway can remain intact yet constrain the topology that a new computing configuration needs. The current transition toward liquid-cooled AI infrastructure demonstrates why these dependencies matter because commissioning teams may need equipment that reproduces the electrical and thermal behavior of the intended workload.
Where Stranded Value Actually Forms
The middle-layer trap becomes more visible when an upgrade cannot occur independently of neighboring systems. Engineers may find network equipment straightforward to replace until pathway capacity or physical routing limits the new topology, while thermal equipment may appear straightforward to change until service clearances or structural arrangements block the required configuration. Structural modifications can then create additional work for thermal and network systems because crews must move pathways, access zones and equipment positions together. This produces a chain of dependencies in which a seemingly small technology refresh can become a broader infrastructure project. The longer the underlying asset remains in operation, the more generations of these decisions can accumulate, making the original configuration increasingly difficult to separate from the building itself.
Stranded value does not necessarily appear when a component stops functioning, because infrastructure can remain technically operational while losing the ability to support the workloads that justify its continued use. This matters especially for long-lived buildings because a shell can preserve physical integrity while the systems inside it gradually narrow the range of viable configurations. The resulting problem resembles a compatibility constraint rather than a conventional failure, with each new technology cycle requiring more adaptation until operators find the accumulated intervention difficult to justify. Research into AI-era infrastructure increasingly emphasizes the challenge of integrating new high-density computing into existing environments because legacy infrastructure and newer cooling requirements do not always align cleanly. The issue therefore extends beyond replacement cost to the interaction among replacement cost, disruption, commissioning complexity and the residual value of systems that must remain in place.
Some Layers You Can Swap, Some You Have to Live With
The seven-layer stack becomes financially useful when investors consider replacement according to the degree of reversibility available at each layer. Operators can normally change software without touching the building, while teams can often refresh active network equipment without replacing the physical pathways that carry it. Other systems sit further toward the irreversible end because changes can require construction, shutdowns, redesign or extensive commissioning. The question of modularity therefore does not depend only on whether a component can come out of the system, because the more relevant question asks whether teams can replace it without forcing changes across several other layers. A component may look easy to unbolt yet offer little practical modularity if crews must reconstruct extensive infrastructure around it. Infrastructure teams therefore need to evaluate adaptability through interfaces, access and dependencies rather than through equipment replacement procedures alone.
The Reversible End of the Stack
Software sits closest to the reversible end because teams can often introduce new models, frameworks and orchestration methods without rebuilding the physical environment. Network equipment also offers substantial refresh potential because teams can change active components while portions of the underlying fiber pathway remain in service. Designers can apply the same principle to selected cooling components when they preserve common interfaces and allow equipment from different technology generations to operate within a compatible architecture. Recent analysis of IT-agnostic liquid cooling specifically identifies the need for a common approach that can support multiple overlapping hardware cycles within the life of a building. That requirement captures the essence of modularity because supporting infrastructure retains value when it can absorb equipment changes without tying itself to one generation.
Modularity also depends on whether teams can complete a replacement without creating an unacceptable operational disturbance, since a theoretically replaceable component can still carry significant transition risk. Network teams may need coordinated changes across topology and configuration, while liquid cooling equipment can introduce commissioning requirements that connect the IT load directly to the supporting thermal loop. Current commissioning research shows that liquid-cooled systems require testing methods that reproduce the electrical and thermal behavior of the equipment they will support, which makes replacement more involved than simply exchanging one machine for another. Modularity therefore has both a physical dimension and an operational dimension because the system must remain testable and controllable after the replacement.
The Irreversible End of the Stack
Location and the fundamental shell sit toward the irreversible end because replacing either usually means abandoning the original geographic or structural proposition rather than simply refreshing a component. Operators cannot swap a site in the same way they can swap a software layer, and crews cannot replace a structural frame incrementally without confronting the building that contains it. That does not mean these layers have fixed value or that they inevitably become obsolete, because their usefulness can persist through many generations when their original design assumptions remain compatible with changing requirements. These characteristics give their economic decisions a longer-duration horizon because mistakes at these layers can constrain every later layer. As a physical layer approaches a long service horizon, decision-makers need to understand uncertainty before that layer becomes difficult to modify.
The facility shell therefore represents a commitment that extends beyond the hardware installed inside it at any particular moment. Its clearances, loading assumptions, service pathways and physical geometry establish boundaries that later technology cycles must either accommodate or modify. A shell with greater adaptability can preserve more future options, while a shell optimized tightly around one configuration can embed assumptions that become expensive when the workload changes. Current industry analysis shows that newer AI-oriented requirements are already forcing operators to reassess how existing infrastructure supports higher-density computing and evolving cooling systems. That reassessment does not make older buildings worthless, but it demonstrates why remaining physical life and remaining economic usefulness should not carry the same meaning. The shell can survive for a long time while its ability to host the next generation gradually narrows.
From Lifespan to Layer-span
The seven-layer asset stack changes the question from how long an infrastructure asset will last to how many technology cycles each layer can survive without losing economic usefulness. Lifespan describes the physical endurance of an asset, while layer-span describes its ability to remain compatible with successive generations of requirements. A site may carry value through repeated technology transitions, while teams may replace software many times during the same physical investment period. Between them, structural, thermal and network layers determine whether those two ends can continue operating together without accumulating excessive adaptation costs. An infrastructure investment can therefore retain substantial physical life while possessing limited layer-span if its middle architecture cannot accommodate the next workload cycle. The stronger underwriting approach treats adaptability as a property of the stack rather than as a general characteristic assigned to the building as a whole.
Measuring How Many Cycles the Asset Can Absorb
Layer-span works best as a measure of the number and type of changes an infrastructure layer can accommodate before teams need replacement or major reconstruction. The measure does not require teams to predict the exact hardware or software that will arrive next, because uncertainty itself forms part of the design problem. Instead, the assessment asks whether interfaces remain usable, whether teams can modify physical pathways, whether thermal systems can support different equipment configurations and whether the shell retains enough structural and spatial flexibility for future deployments. Current research into IT-agnostic cooling illustrates this approach by examining how a shared cooling architecture can support multiple overlapping hardware cycles rather than optimizing around a single equipment generation. That approach provides a more durable way to think about infrastructure because it evaluates the ability to absorb change rather than attempting to forecast every change in advance.
The same logic can extend to network and structural planning because both layers benefit when replacement boundaries remain clearly separated from long-lived physical assets. A network pathway has greater layer-span when teams can connect changing active equipment without rebuilding its physical arrangement for every topology change. A structural layout has greater layer-span when it can accept different equipment geometries without requiring extensive modification whenever rack configuration changes. A cooling architecture has greater layer-span when it supports multiple equipment generations without becoming inseparable from the first workload it served. These characteristics create a more useful basis for comparing infrastructure because they reveal where future capital may need to go even when the existing asset remains operational.
The Financial Risk Lives Between the Clocks
The central financial risk emerges when a short-lived workload assumption shapes a long-lived physical layer without sufficient adaptability around it. Software can move quickly, but concrete, pathways and integrated thermal systems move slowly, creating a timing mismatch that can turn an ordinary technology refresh into a capital-intensive infrastructure intervention. That mismatch becomes especially important as AI workloads continue to push infrastructure toward higher-density configurations and more closely coupled cooling arrangements. The current industry environment already shows operators dealing with legacy constraints while attempting to modernize infrastructure for changing workload requirements, making adaptability a practical asset characteristic rather than an abstract design preference. The financial exposure comes from the possibility that capital remains committed to a physical configuration whose useful workload range narrows faster than its physical life expires.
The resulting framework does not call for shorter-lived infrastructure, because long-lived physical assets remain essential to digital infrastructure and can preserve value when designers build them to accommodate change. Instead, it calls for a different way to match investment decisions to the clocks operating inside the same asset, with each layer evaluated according to its own replacement boundary and its dependence on the layers around it. Location remains the slowest commitment, the shell carries the physical memory of previous generations, the middle layers determine adaptability, and software continually introduces new requirements from the top of the stack. The strongest infrastructure therefore does not necessarily mean the structure that lasts the longest; it means the structure that allows the greatest number of meaningful technology cycles to pass through it without forcing unnecessary reconstruction.










