Skip to content
The next AI infrastructure procurement decision may depend on what happens after equipment fails
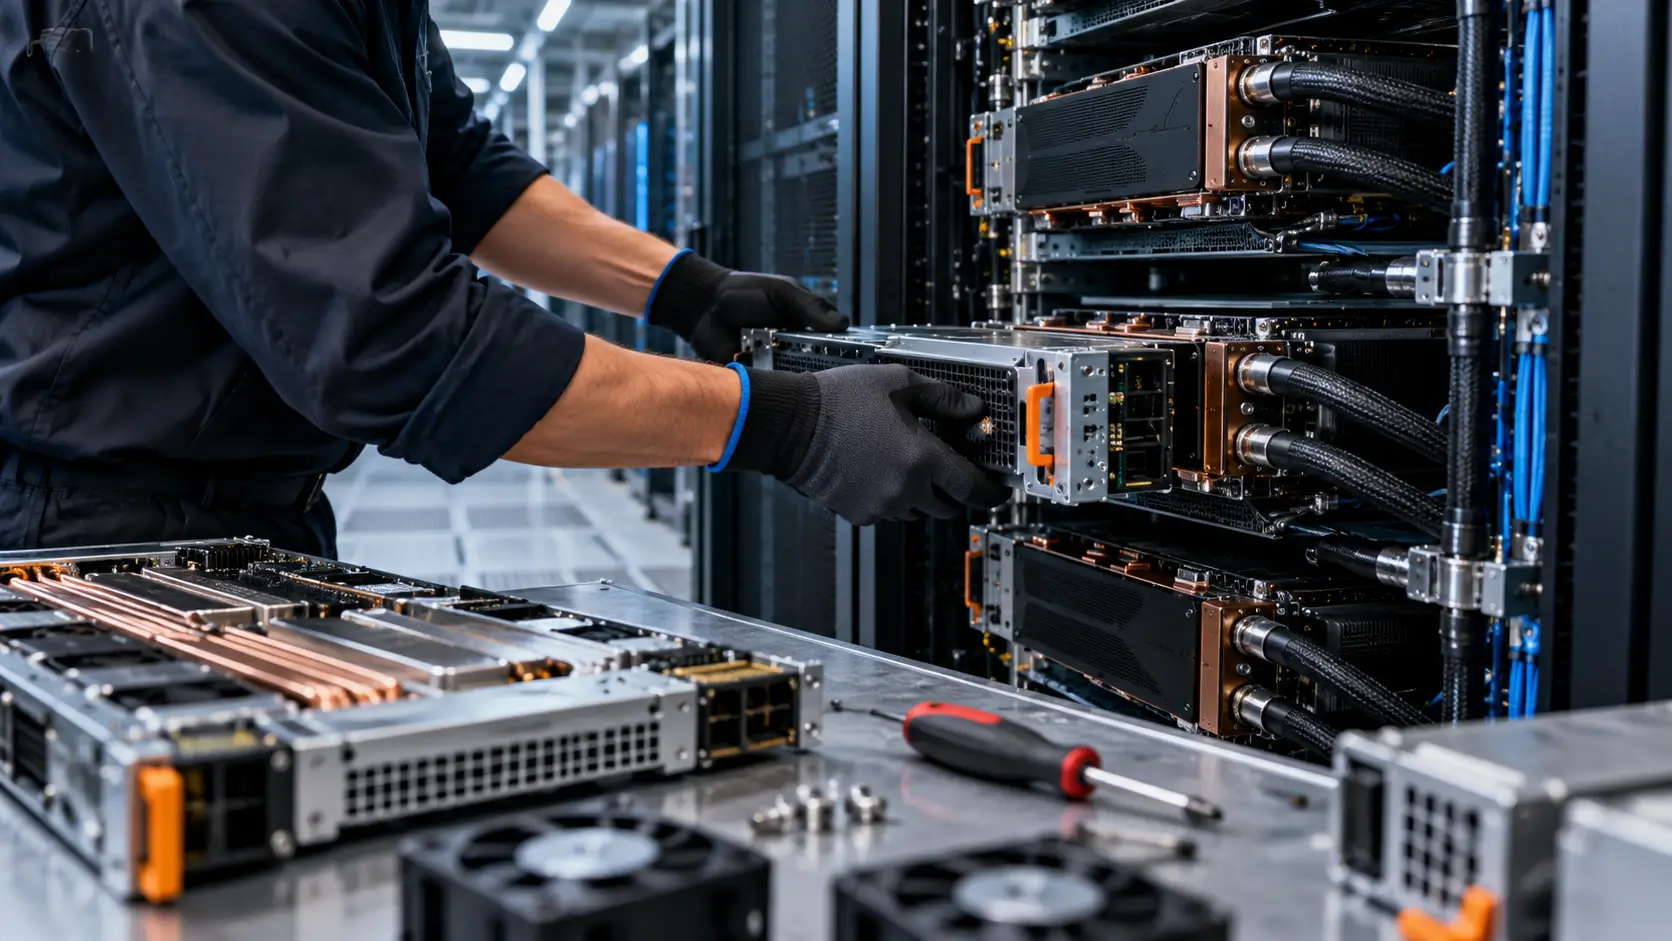
A failed component can turn a productive AI infrastructure investment into an expensive operational problem. The risk grows when replacement parts, compatible hardware or qualified technicians are not immediately available. High-density computing environments depend on interconnected power, cooling, networking and accelerator systems. A fault in one area can affect the availability of other resources. Procurement teams commonly evaluate equipment through acquisition cost, performance specifications, delivery schedules, warranties and service-level commitments. However, these measures do not necessarily reveal how easily technicians can restore a system after a failure. An accelerator server might meet every performance requirement yet present maintenance challenges when technicians cannot isolate a fault or replace the affected part quickly. AI infrastructure procurement should therefore assess both the computing capability equipment delivers and the practical effort required to restore that capability after something goes wrong.
Repairability belongs in the same conversation as performance and availability
The economics of AI infrastructure become more complicated when buyers compare equipment solely through upfront pricing and advertised computing capacity. A lower purchase price may offer an immediate budget advantage, but the calculation changes when routine failures require extensive troubleshooting or specialized intervention. Repairability does not guarantee lower operating costs, and even serviceable systems can require substantial engineering work. However, understanding how equipment can be diagnosed, accessed, repaired and returned to service gives buyers a more complete basis for comparison. Several interconnected systems must function together before installed computing capacity becomes usable capacity. A server awaiting a replacement component can reduce available cluster capacity. Similarly, a cooling-system fault may force operators to restrict workloads even when the accelerators remain functional. Procurement teams should evaluate repair procedures alongside performance benchmarks, availability commitments and lifecycle costs rather than treating maintenance as a separate facilities concern.
A repairability scorecard needs measurable criteria
A meaningful repairability assessment should translate general claims about serviceability into verifiable procurement criteria. Buyers can begin by checking whether telemetry, diagnostic tools and service documentation help technicians identify component failures. They should also determine whether technicians can access replaceable components without dismantling unrelated equipment or taking larger systems out of service. Clear service documentation helps technicians follow consistent procedures, while incomplete instructions can complicate troubleshooting and increase reliance on external support. Parts availability deserves equal attention, including regional inventory, replenishment commitments and compatible replacement components. Procurement teams should establish which repairs qualified in-house technicians can perform and which require specialist intervention. They can then measure the time needed to diagnose a fault, obtain the necessary part, complete the repair and validate the system before production resumes. These measures will not produce one universal score for every equipment category. They can, however, provide a consistent basis for comparing solutions against an operator’s actual requirements.
The hidden cost of waiting for a repair
Repairability becomes especially important when equipment failures affect capacity commitments, workload schedules and service-level agreements. A relatively inexpensive replacement component can create a disproportionate operational burden if its absence prevents an entire server from returning to service. The financial impact depends on the affected workload, available redundancy, cluster architecture and the ability to redistribute jobs. A training workload with sufficient spare capacity may tolerate an isolated server outage. A tightly allocated production environment could instead experience scheduling delays or reduced throughput. Buyers should not assume that every failed accelerator causes an equivalent loss of computing capacity. Workload design and system configuration determine the actual impact. Procurement decisions that ignore repair duration can leave operators with limited visibility into potential capacity shortfalls. Repairability assessments should therefore examine realistic recovery scenarios, including unavailable parts and repairs that require broader system shutdowns. This approach helps buyers evaluate operational exposure without assuming that every hardware failure will disrupt customer-facing services.
Replacement speed matters, but so does the scope of the repair
A useful procurement scorecard should distinguish between replacing a failed part and restoring the wider system. Some components can be serviced independently, while others require shutdowns, additional testing or coordinated work across infrastructure layers. Hot-swappable components can reduce disruption in appropriately designed systems, but they do not guarantee a quick repair. Compatibility requirements, firmware dependencies, diagnostic access and post-repair validation can all influence recovery time. Buyers should ask vendors to document replacement conditions, including restrictions affecting live workloads or redundant configurations. They should also establish whether maintenance procedures preserve the required configuration, security controls and system integrity. These questions become particularly relevant in tightly integrated AI racks, where power, cooling and networking dependencies may limit maintenance options. The objective is not to demand that every component remain replaceable during operation. Instead, buyers need to understand the practical limits of repair before those limits affect production.
Liquid cooling raises the stakes for serviceability
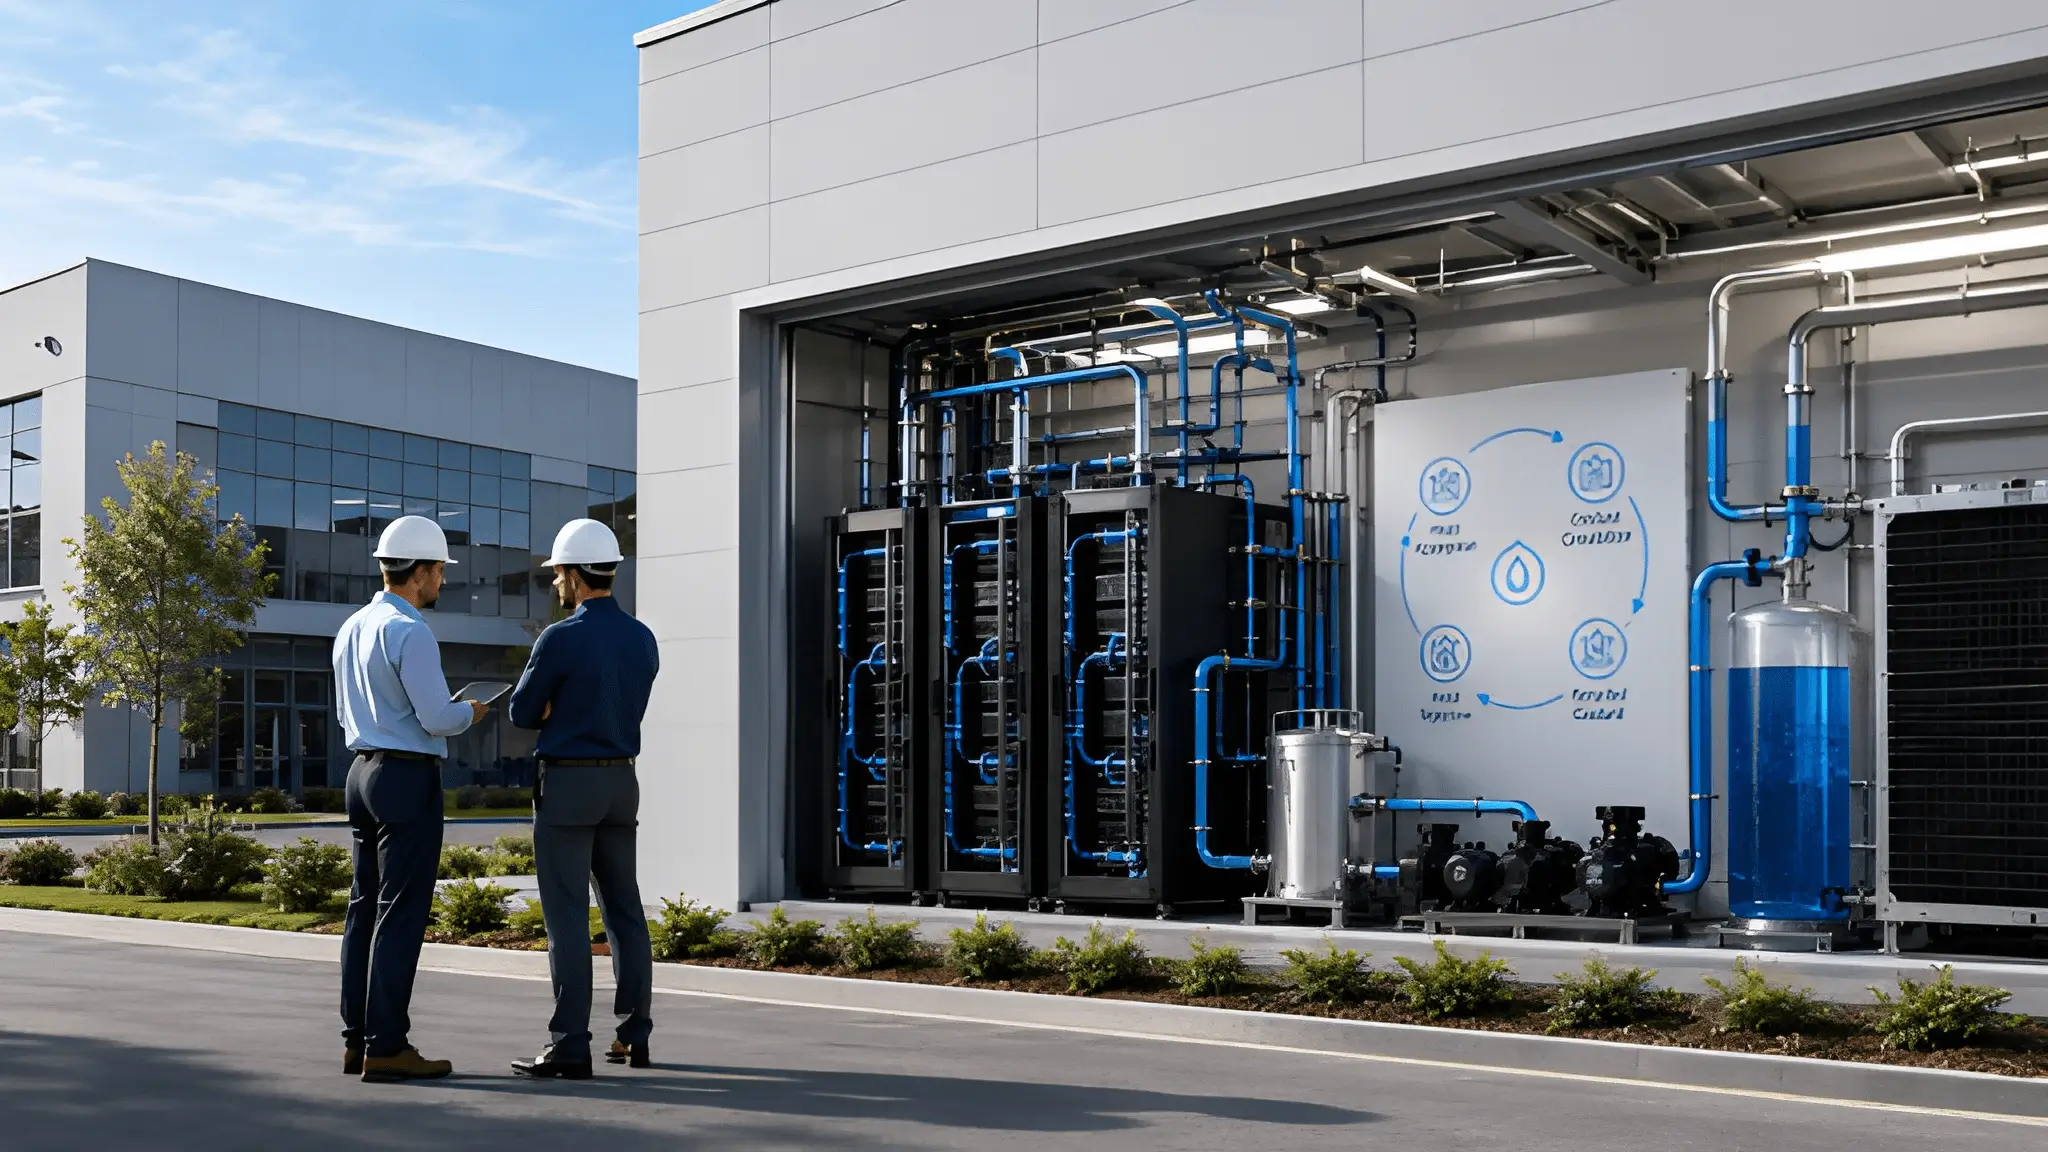
The growth of high-density AI systems makes repairability relevant beyond the server itself. Cooling equipment and fluid-handling components can influence whether computing hardware remains within its required thermal conditions. Direct-to-chip liquid cooling introduces additional interfaces that operators must consider during maintenance. These may include coolant distribution equipment, connections, pumps and monitoring systems. However, maintenance requirements vary with the design, so buyers should not assume that every liquid-cooled installation presents identical risks. They should establish which components technicians can inspect or replace and how maintenance affects coolant circulation. Procedures for leak detection, isolation and system recovery also deserve attention. Procurement teams should verify the availability of compatible parts, service documentation and qualified support for the specific configuration. Where maintenance requires isolating a cooling circuit or taking equipment offline, operators need to understand the consequences for workload continuity and redundancy. A scorecard that evaluates only servers could miss these dependencies and provide an incomplete assessment of operational resilience.
Modular design should be evaluated against real maintenance needs
Modularity can improve serviceability when technicians can replace a failed component without unnecessarily disturbing surrounding systems. However, modular construction does not automatically make equipment easier to repair. Interfaces, proprietary components, configuration dependencies and service restrictions can still complicate maintenance. Buyers should determine whether modularity reduces the time, expertise and equipment needed for common repairs. They should also examine expected parts availability throughout the planned service life. Support for older configurations matters when suppliers introduce newer product generations. A component that can be removed quickly offers limited operational value if its replacement is unavailable or incompatible. In some cases, replacing an entire assembly may also be safer and faster than repairing an individual component. This can be particularly relevant when field repairs require specialized tools or introduce additional reliability risks. Procurement teams should compare these options using documented procedures, realistic parts assumptions and the consequences of each maintenance approach. The central question is whether the design provides practical, economical ways to restore dependable service.
Contracts need to make repairability commitments enforceable
A repairability scorecard will have limited value if procurement contracts leave essential maintenance expectations undefined. Buyers should specify which diagnostic information, service manuals, replacement parts and technical support suppliers must provide. These requirements should account for applicable safety, security, licensing and intellectual property restrictions. Contracts should also clarify warranty coverage, authorized repair procedures, escalation paths and conditions that could affect service eligibility. Response-time commitments require careful interpretation because acknowledging a fault does not mean equipment has returned to production. Contracts can distinguish these stages through measurable milestones for diagnosis, parts dispatch, on-site intervention and restoration. Such milestones should reflect the activities each supplier actually controls. Buyers should also establish how suppliers communicate component discontinuation, material design changes and revised maintenance procedures. These provisions are particularly useful when operators depend on specialized configurations without readily interchangeable replacements. The aim is to make serviceability a documented purchasing requirement, supported by clear responsibilities and evidence rather than broad assurances.
Repairability must fit the economics of the full equipment lifecycle
The case for repairability becomes stronger when buyers consider equipment longevity and total cost of ownership. AI hardware can become less competitive as workloads, software and accelerator generations evolve. Extending a server’s physical life therefore does not necessarily extend its economic usefulness. Even so, efficiently repaired equipment may offer greater flexibility for secondary workloads, phased upgrades or continued operation where performance requirements remain stable. Buyers should compare repair and replacement costs while accounting for energy efficiency, maintenance labor, spare parts and the consequences of retaining older systems. They should also consider whether individual components can be upgraded without replacing the surrounding infrastructure. Neither repair nor replacement is automatically the less expensive option in every situation. Sustainability considerations can inform these decisions by helping buyers assess material use, electronic waste and premature equipment retirement. However, extending equipment life does not automatically improve environmental performance if older hardware consumes substantially more energy. Repairability should inform lifecycle decisions without replacing assessments of performance, energy consumption, reliability and future workload requirements.
The procurement process needs evidence, not another marketing label
Infrastructure buyers can introduce repairability requirements through requests for proposals, technical evaluations, pilot deployments and contract reviews. These steps can fit within existing purchasing processes without requiring an entirely separate procurement system. Vendors can provide documented repair procedures, parts availability information, supported maintenance activities and representative recovery timelines. During technical evaluations, buyers can test whether technicians can identify faults, access affected components and restore systems using the proposed tools. Tests should reflect realistic operating conditions without exposing production equipment to unnecessary risk. Procurement teams can compare results while documenting differences in architecture, support arrangements and replacement inventory assumptions. They should also revisit assessments when equipment configurations change. A modification to a server, rack or cooling arrangement can alter the practical maintenance requirements. Over time, maintenance records can help buyers determine whether supplier commitments match operational experience. This evidence-based approach would make repairability a useful engineering and commercial criterion rather than an unverified label in a product specification.
AI infrastructure buyers should price the ability to recover
The pressure to secure accelerators, power capacity and deployment schedules can encourage buyers to prioritize immediate availability. Less visible maintenance requirements may consequently receive less attention during procurement. Yet operational resilience depends partly on whether technicians can isolate faults, access replacement parts and restore equipment without excessive disruption. Repairability cannot eliminate failures, guarantee uptime or resolve every supply-chain constraint. It can, however, help buyers understand and manage the consequences of equipment faults. A well-designed procurement scorecard would place serviceability alongside performance, power efficiency, cooling compatibility, warranty coverage and lifecycle economics. It would also encourage suppliers to explain how their equipment can be maintained under expected operating conditions. For AI infrastructure users, the benefit is greater visibility into the difference between purchasing hardware and sustaining usable computing capacity throughout its service life. Buyers should require verifiable repairability evidence before procurement decisions lock in years of maintenance obligations.