Skip to content
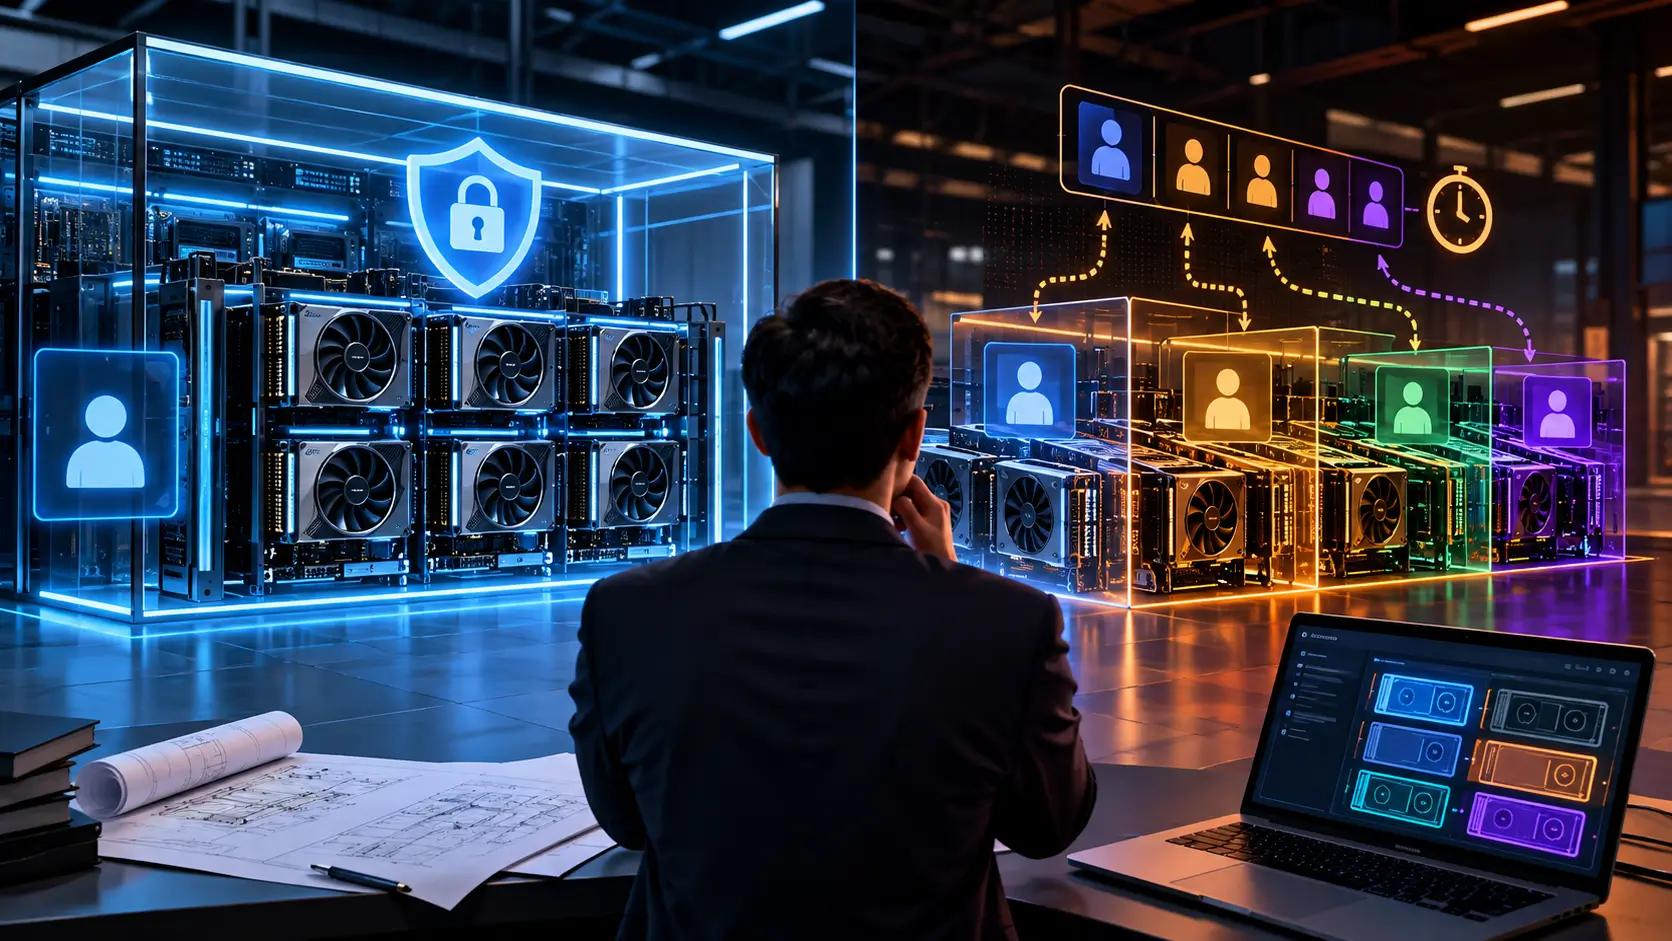
AI infrastructure buyers often focus first on the number of accelerators available under a compute agreement. That number matters, but it does not explain what the provider has committed to keep available. An agreement may refer to reserved resources, guaranteed quantities, preferred access, or an allocation window. Those terms can describe different mechanisms beneath the customer-facing service. Cloud platforms demonstrate this distinction through separate controls for reservations, physical isolation, and workload scheduling. Amazon Web Services (AWS) separates Capacity Reservations from Dedicated Hosts and Dedicated Instances. Microsoft Azure offers Dedicated Hosts that assign physical servers to one subscription. Google Cloud also separates compute reservations from sole-tenant nodes that provide exclusive access to physical servers.
For an AI customer, this distinction changes the questions that should come before a large capacity commitment. A contracted quantity might represent resources held for particular workloads or capacity governed by defined reservation rules. Another service could deliver access through scheduling policies that determine when workloads receive available hardware. None of those models automatically makes a service unsuitable. The customer simply needs to know which model supports the capacity it plans to buy. Accelerator type, deployment region, network configuration, and required launch window can all shape that decision. A training workload may also need many devices to become available at the same time. The contract becomes more useful when commercial capacity maps clearly to operational access.
A GPU Count Does Not Fully Describe the Capacity Model
A contract may give a customer the right to consume a defined number of GPUs without describing every allocation mechanism. Major cloud platforms illustrate why buyers should separate capacity availability from hardware tenancy. AWS Capacity Reservations hold EC2 capacity within a specific Availability Zone. The service supports reservation configurations with default or dedicated tenancy. Google Cloud reservations hold resources that matching virtual machines can consume under defined conditions. Its sole-tenancy service uses a different model and gives a project exclusive access to a physical server. Azure Dedicated Hosts also provide physical servers for virtual machines assigned to one subscription. These documented models show that a reservation and physical isolation answer different infrastructure questions. Customers should therefore identify the resource boundary behind any advertised GPU quantity.
The distinction becomes important when buyers compare services with similar headline specifications. One offer might define capacity around virtual machines, while another could allocate complete nodes or servers. A third service might define access through a larger cluster or scheduling system. The same numerical GPU quantity can therefore sit above different technical architectures. Buyers should identify whether the contractual unit means logical entitlement, GPU allocation, node allocation, or complete server allocation. They should also establish whether the quantity represents simultaneous access or a maximum service entitlement. These questions do not assume that one architecture performs better than another. They establish what the customer will actually receive. A precise resource definition makes later performance and availability discussions easier to manage.
Reservation and Isolation Solve Different Problems
Resource reservation addresses access to qualifying compute capacity, while isolation defines which infrastructure components customers share. Google Cloud reservations hold resources for matching virtual machines according to configured reservation rules. The platform separately offers sole-tenancy for exclusive access to physical Compute Engine servers. AWS also treats Capacity Reservations, Dedicated Instances, and Dedicated Hosts as distinct infrastructure constructs. NVIDIA provides another useful distinction at the accelerator level through Multi-Instance GPU technology. MIG can divide supported GPUs into instances with isolated compute and memory resources. These examples show why reserved capacity does not automatically mean physically isolated infrastructure. A provider can reserve resources while parts of its service remain shared. Customers should therefore request separate definitions for resource availability and infrastructure isolation.
Yet, single-tenant infrastructure can use a different allocation boundary. Lambda Private Cloud, for example, documents bare-metal clusters reserved for one customer’s use during defined periods. That model gives buyers a concrete example of capacity tied to single-tenant infrastructure. Other providers may structure their services differently, so customers should verify each offering independently. A contract can state whether exclusivity applies to GPUs, servers, nodes, clusters, or another defined resource. It can also identify which supporting components remain shared. This approach prevents the term “dedicated” from carrying more meaning than the architecture supports. Buyers can then compare reservation and isolation as separate service characteristics. The resulting comparison focuses on actual infrastructure rights rather than broad product labels.
Prioritized Access Can Still Be Operationally Valuable
Priority does not automatically represent a weak capacity model. A defined scheduling policy can serve workloads that tolerate variable start times or operate with flexible resource requirements. Kubernetes demonstrates the technical difference through its documented pod priority and preemption mechanisms. Priority indicates the relative importance of one pod compared with another. Under defined conditions, the scheduler can attempt to preempt lower-priority pods for higher-priority work. That behavior differs from assigning an isolated physical resource pool to one customer. A neocloud may use another scheduler or proprietary system, so Kubernetes does not describe every provider. Customers should ask which scheduling rules actually govern their service. The answer determines what priority means when several workloads compete for limited resources.
Some workloads can operate effectively under a clearly defined priority model. Batch processing, experimental training, and flexible inference jobs may not require permanently isolated hardware. Tightly scheduled training programs can present a different requirement when engineers need resources within a specific operating window. Delayed allocation may then interfere with planned data pipelines, engineering work, or deployment schedules. The contract should describe how the service handles such demand rather than relying on the word “priority.” Buyers can ask whether workloads enter a queue and how the platform orders that queue. They can also ask whether higher service tiers can affect jobs that have already started. Those answers turn scheduling priority into a measurable service characteristic. The buyer can then decide whether that characteristic fits its workload.
The Scheduler Can Become Part of the Commercial Product
An orchestrated AI platform can make scheduling behavior part of the practical value customers receive. Buyers should understand queue ordering, admission controls, preemption rules, and any applicable allocation limits. Kubernetes shows how a scheduler can prioritize pending work and preempt lower-priority workloads under defined conditions. A particular neocloud may implement completely different policies. Customers should therefore determine whether priority applies only before placement or can affect running workloads. They should also ask whether service tiers draw resources from separate pools. Some platforms may instead schedule several workload classes against common infrastructure. The contract can identify which arrangement applies to the purchased service. This information matters when a customer expects many accelerators at once.
A useful capacity definition should also state whether customers can launch their full contracted quantity simultaneously. A provider may instead make access subject to stated scheduler conditions or allocation rules. Customers should know what happens to unused entitlement during periods of low utilization. The provider might keep resources reserved, leave them unallocated, or manage them under another documented policy. Each arrangement creates a different relationship between commercial entitlement and immediate resource access. By contrast, a documented single-tenant cluster can reserve identified infrastructure for one customer’s workloads. Neither approach should remain implicit in a large compute contract. The buyer needs enough detail to understand what happens when demand reaches its contracted limit. That knowledge becomes particularly important for workloads that cannot start with only part of the required cluster.
Dedicated Infrastructure Needs a Precise Boundary
The word “dedicated” needs a technical boundary because an AI platform contains far more infrastructure than its accelerators. Lambda Private Cloud provides one documented example through its single-tenant bare-metal cluster model. Azure Dedicated Hosts establish isolation at the physical server level. Microsoft also notes that these hosts still use shared network and underlying storage infrastructure within Azure data centers. Google Cloud sole-tenant nodes provide exclusive access to physical servers for the customer’s project. These examples show how isolation can stop at different points within an infrastructure stack. A service can provide exclusivity at one layer while sharing another layer. Buyers should therefore identify the exact boundary covered by a single-tenant commitment. A broad “dedicated” label cannot provide that architectural detail by itself.
The relevant boundary might include GPUs, compute nodes, physical servers, racks, storage, or selected network components. Customers do not necessarily require exclusive control over every layer. They need to understand which resources they share and which resources the provider assigns exclusively to them. Distributed AI workloads make that distinction particularly relevant because applications can exchange data across several accelerators and nodes. Supporting infrastructure can therefore influence how a multi-node workload operates. The contract can document the isolation boundary without prescribing one architecture for every use case. That approach also makes technical comparisons more precise. Buyers can evaluate whether the offered boundary matches their security, performance, and operational requirements. Procurement teams gain a clearer basis for comparing services that use similar commercial terminology.
GPU Partitioning Makes the Question More Detailed
Physical GPU presence does not always mean that one workload consumes every resource on that accelerator. NVIDIA’s Multi-Instance GPU technology can divide supported accelerators into multiple GPU instances. MIG provides separate compute and memory resources to those instances. It also provides isolated paths through portions of the GPU memory system. Multiple GPU instances can operate in parallel on a single supported physical accelerator. NVIDIA also documents MIG configurations that work with virtualization and virtual GPU technologies. Customers therefore need to distinguish a physical accelerator from the logical resource exposed by a service. The difference matters when contracts measure capacity in “GPUs” without defining that unit. A precise definition removes that ambiguity.
A customer should establish whether its purchased unit represents a whole physical GPU, virtual GPU, MIG instance, or another defined resource. Software consumes the resources exposed through the platform’s configured allocation model. Commercial measurement should use the same unit when the parties compare delivered capacity with contracted capacity. This becomes especially important when customers compare offers across providers. A headline quantity alone may not identify the accelerator allocation method beneath the service. Contracts can solve the problem with a clear description of the purchased resource. They can also specify relevant accelerator models and configurations. Such detail does not require the provider to expose unnecessary internal architecture. It simply gives both parties a consistent unit for capacity measurement.
Reserved Capacity Should Identify Who Can Consume It
Another capacity question concerns which workloads can consume reserved resources. Google Cloud illustrates this issue through automatic and specifically targeted reservations. Matching virtual machines can consume automatic reservations according to the platform’s applicable rules. A specifically targeted reservation requires a qualifying instance to target that reservation. Google Cloud also provides information about reservation consumption and remaining capacity. AWS supports open and targeted Capacity Reservations under its own model. These controls demonstrate that reservation scope matters alongside the amount of capacity held. A buyer should therefore understand which workloads or environments can draw against its contracted pool. That question becomes more important when several projects share one commercial account.
Customers can also ask what happens to unused resources when their workloads consume less than the contracted amount. A provider’s terms should explain whether those resources remain reserved or follow another allocation policy. If the service permits temporary use elsewhere, the agreement can define how the customer’s access returns when requested. These questions do not assume that every neocloud uses the same reservation architecture. They establish the behavior that applies to the specific purchased service. As a result, capacity reporting becomes more useful when it separates entitlement from current consumption. Reports can also show resources available for customer use under the applicable service model. This visibility helps operations teams reconcile contractual capacity with actual allocation. It can also make disputes about resource availability easier to investigate.
Availability Needs to Be Tested at the Required Scale
Capacity at one allocation size does not automatically demonstrate availability for a much larger distributed job. Google Cloud documents several accelerator consumption models with different availability characteristics. Its GKE documentation also explains how workloads can consume specific reservations. A workload cannot obtain requested reserved resources when the applicable reservation lacks enough matching capacity. Distributed GPU applications may require several compatible accelerator-equipped nodes within the required configuration. A customer needing 512 GPUs concurrently therefore has a different requirement from one consuming 512 units across smaller jobs over time. Both scenarios may involve the same aggregate accelerator count. Their launch requirements, however, differ materially. Contracts should distinguish aggregate entitlement from simultaneous allocation when the service treats those concepts differently.
The capacity definition can specify allocation granularity, supported cluster size, and relevant location constraints. It can also describe conditions that govern access to the full contracted quantity. A dashboard showing unused accelerators does not by itself establish that every requested multi-node configuration can launch immediately. The available units must also satisfy the configuration required by the workload. Buyers should therefore test capacity discussions against the scale of their intended jobs. This approach gives technical teams a more useful measure than aggregate inventory alone. It also connects procurement language with real deployment requirements. The provider can explain which combinations of resources its commitment covers. Customers can then plan workloads around a capacity model they understand.
Customers Need Evidence, Not Just Capacity Labels
A capacity agreement becomes easier to govern when customers can compare entitlement with actual allocation. Google Cloud, for example, exposes reservation information that users can inspect through its management tools. Customers can view consumption and determine which resources use relevant reservations. Neocloud providers may expose different controls because their architectures and management systems differ. Useful evidence can include allocation records, resource identifiers, reservation status, or comparable service telemetry when available. Customers do not require unrestricted access to every provider system. They need enough evidence to understand the service they receive. Clear reporting can distinguish customer consumption from scheduler behavior or infrastructure events. That distinction can become particularly valuable during a capacity dispute.
Provider security and tenancy controls can determine which infrastructure information appears through customer-facing interfaces. A contract can therefore define the evidence appropriate to the service without requiring disclosure of unrelated tenant information. Operations teams might need different visibility from procurement or finance teams. Technical users may focus on resource state and allocation history. Commercial teams may instead need evidence showing whether contracted quantities remained available during the relevant period. Both views can rely on the same clearly defined capacity model. Verification then becomes part of routine service governance rather than an investigation after a shortage occurs. Customers gain a repeatable method for comparing promised access with delivered access. Providers also gain clearer criteria for demonstrating fulfillment of their commitments.
Idle Capacity Reveals the Economics of the Model
Idle resources can help buyers understand the economics behind different capacity products. Lambda states that its on-demand instances accrue charges while they run, even when customers do not actively use them. Its cluster offerings can follow reservation-based billing terms. Google Cloud charges for reserved Compute Engine resources while applicable reservations exist, subject to its pricing rules. Azure charges customers for Dedicated Hosts regardless of how many virtual machines run on those hosts. These models differ, so buyers should not treat them as a template for every neocloud agreement. They do show how stronger capacity control can carry costs during periods of low utilization. Buyers should examine who bears that cost under their own contract. They should also understand whether unused resources can serve other customers.
Billing terms alone cannot establish the underlying infrastructure architecture. Technical allocation and tenancy provisions need to confirm how the provider operates the service. Pricing can still provide useful context when buyers examine it alongside those provisions. A customer paying for idle resources may want to understand what rights accompany that payment. Another customer may accept shared infrastructure in exchange for a different commercial structure. Neither arrangement automatically provides the better answer for every workload. Buyers need the arrangement that matches their operating requirements and risk tolerance. Pricing becomes easier to interpret when it sits beside a precise capacity definition. The commercial and technical descriptions should refer to the same service behavior.
Failure Conditions Belong in the Capacity Definition
Hardware isolation does not remove the possibility of component failures or maintenance events. Azure Dedicated Host documentation includes maintenance controls and host service-healing mechanisms within its hosting model. AWS also documents limitations for Capacity Reservations. For example, a reservation does not guarantee that a hibernated instance can resume successfully. These examples show why capacity assurance and workload recovery need separate definitions. A customer should know what happens when a contracted accelerator, node, or other required component fails. The provider’s service terms can explain how it obtains compatible replacement resources. They can also establish the expected restoration process. Capacity therefore needs a recovery dimension as well as an allocation dimension.
Replacement capacity may need to preserve characteristics that matter to the customer’s workload. These can include accelerator type, network configuration, topology requirements, or required data access. The exact list will depend on the service and application. A replacement resource that changes a material characteristic may not support the workload in the same way. Customers should therefore define which characteristics must remain consistent during restoration. In practice, measurable restoration requirements make the capacity commitment easier to administer after a failure. They also prevent the contract from treating every replacement resource as automatically equivalent. Providers gain a clearer specification for acceptable restoration. Customers gain a clearer standard for determining when capacity has returned.
Capacity Rights Should Survive Routine Operational Changes
AI infrastructure can change during a contract as providers replace components, expand clusters, modify orchestration, or introduce newer hardware. Those changes do not automatically reduce the quality of a service. They can create ambiguity when the original contract never defined the resource boundary. A customer purchasing a specific accelerator model may need rules governing hardware substitution. Another customer may require a migration to preserve an agreed single-tenant boundary. Scheduling changes can also matter when a provider changes how service tiers access infrastructure. GPU partitioning adds another variable when platforms support several allocation configurations. NVIDIA documents deployment approaches that include bare metal, pass-through virtualization, MIG, and vGPU technologies. Those options demonstrate why the implementation beneath a service can take several forms.
No single architecture suits every AI workload. Performance, isolation, utilization, security, and cost requirements can lead customers toward different designs. Procurement language should therefore focus on the characteristics the customer needs rather than freezing every internal implementation detail. A provider can retain operational flexibility while preserving the service properties it promised. Customers can identify which changes require notice or technical validation. They can also define when a substitution changes the commercial product enough to require approval. This approach keeps infrastructure evolution from creating unnecessary contractual uncertainty. It also gives technical teams a framework for assessing changes during the service term. The capacity commitment remains tied to measurable characteristics rather than an undefined label.
Procurement Needs a Capacity Specification, Not a Single Adjective
Procurement teams can reduce ambiguity by turning broad capacity terminology into measurable infrastructure requirements. A specification can identify accelerator type, quantity, allocation boundary, tenancy model, and supported cluster size. It can also define relevant location requirements and rules for simultaneous consumption. Customers should know whether unused resources remain exclusive or follow another allocation policy. Scheduling terms can describe how waiting workloads obtain resources when demand exceeds immediately available capacity. Isolation terms can identify the GPU, node, server, or cluster boundary covered by the agreement. Capacity terms can explain how customers verify the quantity available to them. Recovery provisions can establish how the provider restores resources after failures.
These questions do not require every customer to purchase physically isolated infrastructure. Documented cloud and accelerator platforms support several shared and isolated deployment models. Different applications can benefit from different combinations of cost, control, flexibility, and isolation. The important point is to define the model before comparing services primarily on price. A buyer should know whether it purchases physical exclusivity, reserved entitlement, priority, or another defined allocation right. That definition can then guide technical testing and commercial measurement. It can also help engineering teams understand the limits of the purchased service. Procurement gains a more defensible basis for comparing competing offers. The provider gains a clearer statement of what the customer expects.
The Contract Should Describe What Happens at the Moment of Demand
One capacity question exposes many of these distinctions: what happens when the customer requests every contracted accelerator simultaneously? If resources already belong to the customer’s environment, the agreement can identify that allocation boundary. If the service draws resources from a broader pool, the contract can explain the relevant allocation mechanism. A priority service should define how its scheduler handles competing demand. Reservation-based services should identify which workloads can consume the reserved resources. Google Cloud distinguishes automatic reservation consumption from specifically targeted reservation consumption. AWS also supports open and targeted Capacity Reservations under its own rules. Those examples show how resource consumption can follow explicit configuration rather than one universal reservation model. Neocloud customers need the same level of conceptual clarity from the services they purchase.
A customer does not need the same infrastructure model for every AI workload. Some workloads may justify single-tenant resources because predictable access or isolation matters strongly. Others may operate effectively with reservations, scheduling priority, or shared infrastructure. The commercial question is whether the customer understands the access right before committing to the service. Contracts should make that right observable through allocation rules, service terms, and appropriate reporting. They should also define what happens when the customer requests its maximum contracted quantity. That moment tests whether a capacity number represents entitlement, priority, reservation, or exclusive infrastructure. Clear definitions allow engineering and procurement teams to evaluate the same product from different perspectives. For neocloud buyers, that clarity can matter as much as the accelerator count printed on the order form.