Skip to content

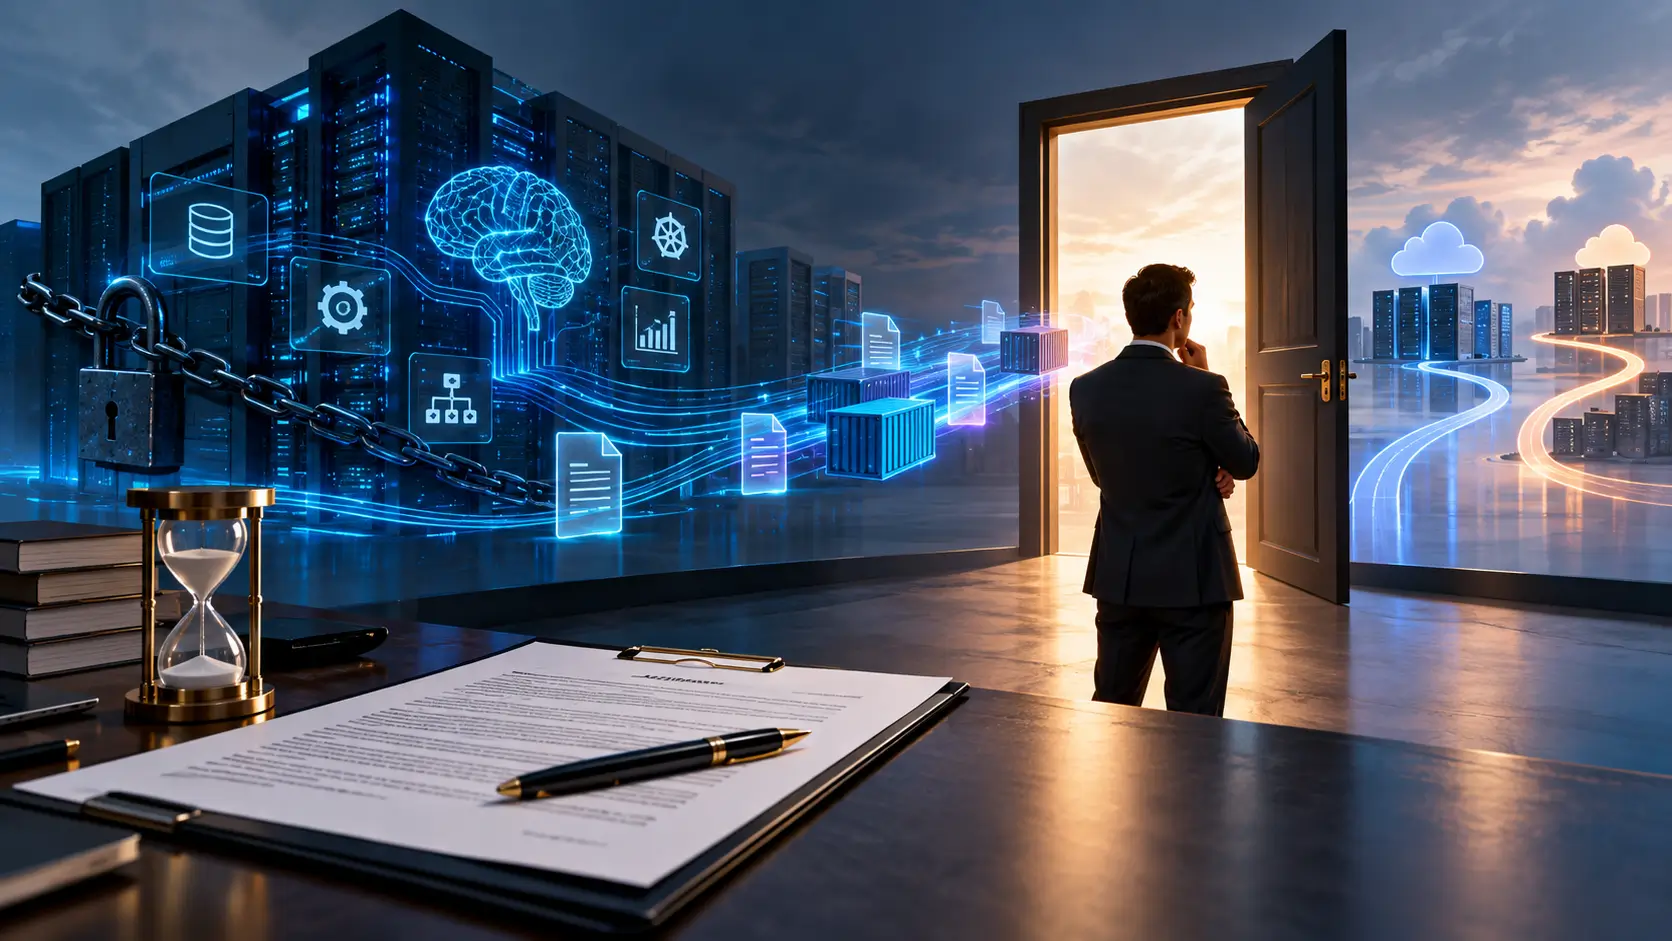
AI infrastructure procurement can begin with a simple problem: a team needs GPUs sooner than its existing capacity plan can support. Specialised cloud infrastructure can provide accelerated computing resources designed for AI and other computationally intensive workloads. For an AI buyer facing a production deadline, a multi-year capacity agreement can address an immediate availability requirement. It can also give engineering teams a defined environment for training or inference.

Yet the commercial decision extends far beyond obtaining access to accelerators. Over the contract term, the buyer can build operational processes, storage paths, deployment automation and application dependencies around that environment. Those dependencies can matter when the contract approaches renewal or the workload needs to move earlier. A procurement process focused only on entry economics can overlook an equally important question: how does the customer get out? The buyer needs to understand that path before infrastructure dependencies make the answer more complicated.
The Contract Can Outlive the Original Infrastructure Decision
A three-year infrastructure commitment does not guarantee that the assumptions supporting the original purchase will remain unchanged. AI workloads operate within software and hardware environments that can change as applications develop and infrastructure requirements evolve. Accelerator platforms can also advance during the contract period. The infrastructure environment contains more than GPUs because drivers, networking and runtime components affect how applications use the hardware.
NVIDIA’s GPU Operator documentation, for example, lists GPU drivers, the Container Toolkit, Kubernetes device plugins and monitoring components. These components help manage GPUs in supported Kubernetes environments. NVIDIA also publishes platform-support information covering operating systems, Kubernetes environments, container runtimes and GPU deployment configurations. Such dependencies do not make migration inherently impractical. They do show why moving an accelerated workload can involve more than copying application files to another machine.

Buyers should treat the contract term as one timeline and the technical lifecycle of the workload as another. The relationship between those timelines should become part of the infrastructure decision before the agreement begins. A training environment configured for an existing workload may need adjustment as the customer’s requirements change. Memory capacity, accelerator configuration, storage performance and networking requirements can differ among AI workloads.
An infrastructure configuration that meets one deployment profile does not automatically match every future profile. New accelerator generations can also introduce different hardware capabilities during a multi-year infrastructure agreement. None of this automatically makes a long-term commitment unattractive. Predictable capacity can have substantial operational value when infrastructure availability matters to product schedules.
Problems arise when the customer lacks a practical contractual or technical route for responding to change. Buyers should understand whether committed capacity can move between hardware types, locations or service configurations. They should also determine whether such changes require a different commercial arrangement. The answers depend on the provider and individual contract, so assumptions are dangerous during procurement. Exit planning starts with understanding exactly which parts of the environment remain flexible after signing.
Portability Has to Be Tested, Not Assumed
Cloud portability has been an established technical concern for years. AI infrastructure introduces additional hardware and software dependencies into that discussion. NIST has addressed application and data portability as part of cloud interoperability. It has also examined the movement of workloads and data between cloud environments.
Those considerations remain relevant because applications can encounter configuration, compatibility or performance differences after migration. Accelerated computing adds device drivers, GPU scheduling, runtime configuration and hardware-specific requirements to the dependency list. NVIDIA’s GPU tooling supports multiple Kubernetes environments, operating systems and container runtimes within documented compatibility boundaries.
Common components can provide useful building blocks across supported infrastructure, but they do not make every implementation identical. A buyer needs to identify which production layers use broadly portable interfaces. Teams should separately identify dependencies on provider-specific services or configurations. That inventory should exist before a long-term agreement turns portability into an urgent engineering project.
Containers Solve Only Part of Portability
Containerisation can improve portability at the application layer, but it does not represent a complete migration strategy. NVIDIA’s support for the Container Device Interface provides a useful example. CDI uses an open specification designed to standardise how compatible container runtimes access devices such as GPUs. This can simplify one part of device integration across supported container environments.
A production AI system can still depend on storage APIs, networking behaviour and identity systems outside the container. Other dependencies can include secrets management, monitoring pipelines, managed databases and provider-specific orchestration features. Moving the container image does not automatically reproduce these surrounding services.
Engineering teams should map those dependencies while procurement negotiations remain open. Contractual flexibility becomes more valuable when engineers understand what actually needs to move. The resulting dependency map can separate portable components from services that require replacement or redesign. Moreover, it gives procurement teams a technical basis for defining migration assistance instead of assuming workload export will be straightforward.
Data Can Become a Major Part of the Exit
AI workloads can create substantial collections of checkpoints, model artefacts, datasets, logs and intermediate outputs. Data movement can therefore become an important operational component of a provider transition. Migration services available from major cloud platforms illustrate the practical challenge of moving large datasets.
Google, for example, provides Transfer Appliance workflows that can export Cloud Storage data using encrypted physical appliances. Services designed for offline bulk movement show that large-scale migration does not always rely solely on conventional network transfers. Transfer duration depends on the migration method and characteristics of the source and destination environments. The quantity of data that needs to move also matters.
Customers should estimate migration requirements using the data footprint expected near the end of the agreement. Looking only at the volume present when the contract begins can produce an incomplete picture. Growth assumptions belong in exit planning because production workloads can accumulate information over time. An architecture that is straightforward to migrate initially may require a different process after several years of operation.
The buyer also needs a precise understanding of what can be exported and in what form. Raw objects may require a different migration process from service configurations or access controls. Application metadata and operational records associated with the surrounding platform may require separate treatment.
Migration planning should identify the customer-controlled assets required to reproduce or continue the workload. The exact list depends on the architecture in use. Relevant assets can include model checkpoints, weights, datasets, container images, deployment definitions and operational configuration. Teams should also determine which historical information must remain accessible after primary workloads leave.
NIST cloud-interoperability work includes use cases involving application migration and copying data objects between cloud providers. This reinforces the broader principle that portability involves applications as well as data. However, an AI workload can contain multiple infrastructure and application assets beyond the model itself. The migration scope should reflect the actual deployment. A contractual right to retrieve data becomes more useful when engineers already know what information they need to retrieve.
Exit Economics Belong in the Original Business Case
Infrastructure buyers commonly compare compute rates, storage charges and networking costs before selecting a platform. Exit costs deserve a place in the same financial model. Migration can consume engineering time. Some strategies may also operate source and destination resources simultaneously while engineers validate the replacement environment.
That overlap can add infrastructure expense when teams keep the original environment available during testing. Data-transfer operations can also carry direct charges depending on the services and mechanisms involved. Google’s published Transfer Appliance pricing, for example, identifies appliance-related charges and other potential costs. These can include storage operations, transfer services, extended usage and shipping.
Those charges apply to Google’s service rather than representing a universal cloud pricing model. Still, they demonstrate why a chosen migration method should be costed rather than assumed to be free. Buyers evaluating specialised providers should request equivalent information for their contractual environment. Financial models should cover migration labour, planned overlap, data movement and termination-related obligations specified by the agreement.
Commitment Discounts Need Context
This changes how procurement should interpret a discounted multi-year commitment. A lower committed rate can create genuine savings when the customer consumes the contracted resources. The platform must also continue meeting workload requirements for those economics to remain relevant.
The same commitment can limit commercial options when an agreement restricts changes to capacity, hardware configurations or consumption. Those outcomes depend on the actual agreement. Buyers should therefore avoid assuming that every long-term neocloud contract creates identical restrictions.
Instead, commercial reviews can model normal completion, partial migration, early workload relocation and provider transition at renewal. Each scenario can expose different costs and operational dependencies. Procurement teams can compare the economic benefit of the commitment with the contractual flexibility available during its term. The resulting analysis goes beyond headline GPU prices and considers how the infrastructure decision operates throughout the agreement.
The Exit Clause Needs Technical Meaning
A termination clause can define legal rights without explaining whether a customer can execute a safe technical transition. Buyers should connect contractual language to operational requirements such as access periods, data retrieval and credentials. Support availability and the treatment of customer assets after termination also deserve attention.
Some migration strategies may require continued access to the source environment while engineers validate workloads at the destination. If a contract limits access after termination, the engineering team needs to understand that timing before selecting its migration procedure. Procurement teams should ask how long data remains available and what happens during account closure.
Teams should also determine whether the provider supplies export tooling, technical assistance or migration documentation. Those capabilities should meet the customer’s actual migration requirements. Therefore, exit provisions become more useful when important contractual rights correspond with clearly defined technical steps.
Service continuity deserves similar attention because production transitions can involve several stages rather than one instantaneous move. An inference workload may use staged traffic migration while engineers validate the destination. Training workloads can use checkpoints or other recovery mechanisms when the application and framework support them.
Data replication may also form part of the migration architecture. This can apply when source and destination systems need synchronisation during a transition. Identity and access policies require careful handling so users and services retain appropriate permissions in the destination environment.
These are general engineering considerations rather than characteristics unique to neoclouds. However, a long-term infrastructure contract can influence the conditions under which engineers must solve them. NIST portability work establishes that moving applications and data between cloud environments raises interoperability considerations. The exit schedule should provide enough time to test the destination before contractual access to the original capacity ends.
Hardware Choice Can Become a Migration Constraint
A customer buying GPU capacity also receives access to a system architecture built around those GPUs. High-performance AI environments can include specific operating systems, driver versions, container runtimes and virtualisation arrangements. These elements appear in NVIDIA’s compatibility and platform-support documentation.
Supported deployments can include bare-metal environments and virtual machines using GPU passthrough. Virtualised GPU configurations can also form part of supported deployments. Compatibility depends on the platform and software combination.
The destination environment should therefore be validated against the software assumptions embedded in the customer’s workload. An application requiring a particular driver, runtime or virtualisation configuration may need changes at the destination. Buyers should record those assumptions while designing the initial platform rather than reconstructing them during an urgent migration.
Architecture documentation becomes part of exit readiness because it identifies what a replacement environment needs to support. Portability becomes easier to evaluate when the buyer knows which infrastructure characteristics are essential. It also helps teams distinguish genuine workload requirements from properties of the current deployment.
Hardware Flexibility Should Be Contractual
Hardware evolution raises another question: can the customer change committed infrastructure without making a complete provider exit? Multi-year agreements should explain how upgrades, substitutions or accelerator configuration changes work during the term.
A provider may continue supplying contracted infrastructure while the customer’s workload requirements change. Those changes can alter the desired configuration. Newer hardware is not universally better because performance and economics depend on the workload. Buyers instead need to understand whether commercial commitments attach to a defined configuration.
A useful review can examine whether the provider permits committed spending to move between eligible services, cluster configurations or locations. Buyers should never assume these capabilities because they depend on provider offerings and negotiated terms. Meanwhile, engineering teams can benchmark alternative environments before a contract event creates urgency. That preserves evidence-based decision-making during renewal or migration discussions.
A Second Environment Should Exist Before It Is Needed
An exit plan becomes more credible when the buyer has tested at least one technically suitable alternative destination. This does not require a permanently duplicated production environment. Maintaining equivalent infrastructure across providers can add cost and operational complexity.
A smaller validation environment can test selected migration assumptions. Teams can determine whether container images launch correctly, deployment definitions work and required storage interfaces remain available. NIST interoperability work includes use cases involving application migration and copying data between cloud providers. Movement between cloud environments is therefore a recognised portability problem.
Regular validation can also show whether migration documentation still reflects the production architecture. Testing may identify dependencies that require modification before a workload can operate elsewhere. Engineers can address those dependencies while the existing platform remains available. That is preferable to discovering them during a time-sensitive transition.
Testing should measure more than whether an application starts successfully. Engineers can compare throughput, latency, accelerator utilisation, storage behaviour and network performance under representative workloads. Successful deployment does not establish identical performance across infrastructure environments.
NIST cloud-computing work treats performance measurement as an important consideration when comparing and operating cloud services. AI systems make performance validation particularly relevant. Software configuration, hardware characteristics and infrastructure topology can influence workload behaviour.
A migration rehearsal can also measure the time required for data replication, environment creation and workload validation. Those observations help procurement and engineering teams estimate transition requirements using measured results. Testing can also show whether additional expertise or provider assistance will be necessary. Exit readiness becomes measurable when the organisation records the time, dependencies and technical steps demonstrated during migration testing.
Operational Knowledge Must Remain With the Buyer
Provider support can reduce the operational burden of running specialised infrastructure. Customers should still avoid allowing essential knowledge about their workloads to exist only inside the provider relationship. Internal teams need current documentation covering deployment procedures, network requirements, storage mappings and security controls.
Dependency versions and recovery procedures should also remain documented. Configuration should remain reproducible wherever practical so another engineering team can understand how the production environment was assembled. Kubernetes and standardised container tooling can provide common operational mechanisms across supported environments.
NVIDIA’s tooling demonstrates how Kubernetes mechanisms can manage GPU resources while still depending on documented compatibility requirements. Buyers can use that distinction when documenting which parts of their stack use portable interfaces. Components requiring adaptation for another environment should remain equally visible.
The objective is not to eliminate every platform-specific feature. Doing so could prevent teams from using services that provide legitimate technical value. Instead, dependencies should remain intentional, documented and measurable before they influence a future migration.
Renewal Should Be a Decision, Not a Deadline
The strongest exit plan may never result in an exit, and that does not make the work unnecessary. A provider that continues delivering the required capacity, economics and operational performance may remain appropriate at renewal. A prepared customer simply enters that discussion with tested alternatives, documented dependencies and an estimate of switching costs.
Without preparation, the engineering effort and time required for migration can affect the options available near contract expiration. NIST has long treated portability as a cloud-computing consideration involving applications and data moving between environments. For AI buyers, the same principle needs to account for accelerator configurations and supporting infrastructure.
Contract reviews should begin early enough for the organisation to evaluate technical migration before the existing term expires. Buyers can then compare renewal with available alternatives using documented technical and commercial information. Renewal becomes a deliberate infrastructure decision rather than an outcome driven mainly by insufficient preparation time.
An AI buyer does not need to distrust a neocloud provider to prepare for leaving it. Long-term infrastructure agreements can provide useful capacity certainty when contracted resources matter to product delivery. The procurement discipline comes from recognising that certainty on the first day should not eliminate optionality on the last one.
Before signing, the buyer should know what data must move and which application dependencies require replacement. Teams should estimate how long the tested migration process could take. Contractual access during transition and commercial obligations after an early departure should also be clear.
Engineering teams should test enough of an alternative architecture to distinguish assumed portability from demonstrated portability. Legal and procurement teams should connect termination rights to the operational steps required to exercise them. Finance should include expected switching costs when evaluating the commitment’s economics.
A multi-year deal becomes easier to evaluate when the organisation understands both entry and exit. That preparation can reduce avoidable pressure on the AI workload, its data and the operating timetable.