
Why Shared Cooling Infrastructure Is Becoming a Capacity Allocation Problem
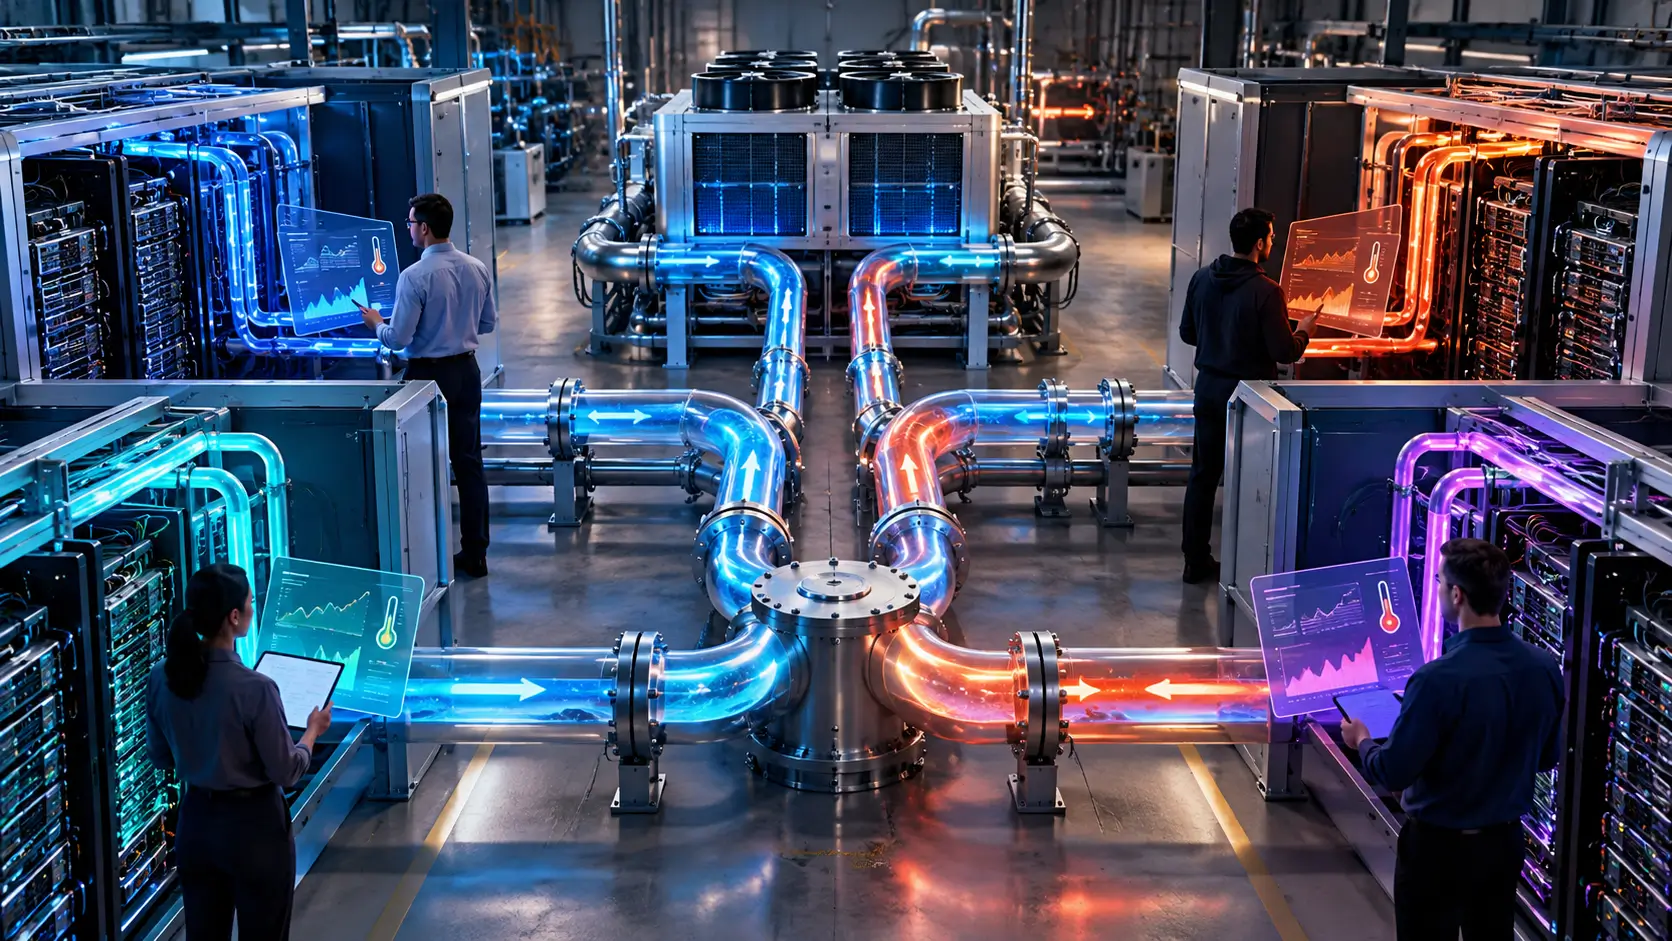
An AI data center can have enough electrical capacity to power several GPU clusters but still struggle to cool them during demanding workloads. High-density computing concentrates heat within a limited physical footprint. Operators must therefore manage coolant flow, supply temperatures, heat exchanger performance and supporting equipment carefully. When several customers share cooling infrastructure, their technical requirements become interconnected. One customer may reserve a specific number of GPUs, while the operator manages the pumps and distribution equipment serving everyone. The challenge extends beyond the cooling plant’s rated capacity. Operators must determine how much usable thermal capacity remains under actual operating conditions. If several customers increase utilization simultaneously, shared equipment may approach its operating limits. This can affect deployment schedules, workload planning and the amount of computing capacity an operator can reliably promise. The commercial question is clear: who controls the remaining thermal margin, and how should the provider allocate it?

The Difference Between Installed Cooling and Usable Headroom
Cooling headroom describes the additional heat-removal capacity available before a system reaches a defined operating limit. Its calculation depends on the system boundaries and operating conditions. Operators cannot determine usable headroom simply by subtracting current demand from advertised plant capacity. Equipment performance, coolant temperatures, flow rates and redundancy requirements also affect the available margin. A facility may have sufficient nominal capacity across its chillers and heat rejection equipment. However, a distribution branch could face a more restrictive flow limit. A coolant distribution unit may also reach its practical limit before the wider cooling plant runs out of capacity. GPU clusters depend on the cooling delivered at their interfaces, not merely on equipment installed elsewhere. Operators must distinguish plant capacity from distribution capacity and rack-level capability. They must also account for equipment reserved for maintenance, redundancy and recovery from component failures. Without these distinctions, a facility could report spare capacity that customers cannot actually use.
How Shared Cooling Loops Create Competition Between Customers
A shared cooling architecture can connect several racks to common pumps, heat exchangers, distribution headers or heat rejection equipment. The precise arrangement depends on the facility’s design. Each component introduces operating limits that affect heat removal and coolant delivery. A pump may provide sufficient total flow while individual branches receive different flow rates. Hydraulic resistance, valve positions, piping geometry and changing demand can all influence distribution. Consequently, one rack may have less usable cooling capacity than another. Both racks might depend on the same upstream infrastructure, yet experience different operating conditions. Coolant temperature also affects heat transfer. Supply temperature determines the incoming thermal conditions, while return temperature reflects the heat absorbed along the circuit. One customer’s increased heat load can affect shared return conditions when capacity or control flexibility is limited. Engineers must evaluate these interactions through hydraulic calculations, equipment specifications and operating measurements. They should never assume that a shared system distributes capacity evenly.
Why Simultaneous Workloads Change the Allocation Question
Two AI customers can reserve identical GPU counts yet create different thermal demand profiles. Their hardware configurations, utilization patterns and workloads may differ considerably. One customer might run sustained model training jobs, while another operates inference services with variable demand. Neither workload category establishes a fixed ranking of cooling requirements. Actual heat output depends on hardware configuration, power limits and workload execution. When several customers experience high utilization simultaneously, their combined heat load can expose limitations hidden during quieter periods. A provider that plans around average utilization may discover that peak demand leaves less operating margin than expected. Conversely, conservative peak-demand planning may leave substantial capacity unused for long periods. Neither approach resolves the allocation problem by itself. The operator must define how it measures demand, protects operating limits and handles competing requests. Customers should understand whether their contracts support a specified cooling envelope during concurrent demand. An advertised facility-wide cooling rating alone does not establish that guarantee.

Who Should Receive the Remaining Thermal Headroom?
When several customers share a constrained cooling system, the operator needs a clear allocation policy. That policy should separate contractual entitlements from temporary operating flexibility. A customer that has paid for defined compute capacity should not have to rely on informal assurances about cooling availability. However, a provider cannot promise every customer unlimited access to the same finite thermal reserve. Contracts should identify the relevant capacity boundary. The commitment might apply to the facility, a cooling distribution unit, an individual rack or the customer’s complete compute allocation. Agreements should also specify the conditions used to measure compliance. These may include inlet temperatures, flow requirements, equipment power limits and permitted operating ranges. If the provider reserves headroom for redundancy or maintenance, the agreement should distinguish that protected reserve from commercially available capacity. The parties can then agree on an allocation method based on reserved entitlements, scheduled demand or priority tiers. Clear rules reduce conflicting expectations when cooling capacity becomes constrained.
Reserved Headroom and Operational Reserves Serve Different Purposes
A facility operator should distinguish customer-allocable capacity from the margin needed to meet reliability and maintenance requirements. The required reserve may account for equipment outages, planned maintenance, changes in ambient conditions or the loss of a critical pump. Its precise size depends on the system design and the facility’s commitments. A cooling plant with spare nameplate capacity may not retain the same margin during a component failure. This becomes particularly important when redundancy depends on specific equipment combinations. Operators should calculate available capacity against the relevant operating configuration rather than treat every unused unit as available for sale. A facility that promises a defined level of availability must maintain the resilience covered by its design and contract. Selling protected reserve capacity could undermine that commitment. Excessive reserves can also restrict customer capacity unnecessarily. Operators should review actual load profiles and equipment performance before changing their reserves. The allocation policy should document its assumptions and require technical reassessment before protected capacity becomes commercially available.
The Measurements That Determine Real Cooling Availability
Cooling allocation becomes more defensible when operators measure performance at the customer interface. A single facility-wide capacity figure cannot describe every operating condition. Coolant flow rate indicates how much fluid passes through a circuit. Supply and return temperatures help establish how much heat the fluid carries away. For a single-phase coolant, engineers can estimate heat transfer using mass flow, specific heat capacity and the temperature difference across the circuit. The calculation requires reliable measurements, appropriate fluid properties and a clearly defined boundary. Pressure measurements provide another important indicator. Insufficient differential pressure can prevent equipment from receiving its required flow, even when the wider loop appears to have spare capacity. Sensor placement matters because an upstream reading may not represent conditions at an individual rack. Operators should compare measurements with equipment power, workload activity and control-system responses. This helps identify whether a constraint originates in the plant, distribution network or customer equipment. It also provides a stronger basis for investigating performance degradation.
Thermal Headroom Needs a Defined Measurement Boundary
A cooling provider and its customer can interpret the same capacity figure differently because they may use different system boundaries. The provider might measure heat-removal capacity at a central heat exchanger. Meanwhile, the customer needs a guaranteed flow rate and coolant temperature at the rack inlet. These figures describe different points in the cooling chain. Equipment performance and distribution losses can affect the conditions ultimately delivered to the rack. Heat exchanger approach temperature influences the relationship between facility-side water and the coolant supplied to IT equipment. Pressure drops, flow imbalance and equipment-specific requirements can introduce further restrictions. Operators should define the measurement point, operating conditions and calculation method before assigning a commercial value to remaining capacity. Agreements should also explain how the parties will handle sensor uncertainty and missing telemetry. They should establish a process for resolving disagreements between facility-level and rack-level measurements. A defined boundary turns thermal headroom into a measurable operating commitment. Customers can then assess that commitment against their actual workload requirements.
What Happens When Cooling Demand Exceeds the Available Margin?
When a cooling system approaches a defined operating limit, the operator may need to adjust equipment power, restrict new workloads or redistribute demand. The appropriate response depends on the hardware, available controls, contractual commitments and severity of the constraint. Some systems can reduce power in response to temperature conditions. Others may require operator intervention before equipment reaches its operating limits. These measures can protect hardware, but they may also reduce throughput or increase job completion times. A customer running time-sensitive inference services could experience a different business impact from one whose training schedule allows work to pause and resume. The cooling provider must distinguish between protecting infrastructure and maintaining promised service levels. Contracts should explain when thermal constraints permit workload restrictions. They should also specify how the provider communicates those restrictions and whether resulting performance losses affect service commitments. Customers should establish whether the provider can restrict workloads selectively or must follow a predefined allocation policy. These provisions become important when several workloads compete for limited cooling capacity.
Cooling Failures Require More Than an Uptime Promise
A service-level agreement focused exclusively on server availability may not fully describe the consequences of a cooling constraint. Servers can remain powered on while thermal restrictions reduce their operating performance. Customers may therefore have available hardware that delivers less compute than expected. This distinction matters for AI workloads because training throughput, inference latency and job completion time can depend on sustained accelerator performance. A contract should define whether the provider measures availability at the infrastructure level, the compute service level or both. It should also explain how thermal restrictions affect those measurements. The agreement should distinguish a facility-wide cooling failure from a local distribution problem affecting one customer or rack. Incident records should identify the affected equipment, measured operating conditions, duration of the restriction and corrective actions taken. These records can help establish whether the provider applied its allocation policy consistently. Clear incident definitions and reporting requirements prevent performance losses from remaining commercially invisible simply because the servers never shut down.
Designing Contracts Around Shared Cooling Constraints
AI infrastructure changes over time as operators replace servers, increase rack density, modify power limits or introduce equipment with different cooling requirements. A configuration that operates comfortably within an existing thermal envelope may create new constraints after a hardware refresh. This can happen even when the customer retains the same nominal number of GPUs. Providers should establish a technical review process for changes that materially affect heat output, coolant flow, supply temperature or pressure requirements. The process should identify who approves the change and what engineering evidence the provider needs. It should also determine whether the revised configuration requires additional cooling capacity. Customers should receive advance notice when a proposed change could reduce their reserved thermal margin or alter agreed operating conditions. Contracts should explain how the parties handle upgrades when the shared system cannot support every requested change simultaneously. A documented process helps prevent one customer’s hardware expansion from silently reducing another customer’s practical capacity. It also helps distinguish an infrastructure shortfall from a configuration that exceeds the original technical agreement.
Allocation Policies Should Include an Evidence Trail
A practical allocation policy should specify how the operator calculates available headroom and measures customer demand. It should also identify who can approve exceptions and how the operator protects capacity reserved for maintenance or failure scenarios. When demand approaches the available limit, the operator should record relevant measurements and explain how it allocated capacity across affected customers. Records can include coolant temperatures, flow rates, differential pressure, equipment power and the operating status of critical components. A consistent evidence trail helps customers understand whether a restriction resulted from their workload, another customer’s demand or a shared infrastructure limitation. It also supports technical audits and commercial dispute resolution. Neither party needs to rely entirely on verbal explanations after an incident. Providers should protect confidential customer information while sharing enough operational evidence to substantiate their decisions. This balance allows a shared facility to manage common infrastructure without forcing customers to accept an opaque capacity policy. It also gives operators a more defensible basis for reviewing allocation decisions and resolving disagreements.
What AI Infrastructure Buyers Should Establish Before Signing
Customers evaluating an AI infrastructure contract should ask how the provider translates installed cooling equipment into a specific commitment for their deployment. The answer should identify the relevant rack or distribution boundary, required coolant conditions and assumptions used to calculate supported heat load. Buyers should confirm whether the commitment remains valid when other customers reach their contracted demand simultaneously. An aggregate facility rating does not automatically guarantee every customer the same operating margin. Buyers should also ask what happens during maintenance, a critical component failure or a change in operating conditions. Where workload performance matters commercially, the contract should describe how thermal restrictions affect service measurements, incident reporting and remedies. Customers should establish whether their deployment can expand without competing for unallocated cooling capacity or triggering a new engineering review. These questions separate a reservation for computing hardware from a commitment to deliver that hardware under defined thermal conditions. The distinction matters when customers purchase capacity for long-running AI workloads that depend on predictable performance across a shared facility.
Treat Cooling Headroom as a Contracted Operating Boundary
The allocation of cooling capacity requires physical evidence and explicit contractual rules. Operators must understand the limits of their cooling loops, while customers need clarity about the conditions supporting their purchased compute capacity. A facility-wide cooling rating cannot resolve every allocation question because constraints may vary by equipment, operating condition and location. A sound agreement should define the customer’s entitlement, protect necessary operating reserves and establish a fair process for resolving competing demands. It should also require timely communication when changes in hardware, workload demand or equipment availability threaten the agreed operating envelope. These provisions cannot eliminate every thermal constraint, but they can make responsibility and decision-making more predictable. For AI infrastructure buyers, the essential question is not simply whether the provider has installed enough cooling equipment. Buyers need to know whether the provider can demonstrate that the promised capacity will remain available under the conditions covered by the contract. That is the level of clarity required when several customers depend on one cooling loop and each expects its computing capacity to remain usable when demand rises.









