Skip to content
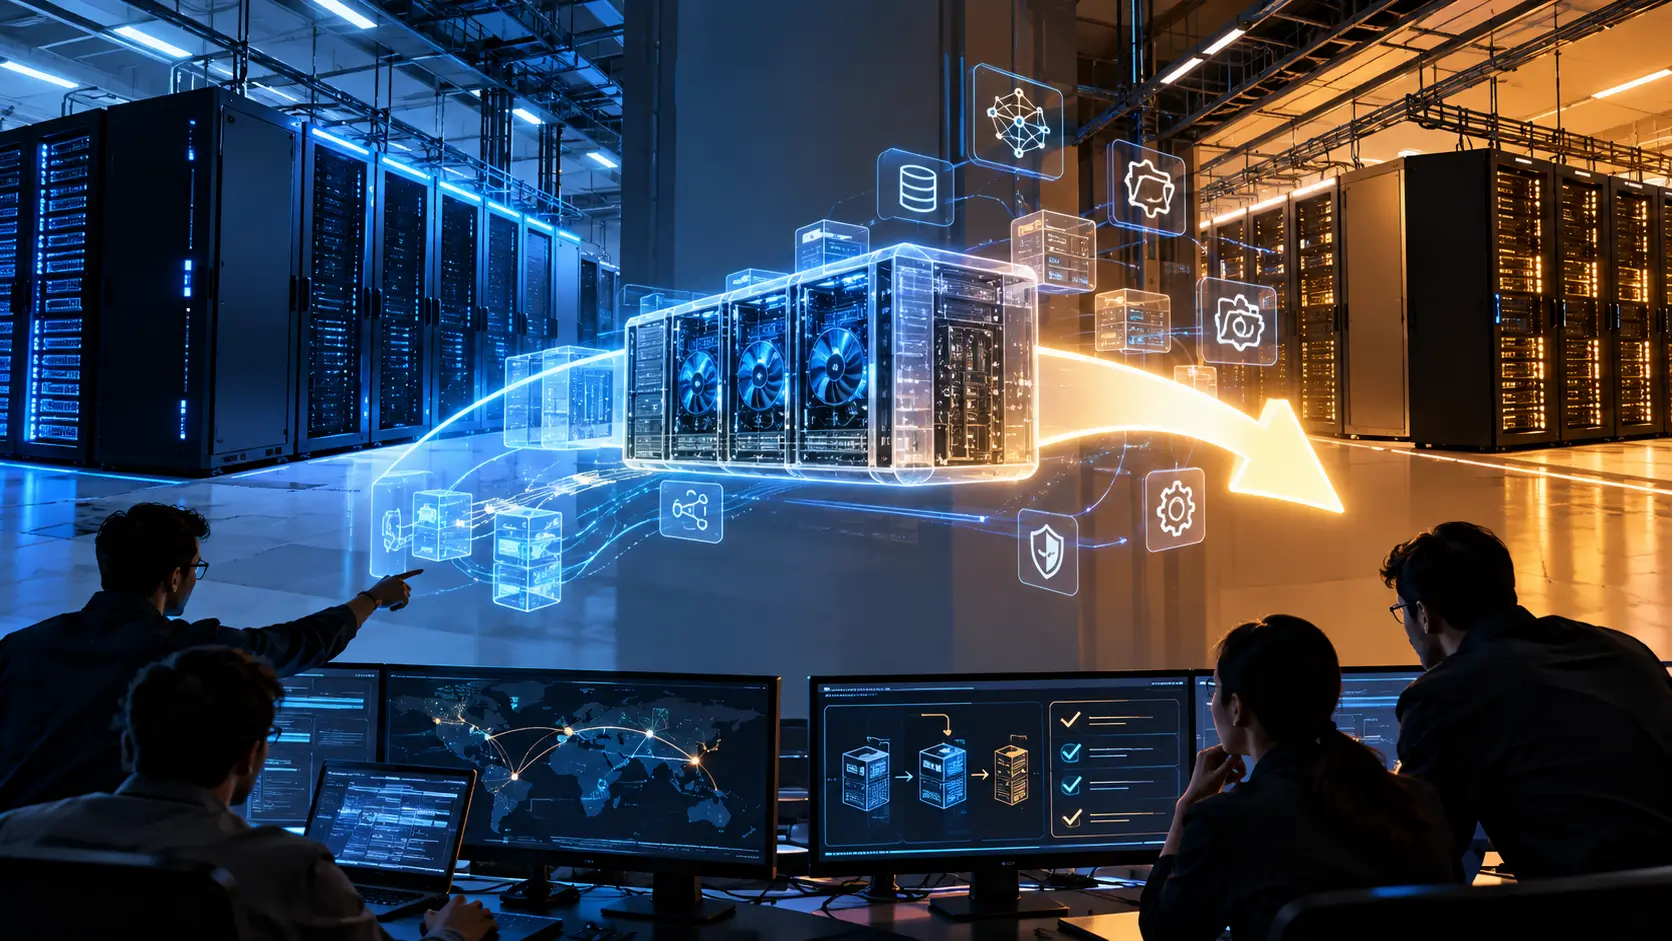
A reserved GPU allocation can look remarkably stable from the customer side, even when important infrastructure changes underneath it. Capacity appears in a portal, workloads enter queues, storage remains accessible, and the commercial agreement continues without visible disruption. Behind that interface, the physical environment may depend on a separate relationship between the neocloud and its data center partner. That relationship can change while the customer’s requirement for compute remains exactly the same. The resulting challenge is not necessarily the disappearance of GPUs, but the movement of infrastructure supporting those GPUs. For buyers, that difference can determine whether a supplier change remains invisible or becomes a workload migration.
A customer may retain the contractual right to compute while the physical operating environment changes around that allocation. Racks may move, network paths may change, storage relationships may need rebuilding, and cooling arrangements can differ between locations. These differences do not automatically make replacement infrastructure worse, and another environment may support the workload equally well. However, hardware identity alone cannot establish that the surrounding operating conditions remain equivalent. The customer needs to know which characteristics of the original service must survive the transition. That question turns a supplier change into an infrastructure continuity issue rather than a simple procurement event.
An AI cluster is also more than a collection of accelerators attached to an internet connection. Distributed workloads can depend on coordinated compute, storage access, east-west communication, management networks, external connectivity, and reliable orchestration. Several of these functions may use different infrastructure paths because they serve different operational purposes. A relocation can preserve the accelerator class while changing parts of the system surrounding those accelerators. Those changes may matter differently for training, inference, development, or other workload patterns. C-level buyers therefore need to separate capacity entitlement from capacity continuity before committing important workloads to reserved compute.
The Meaning of Equivalent Capacity Can Change
From a procurement perspective, replacement looks straightforward when the customer receives the same accelerator class after a partner change. The commercial inventory may appear unchanged, and the provider can still show the contracted compute inside its control plane. Technical equivalence requires a broader assessment because distributed AI depends on more than processor specifications. Network topology, storage accessibility, management systems, and the physical deployment environment all contribute to usable capacity. A replacement cluster can reproduce those characteristics through a different design without copying the original infrastructure exactly. The important question is whether material workload conditions remain within the boundaries agreed with the customer.
High-performance AI clusters depend heavily on communication between compute nodes during many distributed workloads. Storage paths can also influence operations because training requires access to datasets, checkpoints, model artifacts, and other workload state. Management networks support administration and control independently from the traffic generated by the workload itself. A partner change can therefore alter infrastructure relationships even when accelerator specifications remain unchanged. None of these differences proves that the new environment will perform worse. They simply show why processor identity cannot serve as the only definition of equivalent capacity.
The contract should identify characteristics that matter without dictating every engineering choice behind the neocloud service. Accelerator class, cluster topology, storage accessibility, network behavior, geography, security boundaries, and recovery expectations may all deserve consideration. Not every workload needs every characteristic protected to the same degree. A loosely coupled workload can tolerate infrastructure changes that would matter more to tightly coordinated training. Procurement should therefore connect equivalence requirements directly to the workload rather than create an unnecessary technical checklist. That approach preserves provider flexibility while giving the customer a clearer standard for evaluating replacement capacity.
Thermal conditions can influence whether replacement capacity is practical
The thermal environment adds another dimension because dense accelerator systems can depend on tightly coordinated heat-removal infrastructure. A destination may use different cooling distribution arrangements, rack configurations, interfaces, or operating procedures from the original environment. Those differences do not automatically create reliability problems when the replacement infrastructure supports the required operating conditions. However, they can influence placement, maintenance procedures, recovery options, and the way systems are grouped physically. Customers rarely need to specify the engineering design used to remove heat from the equipment. They do need confidence that the replacement environment can sustain the configuration associated with their reserved capacity.
Cooling also interacts with physical placement because not every rack position necessarily supports every equipment configuration in the same manner. A provider may need to reposition equipment, rebuild connections, change rack groupings, or adjust operating procedures during relocation. These changes can occur without reducing the quality of the service. Still, they may affect how quickly capacity can be restored after maintenance or another infrastructure event. A customer expecting a coordinated cluster should understand whether the destination can support that allocation as designed. The relevant commercial question concerns usable compute, not the engineering label attached to the cooling system.
A stronger capacity definition therefore focuses on operating outcomes rather than demanding identical mechanical infrastructure at every location. The provider can retain freedom to change infrastructure while remaining responsible for meeting agreed workload conditions. Customers gain protection against substitutions that preserve accelerator specifications while materially changing the service they expected. This distinction becomes especially useful during a partner transition because technical teams gain an objective target for validation. It also reduces arguments about whether two physical environments must look identical. They do not need to look identical when both environments satisfy the agreed requirements of the workload.
Capacity Portability Is Not Workload Portability
Cloud interfaces can make infrastructure appear highly portable because resources often look similar through a common control plane. AI workloads can carry much more state than the visible compute allocation suggests. Datasets, checkpoints, model artifacts, container images, secrets, networking rules, scheduler configuration, and monitoring integrations can all accompany production workloads. Moving the contractual entitlement to GPUs does not automatically relocate those dependencies. The provider may supply replacement compute while the customer still needs to move or recreate parts of the workload environment. Procurement should distinguish those responsibilities before an infrastructure transition begins.
The distinction becomes clearer when the customer has built operational processes around one established deployment. Network policies may reference existing endpoints, while deployment automation may assume particular storage or access configurations. Monitoring systems can also depend on integrations created during the original rollout. A new environment can expose these assumptions even when the underlying software remains compatible. The workload may therefore need validation before replacement capacity becomes production-ready. Capacity portability describes the provider’s ability to supply compute elsewhere, while workload portability describes the customer’s ability to use it.
This difference should influence how migration obligations appear in the contract. Customers need to know which components the provider will recreate and which remain under customer control. The agreement should also identify responsibilities for storage preparation, network changes, data transfer, testing, and application validation. Provider-initiated relocation does not automatically mean the provider can perform every application-specific task. Equally, customers should not inherit infrastructure work simply because some workload configuration remains under their control. Clear boundaries allow both teams to prepare without discovering responsibility gaps during cutover.
Checkpoints can protect training progress during infrastructure change
For training workloads that support checkpoint recovery, saved state can reduce the amount of work lost after interruption. Its usefulness depends on whether the destination can access and use the relevant checkpoint when recovery begins. A checkpoint stored only within an inaccessible source environment provides limited protection after that environment disappears. Migration planning should therefore identify the recoverable workload state before disruptive work begins. Teams should also verify that the destination can access that state through the intended storage architecture. This turns checkpoint planning into part of infrastructure continuity rather than only a routine training practice.
Checkpoint availability does not guarantee immediate workload recovery because the destination still needs the required software and supporting infrastructure. Network configuration, storage access, orchestration, permissions, and runtime compatibility can all influence successful resumption. The provider and customer should understand which of these elements each side controls. That knowledge becomes important when troubleshooting a failed restart after migration. Otherwise, accelerator availability can be mistaken for complete workload readiness. A recoverable workload needs both suitable compute and access to the state required for continued operation.
Inference workloads create a different continuity problem because important state can exist outside the accelerator fleet. Model repositories, routing layers, application services, databases, queues, and caches may all participate in serving requests. Moving GPU capacity without coordinating those dependencies can leave a technically healthy destination unable to support normal production traffic. A staged transition can help when the architecture supports temporary coexistence between environments. Teams can validate destination behavior before directing broader workload traffic toward it. The migration plan should define that process rather than assume every AI workload can follow the same cutover method.
Hardware Relocation and Capacity Reassignment Create Different Risks
One migration path involves physically moving servers and related equipment from the existing environment into another location. The hardware may remain unchanged, but systems generally need installation and reconnection before they return to usable inventory. Power, cooling, networking, management access, and storage connectivity may all require re-establishment at the destination. The customer should therefore avoid assuming that possession of the same physical accelerators guarantees continuity of the same cluster. Supporting topology can matter just as much as the identity of individual servers. Physical relocation needs a migration plan that addresses workload sequencing, validation, recovery, and customer communication.
The provider should also establish when relocated hardware becomes usable capacity again. Initial power-up demonstrates that equipment can operate, but it does not prove that the entire workload environment is ready. Network communication, storage access, management systems, monitoring, and orchestration may still require validation. Application teams may need additional checks before production jobs return. Acceptance criteria should therefore reflect the actual service promised to the customer. That prevents the commercial definition of readiness from becoming narrower than the technical conditions required to use the cluster.
Physical movement can also reduce rollback options as the transition progresses. Once equipment leaves the source environment, returning to the previous operating state may become increasingly difficult. Network routes may already be changing while storage and other supporting systems enter their own migration sequence. Customers should know when the move crosses that practical boundary. The provider should define what happens when destination validation fails after returning to the original environment becomes impractical. A clear fallback mechanism provides more protection than a vague promise that migration can simply be reversed.
Logical reassignment can preserve hardware availability but change infrastructure context
Another strategy involves assigning the customer to different infrastructure instead of physically moving the original servers. The provider can prepare replacement capacity while the original environment continues operating when resources and commercial arrangements permit. This approach may create a useful validation window before the customer gives up the original allocation. However, replacement hardware still needs to satisfy characteristics that matter to the workload. Network, storage, geography, security, and orchestration can all require assessment. A stable cloud interface does not automatically prove that these underlying characteristics remain unchanged.
Logical reassignment can also change resource identity even when customer-facing workflows remain familiar. Network endpoints may differ, storage relationships can require modification, and access policies may need review. Deployment automation might need adjustment if the destination exposes different infrastructure details. None of these changes necessarily creates a serious migration problem. Their importance depends on how tightly the workload depends on the original environment. The provider should therefore disclose material changes early enough for customer teams to prepare.
Some transitions may combine logical reassignment with physical relocation. Replacement capacity can handle part of the workload while specialized infrastructure moves separately. This hybrid model can reduce dependence on a single cutover, but it introduces temporary complexity between source and destination environments. Shared data, routing, monitoring, and identity controls may need to operate across both locations during that period. Clear ownership becomes particularly important because several infrastructure layers may be changing at once. The customer should judge success against agreed workload conditions rather than the completion of any single physical migration task.
Cluster Identity Can Matter More Than Individual GPUs
Customers often purchase capacity by accelerator quantity because that unit is easy to understand commercially. Distributed AI workloads, however, can consume a coordinated cluster rather than a collection of independent processors. Communication between nodes may sit directly on the execution path of the workload. Storage access and orchestration can also depend on how resources are grouped. A replacement allocation can therefore preserve accelerator quantity while changing characteristics of the system around those accelerators. This does not make the replacement unsuitable, but it means equivalence needs a broader test.
Topology becomes particularly relevant when the customer expects a contiguous allocation for tightly coordinated work. A provider may possess sufficient aggregate hardware without having the same arrangement immediately available at the destination. It could potentially assemble capacity from different resource pools instead. Loosely coupled jobs may tolerate that arrangement better than workloads with substantial communication between nodes. Procurement should therefore distinguish general accelerator quantity from cluster characteristics when those characteristics matter. Without that distinction, provider and customer can reasonably interpret equivalent capacity in different ways.
The contract does not need to describe every physical switch or cable to protect the customer. It can instead define outcome-oriented characteristics associated with the purchased cluster. These may include communication behavior, storage access, geographic boundaries, or other workload-specific requirements. The provider remains free to implement those outcomes through a different physical design. Customer teams gain an objective basis for validating the replacement. That balance avoids unnecessary engineering restrictions while preserving characteristics that affect the value of reserved capacity.
Fragmentation can change recovery and placement assumptions
Capacity fragmentation can matter even when aggregate accelerator availability remains unchanged. A workload spread across different infrastructure domains can face different communication, placement, and recovery conditions from one deployed as a coordinated cluster. Neither arrangement is automatically better for every application. The importance depends on workload design and the service characteristics the customer purchased. Customers should therefore understand whether a partner transition changes the logical grouping of their allocation. That information helps technical teams determine whether additional validation is necessary.
Placement can also influence recovery after hardware or infrastructure problems. Replacement resources may need to satisfy both accelerator requirements and the topology expected by the workload. A provider with broad spare inventory may still need time to recreate a particular cluster arrangement. Customers should avoid assuming that total provider inventory equals immediately usable replacement capacity. The commercial agreement should clarify what form of replacement the provider owes after a material infrastructure change. This distinction makes recovery expectations more realistic.
Acceptance testing should reflect these cluster-level requirements. Testing a few reachable GPUs cannot demonstrate the behavior of an entire distributed environment. Validation may need to examine communication, storage access, orchestration, external connectivity, monitoring, and representative workload execution. The precise test should follow the customer’s architecture rather than a generic checklist. Both parties benefit from agreeing on that test before migration begins. It turns equivalent capacity into a technical condition that can be demonstrated rather than a commercial assertion.
Data Movement Can Become the Hidden Critical Path
Replacement accelerators can become visible through a cloud control plane while required workload data still resides elsewhere. AI environments may depend on datasets, checkpoints, model weights, logs, configuration repositories, and intermediate outputs. Some of that information may need relocation, while other data can remain accessible through another architecture. The correct choice depends on workload requirements rather than a universal migration rule. Customers should identify these data dependencies before the provider begins a major infrastructure transition. Otherwise, usable compute can arrive before the information required to use it.
Storage architecture makes this issue more complex because workloads can use different storage layers for different purposes. Active datasets, checkpoints, artifacts, and retained outputs do not necessarily share identical access patterns. Moving everything through one undifferentiated bulk-copy process may therefore provide an incomplete migration strategy. The destination must support the storage relationships required by the workload after cutover. Data integrity and version consistency also matter when source applications continue changing information during migration. Teams need a clear point at which the destination becomes authoritative.
Data transfer can also interact with the migration timeline. The provider may be able to provision replacement compute before the customer can complete necessary data movement. In another case, replicated data may already exist while network or compute preparation remains unfinished. A useful migration plan sequences these dependencies rather than assuming every component becomes ready simultaneously. That sequencing should appear in the runbook and acceptance process. C-level buyers need visibility into the critical path because delays outside the GPU layer can still postpone usable capacity.
Data responsibilities need explicit ownership
Provider-initiated migration does not eliminate customer responsibilities for workload information and application-specific dependencies. The neocloud may control infrastructure while the customer controls datasets, application configuration, credentials, or deployment processes. Both sides therefore need a shared understanding of migration ownership. The agreement should identify who prepares destination storage and who initiates required transfers. It should also define who verifies data availability and resolves access problems. Those boundaries reduce confusion when compute becomes available before the workload can use it.
Security responsibilities deserve the same clarity during transfer. Data may cross a different infrastructure path while moving between source and destination environments. Customers need the agreed protections to remain applicable during that transition. The provider also needs enough information to support transfer without assuming responsibility for customer-controlled application behavior. A responsibility matrix can make these boundaries visible without prescribing every implementation detail. The objective is clear ownership rather than unnecessary contractual complexity.
Data portability also matters if migration ultimately fails. A customer may need to move workload state somewhere other than the provider’s proposed destination. Checkpoints, model artifacts, datasets, and configuration information can become essential to that exit. Portability expectations should therefore exist before an urgent transition begins. Providers can establish reasonable procedures without promising instant movement of every workload. Customers gain a defined path for retrieving the state needed to continue operations elsewhere.
Power and Cooling Equivalence Requires More Than Installation
Installing compute equipment demonstrates physical progress, but it does not establish complete operational readiness. The destination needs to support the intended configuration across electrical, thermal, network, storage, and management systems. Each of these layers can affect the provider’s ability to operate the cluster. A migration may change how equipment receives power or how infrastructure gets isolated during maintenance. Such changes do not automatically affect customer workloads. They still deserve validation when they alter characteristics incorporated into the service agreement.
Customers rarely need detailed knowledge of the internal electrical architecture supporting their allocation. Their concern is whether the environment supports the agreed operating conditions and recovery expectations. A technically compatible power arrangement can be completely acceptable even when it differs from the original design. Procurement should therefore focus on outcomes rather than demanding physical duplication. The provider retains engineering flexibility while remaining accountable for service behavior. This approach also keeps commercial requirements aligned with what the customer can meaningfully evaluate.
Maintenance behavior belongs in that assessment because infrastructure needs servicing throughout its operating life. A destination can support normal workloads successfully while using different maintenance procedures from the source environment. Those procedures may influence isolation, recovery, or the availability of replacement positions. Customers should care when such differences materially affect the contracted service. They do not need authority over routine engineering decisions that leave the service unchanged. The distinction keeps change control focused on customer impact rather than internal design.
Thermal validation should follow the workload configuration
Cooling readiness should be assessed against the deployed hardware configuration rather than broad claims about site capability. A destination can support advanced cooling infrastructure without necessarily supporting every possible rack arrangement identically. The provider needs to match equipment requirements with suitable deployment positions and supporting systems. Customers should therefore ask whether their assigned configuration has been validated in the destination environment. This is more useful than asking whether the entire building supports one cooling category. It connects thermal readiness directly to the capacity being purchased.
Thermal differences can also influence maintenance and recovery options. A replacement rack position may require compatible connections and supporting infrastructure before it can host the same equipment. This can affect how the provider responds when hardware needs relocation during maintenance. The customer does not need to manage those details directly. However, recovery commitments should account for any infrastructure constraints that materially affect the reserved cluster. A realistic service model acknowledges those dependencies rather than pretending every rack position is interchangeable.
Operational telemetry can help the provider validate the destination after migration. Compute, networking, storage, and supporting infrastructure all produce information useful for diagnosing abnormal behavior. Customers may not need direct access to every internal measurement. They need sufficient evidence that the replacement environment satisfies agreed acceptance criteria. That evidence can combine infrastructure testing with representative workload validation. The result is a stronger readiness decision than simply confirming that equipment has powered on.
Network Changes Can Alter the Character of AI Capacity
A customer-facing API can remain unchanged while the physical network beneath the service changes substantially. The destination may use different switching arrangements, cabling, routes, isolation boundaries, or storage connections. These differences can be perfectly acceptable when the resulting service meets agreed workload requirements. They should not be assumed irrelevant simply because the control plane looks familiar. Distributed workloads can depend on communication between nodes and access to external services. Network validation therefore belongs inside the migration process.
External connectivity deserves particular attention because AI workloads often interact with systems outside the GPU cluster. Data sources, application services, model repositories, databases, or other environments may remain elsewhere. Moving compute can change the routes used to reach those dependencies. Access controls or endpoint configuration may also require review. A cluster can pass internal health checks while remaining unable to reach something the production workload needs. End-to-end validation helps reveal these problems before final cutover.
Customer-controlled network configuration can become another source of delay. Allowlists, routing rules, private connections, certificates, or application settings may reference characteristics of the original environment. These dependencies are easy to overlook when they have remained unchanged for a long period. Migration planning should identify them before the provider retires the source environment. The neocloud can validate infrastructure under its control, while the customer validates external dependencies under its control. Both results are needed when those systems jointly determine workload readiness.
Network acceptance should focus on outcomes
Customers rarely benefit from specifying every network component used by their neocloud. Such requirements can freeze implementation choices without improving the workload outcome. An outcome-based approach instead defines the network behavior that materially matters to the service. The provider can then use another physical design when it satisfies those requirements. Migration testing provides the mechanism for checking that outcome. This preserves engineering flexibility while protecting workload expectations.
Representative testing should reflect the architecture of the customer’s workload. It can examine communication between relevant nodes, storage access, orchestration behavior, and external connectivity. Not every workload needs the same tests or acceptance thresholds. A development environment may have different requirements from a tightly coordinated training deployment. The contract should therefore avoid a generic definition of network equivalence. It should connect testing to the characteristics incorporated into the purchased service.
Management and control traffic also needs to work after migration. Provisioning, health monitoring, lifecycle management, access configuration, and orchestration depend on supporting systems beyond workload communication. A familiar portal can hide significant changes beneath these layers. Operational validation should therefore complement workload testing. The customer does not need visibility into every internal management component. It needs confidence that the provider can continue operating and supporting the contracted capacity.
Contract Language Determines How Much Infrastructure Can Change
A neocloud needs reasonable freedom to change its infrastructure without requesting customer approval for every engineering decision. Preventing routine changes could make normal operations unnecessarily rigid. Customers still need protection when a change materially alters characteristics incorporated into their capacity commitment. The contract should therefore separate ordinary infrastructure management from material service changes. Geography, topology, storage accessibility, connectivity, and migration interruption may matter depending on the workload. Materiality should follow customer impact rather than the visibility of the underlying engineering change.
Notification requirements can follow the same principle. Routine maintenance may need ordinary operational communication, while a major relocation can require earlier coordination. Customers may need time to save workload state, synchronize data, adjust networking, or schedule application changes. A single notification model cannot fit every infrastructure event. Contracts should therefore connect notice expectations to the scale and potential impact of the change. This gives customers preparation time without turning minor engineering work into a formal migration project.
Urgent infrastructure conditions can still make normal notice periods impractical. The contract should account for those situations instead of creating requirements that cannot always be met. An escalation process can preserve accountability when standard migration planning is impossible. Customers should know who communicates the change and what continuity process activates. Providers should know which obligations remain during an urgent transition. Clear exception handling makes the change-control framework more realistic.
Material change should be defined through workload consequences
Terms such as equivalent or comparable infrastructure can become ambiguous without an agreed method for evaluating them. Provider and customer may interpret those descriptions differently during a migration. Materiality works better when connected to observable service consequences. Changes affecting topology, connectivity, storage, location, security configuration, or workload operation can trigger additional review when those characteristics matter contractually. The provider remains free to change internal components that leave agreed outcomes intact. This approach protects the workload without freezing the infrastructure.
Performance also requires careful treatment because workload behavior can change for reasons unrelated to migration. Baseline testing offers a more grounded method for identifying meaningful differences. Teams can compare representative destination behavior with previously understood workload requirements. The goal is not to guarantee identical results under every operating condition. It is to identify material degradation associated with the replacement environment. That standard provides both parties with a more defensible acceptance mechanism.
Operating procedures can also create material changes even when steady-state workload behavior remains acceptable. Recovery, maintenance, provisioning, or support processes may differ at the destination. Those differences matter when they affect commitments important to the customer. Procurement should identify which operating characteristics genuinely deserve contractual protection. Everything else can remain under the provider’s normal engineering control. This keeps agreements technically meaningful without filling them with unnecessary infrastructure detail.
Geography Can Matter Even When the Interface Does Not Change
A partner transition can change physical geography while the customer continues using the same commercial product. Location can influence architecture, network connectivity, internal governance, and data-placement decisions. Its importance varies significantly between workloads. Some customers may need only an agreed region, while others may depend on tighter geographic boundaries. Procurement should define the required boundary instead of assuming one rule fits every deployment. The provider can then consider that requirement before selecting replacement infrastructure.
Network behavior can also change when compute moves farther from external systems. Distance alone cannot predict the result because routing and network architecture also influence communication. End-to-end testing is therefore more useful than assumptions based solely on geography. Customers should identify external relationships that form part of their workload baseline. Those paths can then be validated before source retirement. This allows location changes to be assessed through actual workload requirements.
Data placement adds another consideration because compute and data do not always move together. The customer may move some datasets while leaving others accessible through another path. Neither strategy is automatically superior. The appropriate choice depends on workload architecture, transfer requirements, and operational constraints. The provider needs to disclose enough about the destination for customers to make those decisions. Geography becomes commercially relevant when it materially changes those workload relationships.
Geographic footprint does not equal replacement capacity
A provider operating in several locations may appear naturally resilient to a data center partner change. Multiple locations can create useful options, but those options are not automatically interchangeable. The workload still needs suitable compute, data access, networking, orchestration, and contractual rights at the alternate destination. Another site can exist without being ready for the customer’s specific cluster. Physical capacity can also be committed to other workloads. Buyers should therefore distinguish geographic presence from contractually available replacement capacity.
Data architecture often determines how practical another location becomes. Compute can sometimes be reassigned faster than large or operationally sensitive datasets can move. Replication and checkpoint placement can shorten that path when the workload architecture supports them. Other deployments may rely on a planned transfer after relocation becomes necessary. The correct strategy depends on continuity requirements rather than a universal design. Multi-site capacity becomes useful when the transition path is understood.
The commercial agreement should also clarify whether another location represents guaranteed replacement or merely a possible alternative. This distinction matters when a broader infrastructure change affects several customers simultaneously. A contract cannot manufacture physical capacity that does not exist. It can define the provider’s obligations when equivalent replacement cannot be supplied. That gives customers a more realistic understanding of continuity. A map of available locations cannot provide that certainty by itself.
Overlapping Capacity Can Create a Controlled Migration Window
Migration becomes easier to control when teams can test the destination before losing the source. Temporary coexistence can provide that opportunity when infrastructure availability and commercial terms allow it. The customer can validate data access, network paths, orchestration, and representative workloads in the replacement environment. Both environments do not need to carry identical production traffic throughout the process. The purpose of overlap is to preserve options during validation. Procurement should establish whether such capacity can be available during provider-initiated relocation.
Overlap can also reduce pressure around cutover decisions. Technical teams can investigate unexpected destination behavior without immediately operating against a disappearing source environment. This does not remove migration risk because some problems emerge only after production traffic shifts. It does create more room for testing and remediation. Customers should define which tests need completion before the original allocation enters retirement. The provider can then plan temporary capacity around an agreed validation process.
Progressive migration can also help when different workloads have different sensitivity to infrastructure change. Representative jobs can move first while teams observe destination behavior. More demanding workloads can follow after earlier validation provides confidence. This approach will not suit every architecture, especially when tightly connected systems require coordinated movement. The migration method should follow workload dependencies rather than a fixed provider template. Flexibility in sequencing can be valuable when the transition affects several workload types.
The cost of overlap needs an owner
Temporary duplicate infrastructure can create commercial questions even when its technical value is clear. Both environments may consume compute, storage, networking, and engineering resources during migration. The contract should explain how those costs are treated when the provider initiates the move. Customer-initiated architectural changes may justify a different cost model. The objective is not to demand free capacity in every scenario. It is to prevent migration economics from remaining undefined until the transition is already underway.
Engineering effort also needs consideration because validation can involve teams on both sides. The provider may need to build replacement infrastructure and support data or network transitions. Customer teams may need to validate applications, update configuration, and schedule workload movement. Commercial terms should distinguish work required to preserve the existing service from optional redesign requested during migration. This boundary protects both parties. It also makes the effective economics of reserved capacity easier to understand before commitment.
C-level buyers should include these migration economics when comparing capacity agreements. A low headline compute price does not reveal who carries the cost of provider-driven infrastructure change. A higher price does not automatically provide stronger migration protection either. Contractual responsibility determines much of that difference. Buyers should therefore evaluate compute pricing alongside overlap, migration support, data movement, and fallback terms. The resulting comparison reflects the complete operating commitment rather than only accelerator cost.
Rollback Needs a Defined Expiration Point
A migration plan can promise rollback while leaving unclear how long that option remains practical. The source environment eventually reaches a stage where returning becomes difficult or impossible. Hardware may be disconnected, network routes can change, and data may begin changing only at the destination. Teams should therefore define rollback checkpoints before migration begins. Decision authority should also be clear. Otherwise, the option can disappear while both sides still assume it exists.
The rollback boundary should follow technical conditions rather than an arbitrary statement that reversal remains possible until migration ends. The provider should identify when source capacity stops being a viable recovery environment. Customers can schedule their highest-risk validation before that milestone. Both sides also need criteria for deciding whether destination problems justify rollback. Minor issues may be easier to remediate in place. Serious failures can require a different response while the source remains usable.
Once rollback ends, incident management changes fundamentally. Problems must generally be solved in the destination or through another agreed alternative. The customer should know that shift has occurred. The contract should also describe the process that applies if destination capacity still fails material acceptance criteria. This creates a bridge between technical rollback and commercial remedies. Treating them separately prevents one mechanism from being mistaken for the other.
Workload state complicates reversal
Data state can make rollback harder even while the original infrastructure technically remains available. Training or inference workloads may create new information after cutover. The destination can then become authoritative for checkpoints, logs, artifacts, queues, or application state. Returning to an older source copy may require reconciliation rather than a simple restart. Migration planning should identify which state needs to follow the workload back. This makes rollback a data problem as well as an infrastructure problem.
Teams should also decide when synchronization between environments ends. Maintaining both copies indefinitely can create complexity and cost. Ending synchronization too early can weaken the ability to reverse the migration. The appropriate boundary depends on workload architecture and risk tolerance. Customers need enough visibility to understand the trade-off. Providers need a practical endpoint for operating the old environment.
A rollback clause focused only on accelerator access may therefore provide incomplete protection. The customer needs to understand whether relevant workload state can accompany the reversal. This does not require every temporary file or cache to move. It requires identification of state essential to continued operation. That definition should exist before cutover. Otherwise, rollback can remain contractually available while becoming operationally useless.
Acceptance Testing Should Define When Capacity Is Ready
Replacement resources may appear in the customer’s account before the workload is ready to use them. Provisioning demonstrates that the platform can expose compute. It does not prove that every storage path, network dependency, application integration, or monitoring process works correctly. Acceptance criteria should therefore reflect the characteristics important to the customer’s workload. The tests can be agreed before migration begins. This prevents either party from redefining readiness after technical problems appear.
Representative workload testing provides more useful evidence than a simple hardware health check. Training customers may need to verify communication, checkpoint access, orchestration, and sustained workload behavior. Inference deployments may care more about application connectivity, model access, routing, and recovery. Development workloads can require a lighter acceptance process. The test should match the purchased service rather than apply one generic standard. That approach also prevents unnecessary testing of characteristics irrelevant to the customer.
Operational visibility belongs inside this process because post-migration troubleshooting needs reliable evidence. The provider should be able to distinguish problems across compute, networking, storage, and management systems. Customers do not need unrestricted access to internal telemetry. They need confidence that the provider can diagnose the service they purchased. Establishing an operational baseline during migration can support that objective. It gives support teams a reference when behavior changes after cutover.
Migration closure should follow operational stability
Initial acceptance and final migration closure do not need to occur at exactly the same moment. Some problems emerge only after sustained production use. A defined observation period can keep the transition under elevated attention while the destination settles into normal operation. The source does not necessarily need to remain available throughout that period. Rollback and observation can have separate timelines. The agreement should make those milestones clear.
The observation period should not become an indefinite extension of migration. Both parties need objective criteria for moving into normal operations. Outstanding defects can be categorized according to their effect on the service. Minor issues may remain open without preventing closure. Material problems may require remediation before normal support begins. This structure gives technical teams flexibility without making acceptance subjective.
A migration should therefore end according to agreed operational milestones rather than the completion of physical moving work. The provider needs a clear point at which the transition project closes. The customer needs evidence that the replacement capacity supports the contracted workload conditions. Those goals can coexist through predefined acceptance criteria. A shared definition of completion reduces commercial disputes. It also creates a reusable model for future infrastructure changes.
Source Decommissioning Is a Customer-Relevant Milestone
Source retirement removes the simplest path back to the previous operating state. That makes decommissioning one of the most consequential migration milestones. Destination capacity may already be running while hidden dependencies remain unresolved. Stable initial operation does not prove that every data path or recovery procedure has been validated. Source retirement should therefore follow agreed migration conditions where the commercial arrangement permits. Customers need to understand those conditions before the move begins.
Relevant conditions can include successful workload migration, usable data, acceptable target behavior, and removal of unintended source dependencies. The precise list should reflect the customer’s architecture. A simple workload may need fewer checks than a complex distributed environment. Providers should not keep obsolete infrastructure operating indefinitely without a defined reason. Customers should not lose meaningful rollback merely because the destination has powered on. An agreed decommissioning trigger balances those interests.
Commercial timelines can still create pressure because the provider may need to leave the original environment by a fixed date. That constraint should become visible early in migration planning. Customer validation can then be scheduled around the actual source-retirement window. The contract can define escalation when destination acceptance remains incomplete as the deadline approaches. This is more useful than discovering the constraint during final cutover. C-level buyers should regard source retirement as part of continuity planning rather than an invisible provider milestone.
Decommissioning can reveal stranded dependencies
Some dependencies become visible only after teams believe the main workload has moved. Traffic may still reach storage, management services, repositories, or other systems associated with the source. Monitoring during transition can help identify those remaining relationships. Teams should investigate relevant source activity before declaring the old environment unnecessary. This reduces the chance of discovering a hidden dependency after decommissioning. It also improves understanding of the workload architecture.
Customer teams should preserve a record of material changes discovered during migration. That record can document altered dependencies, accepted exceptions, new network relationships, and revised operating assumptions. It does not need to reproduce confidential provider infrastructure details. Its purpose is to preserve knowledge about the customer’s workload. That information can become valuable during later incidents or another migration. Each transition should improve architectural understanding rather than erase it.
The migration record can also support future procurement and renewal decisions. Technical leaders can see which infrastructure characteristics proved important during the move. Procurement can determine whether those characteristics deserve stronger protection in the next agreement. Teams can identify portability problems while the lessons remain fresh. This turns migration experience into a better capacity strategy. Infrastructure continuity improves when knowledge survives alongside the workload.
Exit Rights Matter When Equivalent Capacity Cannot Be Recreated
Some migrations may reach a point where the destination cannot reproduce a characteristic the customer considers essential. The issue might involve topology, connectivity, data placement, location, workload compatibility, or another agreed condition. The contract needs a process for that scenario. It does not need to assume provider fault. Infrastructure transitions can encounter constraints even when both sides act reasonably. What matters is avoiding an indefinite commitment to unsuitable replacement capacity.
Possible remedies depend on the commercial relationship and should not be treated as universal requirements. The provider might offer another capacity pool, additional remediation, another destination, or another negotiated solution. An agreement can also address what happens to affected commitments when no acceptable substitute exists. These choices belong in contract negotiation rather than emergency migration discussions. Both sides benefit from knowing the process in advance. The customer gains an alternative to accepting capacity that fails agreed requirements.
Technical rollback and contractual fallback should remain separate concepts. Returning to the original environment is a technical action available only while that environment remains viable. Commercial fallback applies when technical reversal is unavailable or insufficient. Confusing these mechanisms can create false confidence. A contract may promise remedies without making source restoration possible. Procurement should understand exactly what protection each mechanism provides.
Exit architecture depends on data portability
Leaving affected capacity does not solve the problem if the workload state cannot move with the customer. Model artifacts, checkpoints, datasets, configuration information, and other customer-controlled state may be required elsewhere. Portability expectations should therefore exist before an urgent exit begins. The mechanism can reflect the service architecture rather than promise instant transfer. Customers should know which state they can retrieve and through which process. Providers should know which migration assistance they have agreed to supply.
This becomes particularly important when provider migration and customer exit happen simultaneously. The original environment may already be approaching decommissioning while the customer decides against the proposed replacement. Time can therefore become a significant operational constraint. Clear export and transfer procedures reduce uncertainty during that period. Customers can prepare another destination while the provider manages its own infrastructure transition. The two processes remain connected without becoming indistinguishable.
Exit planning also discourages unnecessary dependence on undocumented local configuration. Customer teams can keep deployment definitions, workload configuration, and important operational knowledge under deliberate control. Not every provider-managed component can or should become customer-portable. The objective is to understand those boundaries before they become urgent. A workload does not need to be universally portable to have a credible exit path. It needs a practical method for preserving the state and configuration required to continue operating elsewhere.
Multi-Site Capacity Does Not Automatically Solve Partner Risk
Multiple provider locations can create useful options during infrastructure change. Their existence does not automatically provide immediate continuity. The customer still needs suitable compute, data access, networking, orchestration, and commercial rights at the alternate destination. A tightly coupled cluster may not fit any available resource pool without modification. Data may also require movement before the workload can resume. Multi-site infrastructure therefore needs a usable transition path.
Customers should understand whether alternate capacity forms part of their continuity design or merely exists within provider inventory. The distinction becomes important during a broad infrastructure transition. Several customers may seek replacement resources at the same time. Physical capacity can exist without being contractually reserved for one particular customer. Procurement should clarify what the provider actually commits to supply. Geographic diversity alone cannot answer that question.
The workload architecture should also determine how much preparation another site requires. Some deployments can recreate quickly from portable configuration and accessible data. Others may depend heavily on infrastructure-specific relationships. Neither architecture is automatically inappropriate. The customer simply needs to understand the consequences. Continuity planning works best when it reflects actual dependencies rather than assumptions about geographic redundancy.
Portability needs periodic validation
A migration plan can become outdated while the workload evolves. New data pipelines, access controls, application integrations, and orchestration changes can create dependencies that did not exist originally. Technical teams should therefore revisit portability assumptions periodically. This does not require repeated full migrations. Targeted tests can validate important deployment, data, and connectivity assumptions. The objective is keeping the transition path credible.
Renewal provides a natural opportunity for this review. The customer can compare the current workload with the architecture that existed when the original capacity agreement began. Procurement can then update migration requirements where necessary. Technical teams can identify dependencies that have become more important. The provider can explain changes to its own operating model. This keeps contractual continuity aligned with the workload actually running.
Portability should therefore be treated as an architectural property rather than a binary feature. A workload can become easier or harder to move as its dependencies change. Teams can improve portability by documenting configuration, preserving workload state, and understanding external connections. Provider support can improve the transition path as well. Neither side controls the complete problem alone. A credible migration strategy combines provider capability with customer architectural awareness.
Procurement Should Ask About Migration Before Failure
A data center partner change does not need to result from catastrophic infrastructure failure. Commercial relationships can evolve, deployment requirements can change, and providers can revise infrastructure strategies. Customers should therefore treat migration capability as part of the possible lifecycle of reserved AI capacity. This produces more useful procurement questions than focusing only on disaster scenarios. Buyers can ask how planned infrastructure changes are managed. The discussion then becomes operational rather than speculative.
Procurement should ask how the provider handles notice, data movement, validation, cutover, rollback, and source retirement. It should also ask which responsibilities remain with the customer. These questions do not imply distrust of the provider. They acknowledge that infrastructure relationships can change during a long compute commitment. The answers reveal how mature the service is at handling change. They also expose assumptions that ordinary availability language may leave hidden.
A hypothetical migration scenario can make the discussion concrete before the contract is signed. The provider can explain how replacement capacity would be prepared and validated. Customer teams can identify which dependencies would require their participation. Both sides can discuss whether overlap would be available and how costs would be handled. They can also define what happens if equivalent capacity cannot be achieved. This exercise turns abstract continuity language into an operating model.
Ownership should not be confused with operational control
A neocloud can use external infrastructure while maintaining strong control over its customer-facing service. Physical ownership alone does not determine migration capability. Providers can still control hardware deployment, networking, monitoring, orchestration, and customer support across externally operated environments. Conversely, owning infrastructure does not automatically guarantee workload portability. Customers should evaluate operating capability rather than rely on ownership as a shortcut. The important question is how the service handles change.
Relevant evidence includes the provider’s ability to understand infrastructure dependencies and build replacement environments. Customers should also examine how the provider validates workloads and manages cross-domain incidents. Data and network transition processes deserve similar attention. The provider should maintain clear customer-facing responsibility even when several underlying parties participate. This keeps supplier complexity from becoming the customer’s operational burden. It also creates a cleaner accountability model during migration.
The customer’s responsibilities need equal clarity. Application validation, customer-controlled data, external dependencies, and workload configuration may remain outside the provider’s direct control. The provider cannot reasonably guarantee systems it does not operate. Customers should therefore avoid contracts that create unrealistic expectations on either side. Clear boundaries produce stronger continuity than broad promises. Both teams know what they must do when infrastructure changes.
Renewal Should Revisit the Assumptions Behind Reserved Compute
An AI workload can change significantly during a long capacity commitment. A deployment that began as experimentation may develop persistent data, external dependencies, and complex orchestration. Operating teams can also build procedures around the established environment. These changes may increase migration work even when the underlying application remains portable in principle. Renewal should therefore revisit infrastructure assumptions rather than simply extend compute quantity. The customer needs to understand the workload that exists now.
Technical teams should participate directly in that review. They know which storage paths, network integrations, model repositories, deployment processes, and monitoring tools have become important. Procurement records may not capture dependencies created after the original deployment. Bringing engineering knowledge into renewal closes that gap. Commercial teams can then decide which characteristics deserve contractual protection. Incidental infrastructure details can remain outside the agreement.
This process also prevents unnecessary over-specification. Engineers can distinguish requirements that genuinely affect workload continuity from characteristics that merely describe the current environment. Procurement can protect the former without freezing the latter. The provider retains room to evolve its infrastructure. The customer gains protection around conditions that actually matter. Renewal becomes a continuity review rather than only a pricing discussion.
Exit paths should remain credible as workloads grow
Workload growth can make migration more difficult than it appeared when the original agreement began. Datasets may expand, dependencies can multiply, and operating processes can become more specialized. None of these developments automatically creates lock-in. They can increase the effort required to relocate the workload. Customers should understand that change before signing another long commitment. Stable operating periods provide the best opportunity for that assessment.
Renewal should therefore test whether data, configuration, and deployment processes remain portable enough for the customer’s objectives. Teams can review checkpoint strategies and external network dependencies. They can also examine whether alternate capacity would require significant architectural changes. Problems discovered during renewal can be addressed without migration pressure. Problems discovered during an urgent provider transition are harder to negotiate. Timing matters almost as much as technical capability.
The provider can contribute by explaining how its infrastructure model has evolved. New locations, network designs, storage options, or deployment methods may improve future portability. Other changes may require customers to update assumptions. A transparent review benefits both sides. It aligns technical architecture with the next commercial commitment. Capacity renewal then becomes an opportunity to reduce future transition risk rather than simply preserve the status quo.
AI Capacity Becomes More Valuable When Continuity Is Defined
The strongest AI capacity agreement does not need to assume that every physical component will remain fixed. Infrastructure has a lifecycle involving deployment, maintenance, replacement, and architectural change. The contract should instead identify service characteristics that need continuity. Compute compatibility is one part of that definition. Network behavior, storage access, topology, location, and migration support may also matter. The exact combination should follow the customer’s workload.
Not every characteristic deserves equal contractual protection. Adding unnecessary requirements can restrict provider engineering without improving customer outcomes. C-level buyers should identify the smaller set of conditions whose loss would materially change capacity value. Those conditions form the durable layer of the agreement. Everything else can remain under normal provider control. This creates a more flexible and technically meaningful capacity contract.
Technical acceptance converts those requirements into something both sides can evaluate. The customer and provider can agree on representative tests before migration. Those tests may cover compute communication, storage, external connectivity, orchestration, and workload recovery. The suite should remain relevant to the actual deployment. Generic testing can miss characteristics important to one workload while measuring irrelevant ones. Acceptance works best when it follows the architecture being protected.
Accountability completes the continuity model
Migration controls have limited value when nobody remains responsible for restoring the complete customer-facing service. The customer contracts with the neocloud for usable compute rather than a collection of supplier relationships. The provider should therefore maintain clear responsibility for obligations within its service boundary. Internal disputes between infrastructure suppliers should not become prerequisites for customer support. This does not make the provider responsible for systems controlled exclusively by the customer. It creates a clear line around the service being purchased.
Customers must understand their side of that line as well. Application behavior, customer-controlled data, external systems, and certain configuration choices may remain their responsibility. Technical teams should know which actions they must perform during migration. Procurement should ensure those expectations appear clearly in the operating model. Neither side benefits from ambiguous ownership. Explicit responsibilities make infrastructure change easier to coordinate.
Cost responsibility should complete that picture. Migration can require temporary capacity, engineering effort, data movement, storage, and validation. Provider-initiated moves and customer-requested redesigns do not necessarily deserve identical commercial treatment. The agreement should distinguish them before either occurs. This allows both sides to understand the economics of continuity. Compute pricing then sits inside a broader view of infrastructure commitment.
The Strongest Capacity Strategy Assumes Infrastructure Can Change
A customer does not need to expect a partner change to prepare for one. Infrastructure planning already accepts that hardware, networks, storage, and operating arrangements evolve over time. Reserved AI capacity should be treated with the same realism. Buyers can define workload dependencies, service characteristics, migration responsibilities, and acceptance conditions before committing capacity. This does not make infrastructure change more likely. It simply prevents change from becoming an undefined event.
The provider can retain substantial engineering freedom within this model. Servers can move, network designs can evolve, cooling arrangements can change, and supporting infrastructure can be replaced. The customer does not need every physical detail preserved. It needs the material characteristics of the purchased service to remain within agreed boundaries. That distinction allows modernization without weakening continuity. It also keeps the contract focused on outcomes that matter to the workload.
Source retirement then becomes a controlled milestone rather than an invisible provider decision. Workload validation can occur before rollback disappears. Data responsibilities can be understood before the destination becomes authoritative. Network dependencies can be tested while remediation options remain available. Commercial remedies can activate when technical equivalence cannot be achieved. Together, these controls turn partner substitution into a manageable infrastructure lifecycle event.
Portability becomes part of capacity quality
Portability should not mean that every complex AI workload can move instantly between arbitrary environments. Datasets, network dependencies, storage relationships, authentication, orchestration, and application configuration can all complicate migration. A more practical definition asks whether those dependencies are understood and controllable. Customers should know which workload state they own and how it can move. Providers should know which infrastructure characteristics they have committed to preserve. That shared understanding makes relocation more predictable.
Workload architecture can strengthen this model by avoiding unnecessary dependence on undocumented characteristics of one deployment. Reproducible configuration, recoverable workload state, documented network paths, and clear data ownership can all improve portability. These practices do not remove the provider’s responsibility for infrastructure changes it initiates. They prevent customer-controlled dependencies from becoming hidden migration barriers. Provider capability and customer architecture therefore work together. Neither can guarantee continuity alone.
For C-level buyers, this changes the meaning of a strong capacity purchase. The value does not come only from obtaining GPUs at an acceptable price. It also comes from knowing what happens when the infrastructure supporting those GPUs changes. Migration responsibilities, acceptance criteria, data portability, rollback boundaries, and commercial remedies all contribute to that certainty. These elements deserve attention before workloads become difficult to move. Capacity quality includes the ability to survive controlled change.
The Capacity Promise Needs to Survive the Partner Change
A neocloud should not need to promise that its data center relationships will remain unchanged forever. Such a promise would ignore the normal evolution of infrastructure and commercial relationships. Customers instead need confidence that material service characteristics will survive those changes. The provider can accomplish this through controlled migration, clear responsibility, and technical acceptance. The customer contributes by understanding workload dependencies and maintaining realistic portability. Together, these controls create continuity without freezing the physical infrastructure.
This model also produces a better conversation about risk. A partner change does not automatically mean capacity will deteriorate. The destination may reproduce or improve the conditions supporting the workload. Risk arises when important characteristics change without preparation, validation, or clear responsibility. Procurement should therefore focus on the process governing infrastructure change rather than treating change itself as failure. That framing remains grounded while still protecting the customer.
The strongest contract makes those expectations visible before either side faces migration pressure. It defines what matters, who owns each task, how replacement capacity gets tested, and when source retirement can proceed. It also explains what happens when the proposed destination cannot satisfy agreed requirements. Technical teams gain an operating process while commercial teams gain a decision framework. The provider retains flexibility to evolve its infrastructure. The customer retains clarity about what its reserved capacity must continue to deliver.
AI capacity should be defined by what the workload can actually use
The defining question is not whether the neocloud keeps the same data center partner indefinitely. The more useful question asks what happens when the infrastructure relationship underneath the service changes. Workload state, data access, topology, connectivity, operating procedures, and contractual rights can all become relevant. A well-structured agreement addresses these factors before migration begins. Technical teams then have enough information to prepare and validate the destination. Procurement no longer needs to reconstruct the meaning of equivalent capacity during an active transition.
This approach also prevents the definition of AI capacity from shrinking to accelerator inventory precisely when continuity matters most. GPUs remain central to the purchase, but they operate inside a wider technical system. Networks, storage, power, cooling, orchestration, data paths, and operating processes help turn that hardware into usable compute. Not every component needs explicit contractual treatment. The components that materially affect the workload do. That distinction keeps the agreement focused without pretending the accelerator exists independently from its operating environment.
A data center partner change can therefore remain manageable when capacity continuity has been designed into the commercial relationship. The provider can evolve its infrastructure while preserving agreed workload conditions. Customers can validate replacement capacity before treating the transition as complete. Both sides can understand when rollback ends and what happens if equivalence cannot be achieved. Those protections make infrastructure change governable rather than invisible. For an AI buyer, that ability to survive change can matter as much as obtaining the reserved capacity in the first place.