Skip to content
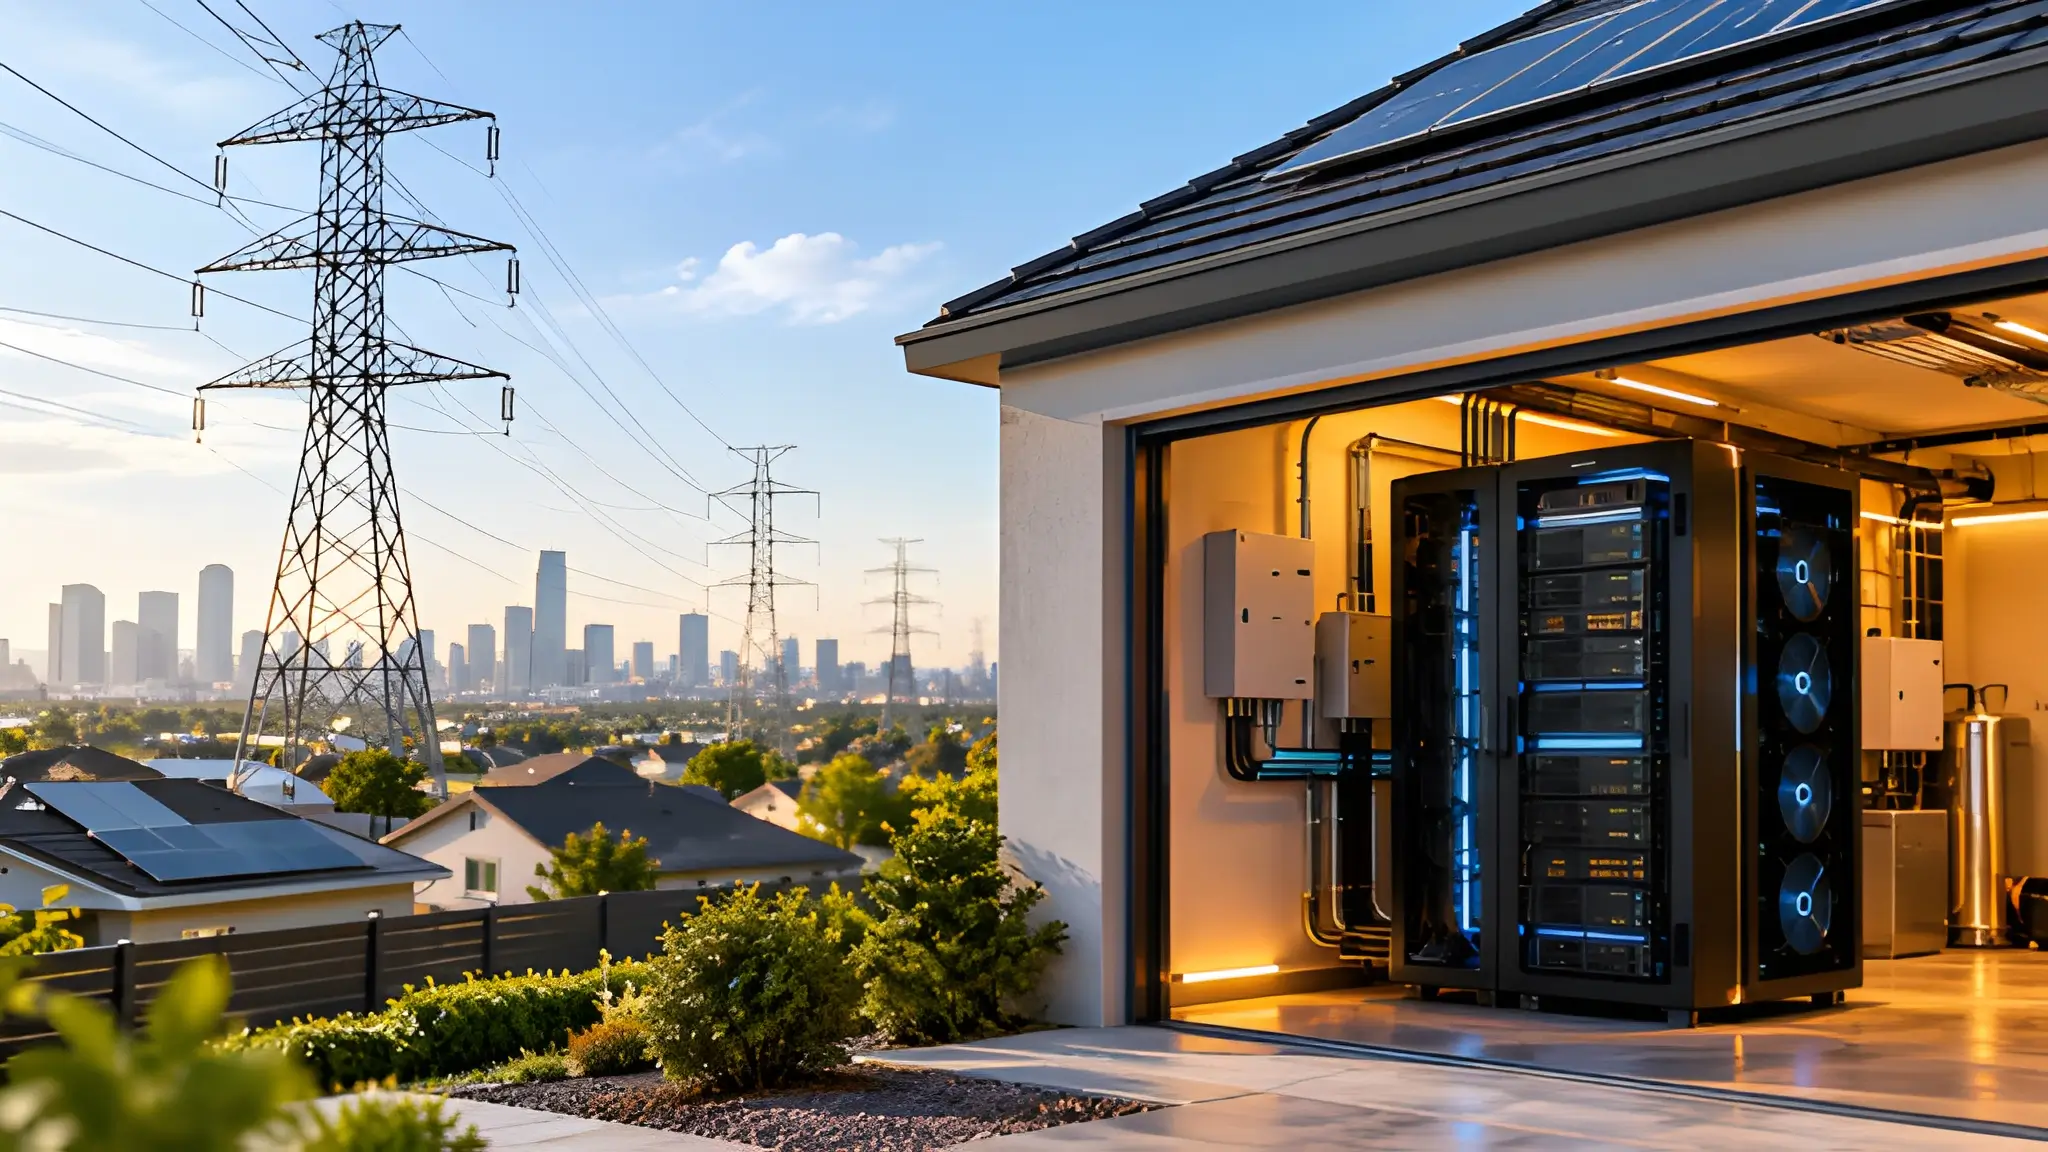
The most consequential change in AI infrastructure may not come from another record-breaking data center. It could come from a much less imposing machine sitting beside a house, inside a commercial building or within other parts of the built environment where distributed computing can operate. Electricity, grid connections, transformers, transmission capacity and construction timelines are becoming increasingly important considerations for compute deployment alongside advances in processors and software.
The conventional response is straightforward: build more generation, expand transmission, reinforce distribution networks and construct larger data centers wherever sufficient power eventually becomes available. If computing systems can safely use some of that headroom without compromising household demand, a network of relatively modest nodes could form a distributed computing layer. The grid is forcing AI infrastructure to rethink scale
A house could become part of the compute network
The idea of placing AI hardware near homes is no longer purely theoretical. SPAN has proposed a distributed computing system that places an AI compute unit alongside residential electrical infrastructure, using household electrical capacity and network connectivity. The company has described a model in which software can coordinate workloads across multiple nodes according to factors such as available energy and latency. The significance of that model extends beyond one company or one product. A residential electrical connection rarely operates at its theoretical maximum every second of the day. Commercial buildings, small industrial sites and other properties also experience changing load profiles.
If computing systems can safely use some of that headroom without compromising household demand, a network of relatively modest nodes could form a distributed computing layer. Instead of asking where to find one location capable of supporting hundreds of megawatts, operators could ask where the network has sufficient pockets of electrical and computational capacity to support smaller workloads. The resulting system would resemble a utility more than a conventional data center portfolio: geographically dispersed assets, centrally coordinated workloads and capacity that changes continuously according to local conditions.
Distribution solves one bottleneck while creating another
The attraction of the model is also its greatest complication. A hyperscale facility concentrates complexity. Operators can engineer its cooling systems, power distribution, networking, security and backup systems within a controlled environment. A distributed network would move much of that complexity into thousands of different locations. Cooling alone illustrates the challenge. A specialized data center can deploy high-density thermal infrastructure designed around a known rack configuration. A residential or neighborhood installation has far less room for error. The hardware must operate within tighter physical constraints while avoiding interference with the building’s existing electrical and thermal systems.
Reliability creates another problem. A centralized facility can maintain redundant power paths, backup generation and controlled networking. A distributed architecture could lose individual nodes regularly. The system therefore needs software that can detect failures, shift workloads and maintain service quality without treating every missing machine as a major incident. That makes orchestration a core infrastructure layer rather than a supporting feature. The network must understand not only where compute exists, but where electricity exists, when that electricity is available, how much thermal capacity remains and which workloads can tolerate movement.
Thousands of small machines could become one large machine
The technical opportunity becomes more compelling when AI workloads are divided according to their requirements. Not every inference request needs the same hardware. Some applications can tolerate additional latency or workload migration. Others require immediate responses and consistent access to nearby compute. Training large models presents an entirely different set of networking and synchronization requirements. This means distributed AI will not replace centralized infrastructure with a simple one-for-one alternative. It would create a hierarchy. Large facilities could handle tightly coupled training and high-density workloads. Regional facilities could process substantial inference demand. Smaller nodes could serve latency-sensitive applications closer to users. That architecture would make compute location more dynamic.
It could also change how the industry thinks about unused electrical capacity. Instead of treating spare capacity as an invisible margin within the distribution system, operators could potentially treat some of it as an input into a coordinated computing market. The concept remains difficult to implement at scale, but the underlying direction has technical precedent. Researchers have already demonstrated that AI workloads can respond dynamically to grid conditions. A Nature Energy study involving a 256-GPU cluster found that software-based workload orchestration reduced power consumption by 25% for three hours during peak demand while maintaining specified AI service guarantees. The lesson is broader than demand response. AI workloads themselves can become more flexible.
AI may be entering its distributed infrastructure phase
The strongest case for distributed AI compute is not that small machines are inherently superior to large data centers. It is that the physical constraints of AI are becoming too diverse for one infrastructure model to address every workload. Hyperscale campuses will continue to anchor the AI economy. But they may increasingly coexist with regional facilities, edge systems and potentially residential or commercial nodes that use capacity already embedded within the built environment. That would make AI infrastructure less geographically concentrated and potentially more responsive to local power conditions. It would also make the system considerably harder to engineer.
The industry would trade a handful of enormous infrastructure problems for thousands of smaller ones involving power quality, cooling, cybersecurity, connectivity, maintenance and orchestration. Whether that trade produces greater scalability remains unresolved. But the grid bottleneck is already forcing the question. The next phase of AI infrastructure may not be defined solely by how many GPUs a facility can install. It may be defined by how intelligently compute can move between the millions of places where electricity, network capacity and demand intersect. If that happens, the most important AI infrastructure asset may no longer be a giant campus on the edge of a transmission network. It could be the software and power architecture capable of turning scattered electrical headroom into one coordinated computing resource.