Skip to content

An AI deployment can appear ready while leaving one important infrastructure question unanswered. The processors may be installed, connected, powered, and prepared for production workloads. Yet those milestones reveal little about the thermal conditions supporting that compute. Cooling telemetry gives technical teams direct evidence about conditions across the cooling path. Temperature, flow, pressure, equipment status, and alarms can help engineers understand changing conditions. These measurements cannot guarantee reliability, but they provide evidence that teams can examine when questions emerge.
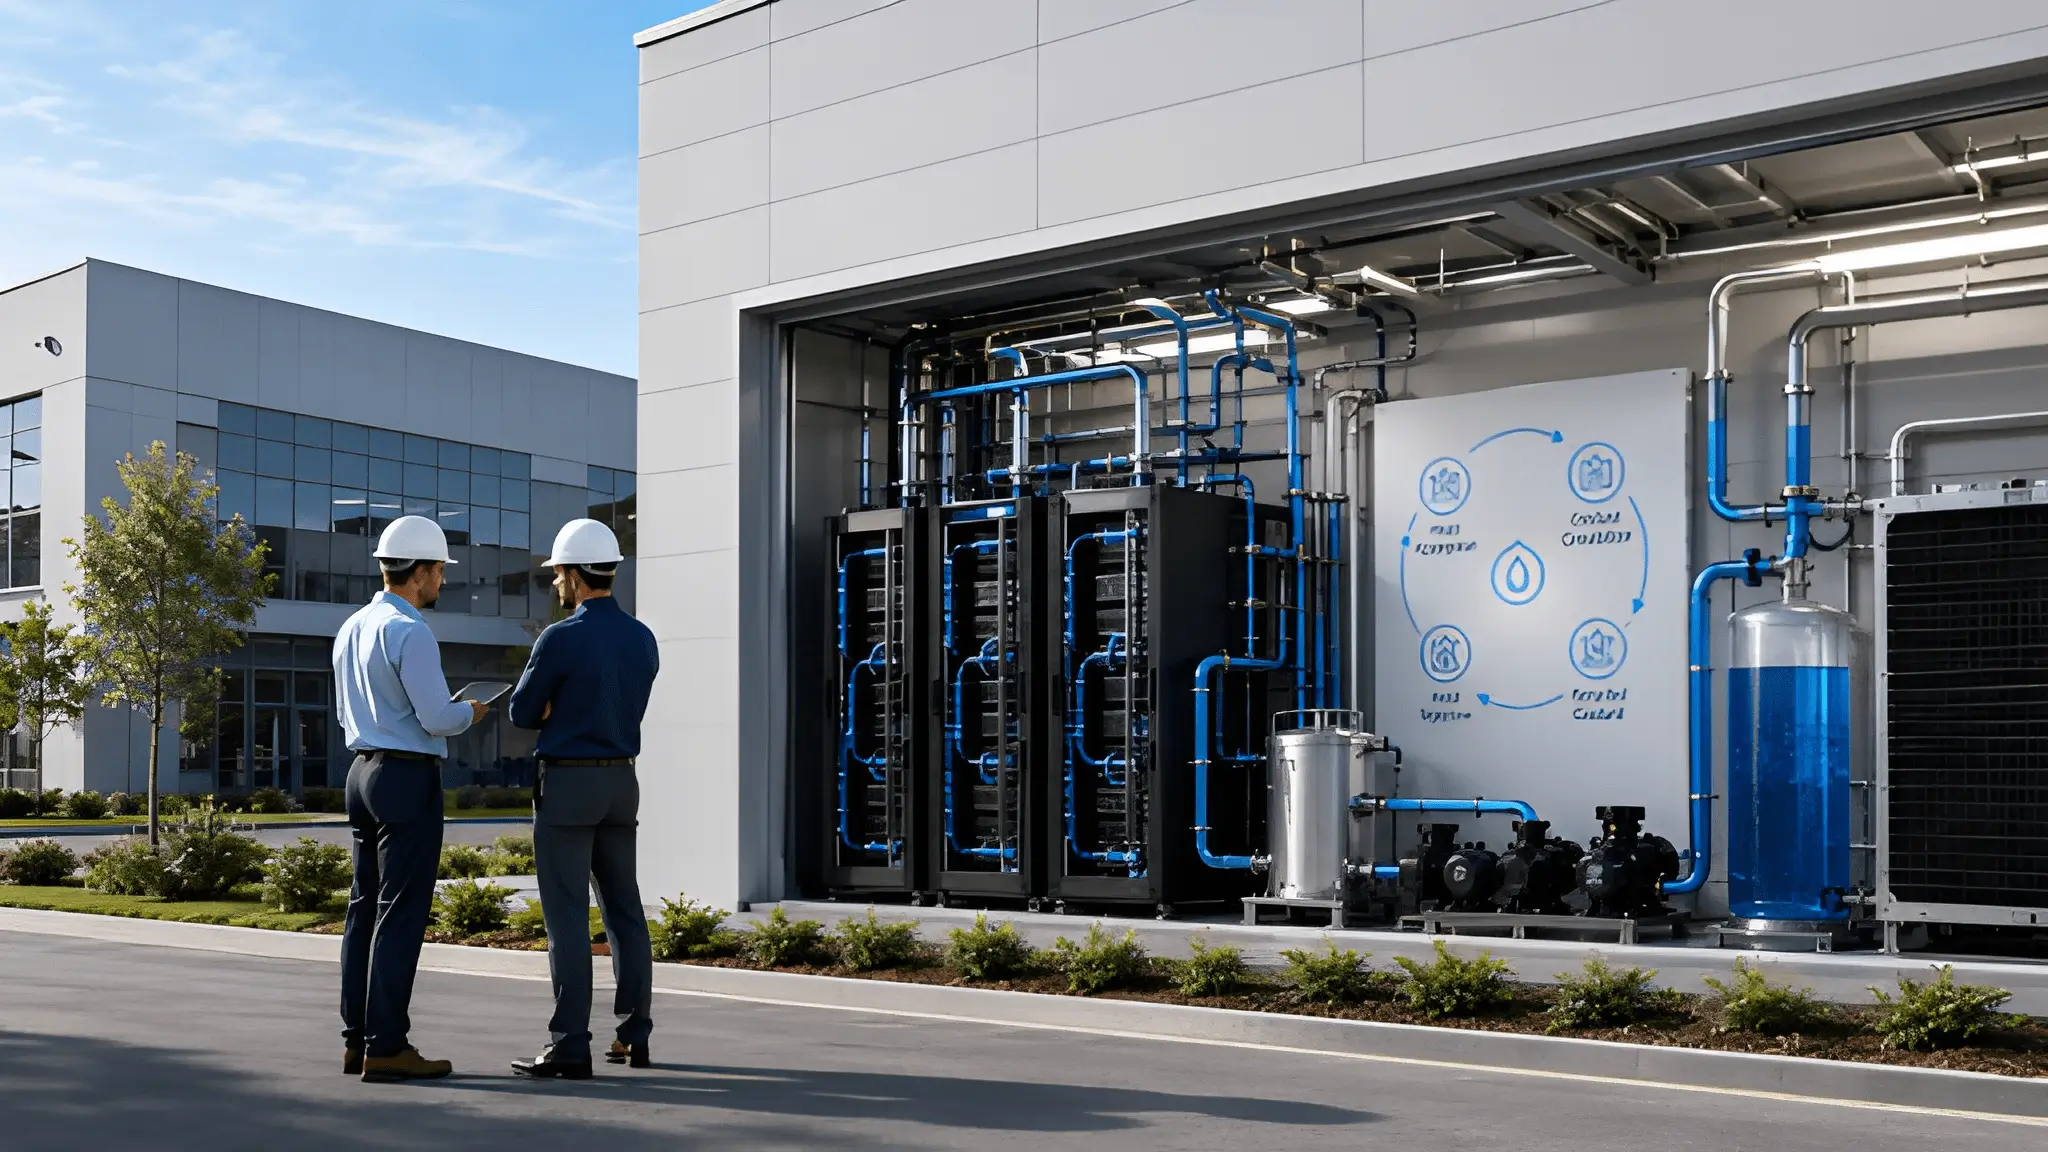
Liquid cooling makes that evidence increasingly relevant because heat removal now sits much closer to computing hardware. Coolant can pass through cold plates, connections, manifolds, pumps, filters, and heat exchangers. Every component performs a different role within the thermal path supporting the workload. Measurements from those locations also carry different meanings during a technical investigation. A temperature reading upstream cannot automatically describe conditions at every downstream connection. Customers therefore need enough context to understand what their available telemetry actually represents.
The issue is not simply whether cooling equipment exists or whether a monitoring dashboard looks sophisticated. Customers need to understand whether thermal behavior can be examined when capacity decisions depend on it. Historical records add context by showing how conditions changed before and after important events. Configuration records can explain why a thermal pattern changed after infrastructure modifications. Maintenance information can provide another layer when engineers investigate unusual behavior. Cooling telemetry due diligence connects these records with the physical infrastructure supporting AI capacity.
Cooling Visibility Is Becoming a Capacity Question
A cooling architecture can be fully installed while providing customers little evidence about its operating behavior. Equipment specifications explain intended performance under defined conditions, but they do not describe every operating state. Telemetry addresses a different question by showing what the installed system actually observed. Temperature, pressure, flow, equipment state, and alarms can provide parts of that evidence. Engineers can compare those measurements when thermal demand or control behavior changes. Customers gain stronger visibility when these signals remain connected to identifiable points within the cooling path.
Sensor placement matters because similar measurements can answer very different questions across a cooling architecture. Pressure measured near a pump represents a different location from pressure measured farther downstream. Temperature carries the same dependence on location within the thermal path. Flow information also needs a defined circuit because shared values can cover several branches. Reviewers should therefore understand where important sensors sit and what infrastructure each measurement represents. This prevents broad upstream measurements from becoming misleading evidence about conditions closer to individual racks.
Direct observation also needs a clear boundary because instrumentation rarely covers every physical connection. A manifold measurement may describe conditions at the manifold while downstream plumbing remains indirectly observed. That limitation does not make the measurement weak or unsuitable for technical analysis. It simply defines what engineers can conclude directly from the available evidence. Other measurements may help them infer conditions beyond that observation point. Strong due diligence keeps direct measurement and engineering inference separate throughout the review.
Historical Visibility Adds Operating Context
Real-time monitoring answers questions about the present state, while historical telemetry addresses a different need. Engineers may need to understand what happened before an unusual thermal or compute event. Trends can reveal whether temperature, pressure, or flow changed before another system responded. Equipment-state records can show whether pumps or valves changed during the same period. These relationships do not automatically establish causation, but they can guide further investigation. Customers therefore benefit when meaningful cooling history remains available after an event has passed.
Time alignment becomes important when cooling records need comparison with compute or other infrastructure evidence. Engineers may need to determine which change appeared first during an operating event. Poorly aligned timestamps can make that sequence difficult to establish with confidence. Accurate timing helps technical teams reconstruct events without depending entirely on retrospective explanations. It also allows different monitoring records to support or challenge a proposed sequence. Cooling telemetry becomes stronger evidence when several systems can be examined against a common timeline.
Retention determines how far investigators can look back when a problem appears after the original event. Not every cooling measurement needs permanent storage to support useful technical review. Important evidence should remain available for a period appropriate to likely investigations. Customers can ask how thermal history is retained without prescribing every storage decision. They can also ask whether historical exports preserve measurement identity and timing. These questions test whether telemetry can support due diligence after conditions have returned to normal.
Thermal Evidence Needs Physical Context
Heat does not disappear when liquid reaches the computing equipment generating it. Thermal energy must move through several physical stages before leaving the computing environment. Cold plates can transfer processor heat into a liquid circuit. Distribution components then move that heated coolant toward another heat-transfer boundary. Pumps and controls support the required movement through the thermal path. Measurements collected along this route describe different parts of the same cooling process.
Those boundaries matter because one measurement cannot automatically represent conditions throughout the entire system. Supply temperature describes the coolant at a particular measurement point. Return temperature describes another point after heat has entered the circuit. Flow measurements indicate coolant movement through the circuit where that measurement occurs. Pressure information can help engineers understand hydraulic behavior around its measurement location. Technical reviewers need this physical context before assigning broader meaning to any signal.
Separate liquid circuits make these distinctions even more important during technical analysis. A measurement on one side of a heat exchanger describes that particular circuit. Engineers should not automatically extend the reading across another thermal boundary. Shared cooling distribution creates a similar limitation when several downstream paths use common upstream equipment. Customers need enough topology information to understand where those boundaries exist. That knowledge prevents monitoring interfaces from making distinct thermal environments appear identical.
Related Measurements Create Stronger Evidence
Individual measurements become more useful when engineers examine how they relate to surrounding signals. Flow can change while temperature remains controlled because equipment responds to changing thermal demand. Pressure can move after a valve adjustment or another hydraulic change. Pump status can provide additional context when those measurements change together. None of these movements automatically indicates that cooling performance has deteriorated. Their relationships help engineers determine whether observed behavior makes physical sense.
Correlation also helps technical teams investigate measurements that appear inconsistent with surrounding evidence. One unusual temperature value may conflict with several otherwise stable related signals. That conflict does not prove that the temperature sensor has failed. Engineers can examine its location, history, communication state, and nearby measurements. They can then determine whether the signal requires instrumentation or cooling-system investigation. This approach reduces dependence on isolated measurements during customer due diligence.
Customers do not need to perform this engineering analysis themselves during every operating change. They need confidence that the evidence supports such analysis when important questions arise. A monitoring environment should therefore preserve useful relationships among relevant thermal signals. Simplified health indicators can still support routine operations and customer reporting. Deeper evidence should remain available when those indicators require technical examination. Cooling transparency becomes valuable when simplified reporting does not eliminate the supporting thermal record.
Capacity Acceptance Needs Cooling Evidence
Physical installation remains important, but installed components cannot demonstrate every condition encountered during actual operation. Pumps may run while engineers still need to examine coolant distribution under thermal load. Valves can respond correctly without proving behavior across every downstream branch. Sensors may show normal values while computing equipment generates relatively little heat. Capacity acceptance therefore benefits from evidence collected under relevant operating conditions. Telemetry can help technical teams examine how the cooling path responds as those conditions change.
The objective should not be to reproduce every workload pattern that customers might eventually run. Such a requirement would create unrealistic expectations for thermal acceptance. Instead, reviewers can examine conditions relevant to the planned computing configuration. Related measurements can show whether the cooling architecture responded coherently during those conditions. Engineering review can then interpret what the observed behavior demonstrates. Telemetry supports that process without replacing commissioning, testing, or technical judgment.
Acceptance evidence also needs limits because observations cannot guarantee future behavior under unknown conditions. Hardware configurations can change after the initial capacity enters service. Workload behavior can alter thermal demand across the computing environment. Maintenance and control changes may create new operating patterns later. Customers should therefore understand exactly what conditions produced the evidence being reviewed. This makes thermal acceptance more credible because conclusions remain proportional to actual observations.
Measurement Quality Matters During Acceptance
Instrumentation can generate extensive data while still providing weak evidence when physical context remains unclear. Temperature values need known measurement locations before engineers can interpret their meaning. Flow information requires the same clarity because different circuit boundaries produce different conclusions. Pressure readings also depend on where sensors sit within the hydraulic path. Alarm records need information about the conditions that triggered them. Otherwise, monitoring can appear comprehensive without answering the customer’s important technical questions.
Topology connects those measurements with the infrastructure they represent. Reviewers can use it to identify shared and dedicated portions of the cooling path. They can also determine whether measurements sit upstream or closer to customer equipment. This prevents a broad system-level signal from becoming mistaken for rack-level evidence. The topology does not need to expose unnecessary operational details to remain useful. It needs enough clarity for engineers to understand the measurement boundaries supporting their analysis.
A useful acceptance package also distinguishes direct measurements from values calculated by monitoring software. Derived indicators can simplify complex operating information for routine use. They should not become indistinguishable from the measurements used to create them. Reviewers need that distinction when deeper technical analysis becomes necessary. Clear provenance allows teams to move from an indicator toward its supporting evidence. Capacity acceptance becomes stronger when the monitoring layer preserves this traceability.
Dashboards Are Not the Same as Thermal Evidence
Dashboards make complicated cooling systems easier to observe, but visual simplicity can hide important limitations. A stable graph may not identify the physical location behind its measurement. The display may also omit maintenance activity or changes in control state. Workload context can disappear when monitoring focuses only on cooling equipment. Reviewers should therefore distinguish a useful interface from complete technical evidence. A visually clean dashboard does not automatically prove that the underlying telemetry supports detailed investigation.
Traceability makes dashboard information more valuable during customer due diligence. Engineers should know which physical points produced measurements used in important graphs. They should understand the period represented and whether the configuration changed during that time. Relevant maintenance activity can also affect how trends should be interpreted. These details allow reviewers to test the story suggested by the visualization. Without them, a polished interface can provide more reassurance than engineering evidence.
Static screenshots create another limitation because they capture selected information at one moment. Incident analysis often requires events before and after the displayed period. Engineers may need to compare several signals against the same timeline. A screenshot cannot always preserve the sequence needed for that work. It may also omit information that seemed unimportant when the image was created. Customer due diligence should therefore consider the evidence behind the dashboard rather than screenshots alone.
Instrumentation Health Is Part of Evidence Quality
Cooling telemetry remains useful only when the measurement system itself provides dependable information. Sensors can require inspection, validation, recalibration, replacement, or other technical attention. Communication problems can interrupt data even while cooling equipment continues operating normally. Mapping errors can also associate measurements with the wrong physical context. These conditions can weaken evidence without creating an actual cooling failure. Customers should therefore consider how questionable telemetry becomes identified and investigated.
Related signals can help engineers recognize when a measurement deserves closer examination. One value may behave differently from several measurements that normally move together. That difference does not automatically mean the sensor is defective. Engineers can compare the signal with physical conditions and surrounding telemetry. Instrumentation history may explain a discontinuity that otherwise appears to be a cooling change. This process protects technical decisions from uncritical reliance on one digital value.
Missing information deserves equal attention because absent data cannot demonstrate that conditions remained stable. Monitoring interfaces should distinguish stale values from current observations. Historical records should also identify periods when measurements were unavailable. That transparency allows investigators to understand the limits of the evidence they possess. Hiding gaps behind continuous-looking graphs can create misleading confidence during later analysis. Strong telemetry communicates uncertainty as clearly as it communicates normal operating conditions.
Historical Telemetry Changes Technical Due Diligence
A cooling environment may look normal when someone opens a dashboard after an event. Its earlier history can still contain behavior that deserves technical investigation. Temperature relationships may have changed before returning to their usual range. Flow or pressure behavior may show another temporary operating pattern. Control activity can reveal how the system responded during the same period. Historical telemetry allows reviewers to examine these changes after the immediate condition has disappeared.
Movement within a trend does not automatically mean cooling performance deteriorated. Workload changes can legitimately alter thermal behavior across the cooling system. Planned maintenance can also create temporary differences within normal operations. Control adjustments may establish a new pattern after infrastructure changes. Engineers therefore need context before interpreting a movement as abnormal. Due diligence should seek explainable behavior rather than perfectly flat thermal graphs.
Stable readings require similar caution because active controls may maintain them while other variables change. A constant temperature does not necessarily mean the cooling system operated identically throughout the period. Pump behavior or coolant flow may have changed to maintain that condition. Those changes can represent correct control response rather than instability. Historical analysis becomes stronger when several related measurements remain available together. Customers can then understand how the cooling system maintained the observed operating state.
Baselines Need Relevant Operating Conditions
A baseline provides a reference for expected behavior under a known infrastructure configuration. It becomes less useful when reviewers ignore the operating conditions that produced it. The same cooling path can behave differently as compute activity changes. Control states can also influence relationships among temperature, pressure, and flow. A meaningful baseline therefore needs technical context rather than a generic historical average. Customers should know which configuration and operating state the reference actually represents.
Baselines should not become rigid rules because infrastructure changes can establish legitimate new operating patterns. Hardware refreshes may change the thermal demand presented to the cooling system. Distribution changes can alter hydraulic relationships across the cooling path. Control adjustments can modify how pumps or valves respond. Maintenance may also produce a different but appropriate operating state. Technical teams should refresh their reference when those changes materially affect thermal behavior.
Customers benefit from knowing when a baseline changes and why engineers considered the change appropriate. That record helps distinguish configuration effects from unexplained thermal movement. It also improves later incident analysis because teams can use the correct reference. Older telemetry remains useful as infrastructure history rather than current operating evidence. Configuration context prevents historical comparisons from becoming misleading. Cooling due diligence becomes stronger when baseline changes remain technically explainable.
Cooling Changes Need a Telemetry Record
Maintenance changes the physical state of cooling equipment and can therefore alter observable operating behavior. Filter work may influence hydraulic conditions within the relevant cooling path. Pump service can change equipment response after the work is completed. Valve adjustments may also alter distribution relationships across connected branches. These changes do not automatically indicate a problem with the cooling environment. Telemetry can help engineers understand whether post-maintenance behavior remains coherent with the updated configuration.
Maintenance records and telemetry become more useful when technical teams can examine them together. A changed pressure relationship may make sense after known work on relevant equipment. Without that context, the same change might appear unexplained during a later review. Component replacement can also establish a different operating pattern. Engineers need maintenance history to understand why the pattern changed. Customers benefit because thermal evidence then carries operational context rather than appearing as isolated data.
Post-maintenance verification deserves particular attention when significant work affects the thermal path supporting active compute. Closing a work order does not itself demonstrate the resulting operating condition. Relevant measurements can help engineers examine behavior after the intervention. The new pattern does not always need to match the earlier baseline. A component or configuration change may legitimately establish different behavior. What matters is whether technical teams understand and can explain the resulting state.
Infrastructure Changes Alter Historical Meaning
Cooling environments also change when capacity expands or computing hardware receives a major refresh. New racks can modify thermal demand across existing distribution paths. Additional branches may change hydraulic relationships within shared cooling circuits. Control modifications can alter how equipment responds to similar operating conditions. Earlier telemetry may then describe a materially different physical configuration. Historical analysis needs a record of those changes to remain technically meaningful.
Sensor changes deserve the same discipline because measurement identity can survive after physical modifications. A sensor may move while retaining a familiar label in the monitoring interface. Its values could then describe a different location from earlier records. Replacement instrumentation can create another discontinuity within historical trends. Reviewers need enough documentation to recognize these transitions. Otherwise, monitoring can create artificial continuity where the physical measurement context has actually changed.
Control modifications can also change telemetry without requiring a major physical reconstruction. Revised pump behavior may alter pressure or flow relationships during normal operation. Valve-control changes can produce another operating pattern under similar thermal demand. Customers do not need access to proprietary control logic to understand these changes. They need enough context to know that a material modification occurred. This keeps historical evidence aligned with the infrastructure state that actually produced it.
Anomaly Detection Requires Engineering Context
Cooling systems naturally produce changing measurements as workloads and controls move through different operating states. Maintenance and infrastructure changes can create additional variation within historical telemetry. An anomaly should therefore trigger investigation rather than an automatic failure conclusion. Engineers need to determine whether the movement fits the known physical system. Surrounding measurements can help them make that assessment. Customers gain better evidence when unusual signals receive technical interpretation instead of simplistic labels.
Several related measurements can strengthen an investigation when a thermal condition appears unusual. Temperature may change alongside flow, pressure, or equipment state. Compute activity can provide another part of the operating sequence. Engineers can examine whether those movements remain physically consistent. A single signal should rarely carry the entire conclusion about cooling behavior. Correlated evidence provides a stronger foundation for determining whether deeper investigation is necessary.
Duration also changes the meaning of an event because brief and persistent conditions can require different interpretations. A control system may detect and correct a temporary change as intended. Historical telemetry can show whether that response occurred and how quickly conditions stabilized. A longer deviation may justify another level of technical review. Neither case should receive an automatic conclusion without surrounding context. Due diligence should preserve enough history to distinguish these different operating patterns.
Predictive Signals Need Careful Interpretation
Telemetry can reveal changing behavior before a visible workload disruption occurs. That does not mean every unusual trend predicts an approaching cooling failure. Flow, pressure, temperature, and equipment behavior can change for several legitimate reasons. Engineers need operating context before deciding whether a pattern deserves intervention. Maintenance history and configuration records can strengthen that interpretation. Predictive language should therefore remain proportional to what the available evidence actually demonstrates.
Condition-based monitoring can still provide practical value by identifying behavior that deserves earlier technical attention. A trend may prompt inspection before the condition develops into a larger problem. Engineers can compare that signal with related measurements and physical equipment. They can also determine whether recent maintenance explains the change. This process improves awareness without pretending that telemetry removes uncertainty. Customers should value earlier evidence while remaining cautious about absolute predictions.
Instrumentation coverage creates another limitation because sensors observe only the points included in the monitoring design. An unmonitored condition can develop without appearing directly in customer-facing telemetry. Communication failures may create additional gaps during important operating periods. Unexpected failure mechanisms can also fall outside configured monitoring logic. Telemetry should therefore complement engineering and maintenance practices rather than replace them. Strong due diligence recognizes both the power and limits of thermal observability.
Rack-Level Visibility Can Reveal Local Differences
Upstream cooling conditions cannot automatically describe every downstream branch within a distribution system. Pipe routing can influence hydraulic behavior across different portions of the cooling path. Valve positions and filtration conditions may also affect local coolant movement. Branch configuration adds another physical variable that engineers must consider. A stable central measurement can therefore coexist with different conditions closer to individual racks. Local instrumentation can provide additional evidence where the cooling architecture includes it.
Central monitoring remains important because it describes the broader operating environment supporting the distribution system. Rack or branch measurements answer more localized questions about downstream conditions. Technical teams may need both perspectives when investigating a specific event. The measurements should not become interchangeable simply because they describe similar variables. Physical location determines what each observation can establish. Customers need this distinction when evaluating how closely telemetry represents their assigned compute.
Visibility can also stop before coolant reaches every component within a rack. A manifold measurement may represent conditions at the distribution point serving several connections. Coolant continues through hoses, connectors, server plumbing, and cold plates beyond that boundary. Stable manifold telemetry cannot independently prove every downstream condition. Equipment-level data may provide additional evidence where available. Clear measurement boundaries prevent technical teams from extending observations beyond their actual physical scope.
Data Granularity Should Match the Question
Not every cooling investigation needs the highest possible data resolution. Long-term stability analysis may rely on broader trends across relevant measurement points. A short operating event can require more detailed records around a narrower period. Data resolution should therefore follow the technical question being investigated. Collecting more samples does not automatically produce stronger evidence. Sensor placement and measurement quality remain equally important to the analysis.
Sampling intervals influence what engineers can observe within historical telemetry. Widely spaced records can show gradual changes while providing less information about shorter events. More frequent collection can reveal additional detail around fast transitions. Yet frequent data remains weak when timestamps or physical context are unreliable. Monitoring design should therefore reflect the behavior of the system being observed. Event records can complement routine trend data when engineers need another level of detail.
Aggregation creates similar trade-offs because averaging simplifies storage and visualization. It can also conceal brief changes occurring inside the aggregation period. Other summaries may preserve useful context about the range of observed behavior. Customers do not necessarily need access to every raw sample. They need enough detail to support investigations relevant to their capacity. Due diligence should therefore examine evidence usefulness rather than raw data volume.
Telemetry Access Creates a Commercial Boundary
Customers may need cooling evidence without needing authority over the cooling equipment itself. Pumps, valves, controllers, and protective logic should remain under controlled operational responsibility. Due diligence does not require customers to manipulate those systems. It requires enough information to evaluate thermal conditions relevant to their compute. This creates a clear distinction between observation and operational control. A well-designed evidence process can maintain that boundary throughout the deployment.
Customer-facing evidence can take several forms depending on the cooling architecture and operating model. Selected trends may provide enough visibility for routine technical review. Historical exports can support deeper analysis after an important event. Structured reports may work better where direct monitoring access creates security concerns. Incident packages can provide additional evidence when deeper investigation becomes necessary. The appropriate method matters less than whether the resulting information remains technically meaningful.
Shared cooling infrastructure makes this separation particularly important because telemetry may represent more than one customer’s environment. Raw data could expose information unrelated to the customer requesting the evidence. Providers may therefore need to scope customer-facing information carefully. That filtering should still preserve enough context for technical interpretation. Excessive abstraction can reduce transparency to a generic status indicator. Useful due diligence balances operational security with meaningful thermal evidence.
Investigative Access May Need Different Rules
Routine visibility and incident visibility do not need to provide identical levels of detail. Daily operation may require only selected indicators relevant to customer capacity. A significant incident can justify deeper technical evidence from the same period. Engineers may need additional trend data, alarms, or equipment-state information. Maintenance records can also become relevant during that review. Defining this escalation path early can reduce uncertainty after an event occurs.
Historical exports need enough context to remain understandable outside their original monitoring interface. Timestamps should identify when each observation occurred. Measurement identities should remain clear after the data leaves the dashboard. Engineering units also need to stay understandable during independent analysis. Relevant topology should connect signals with their physical measurement locations. These details allow technical teams to correlate cooling evidence with other operational records.
A screenshot alone may not provide the depth needed for a serious incident investigation. It captures selected information during a chosen period. Investigators may need events that occurred before or after that view. They may also need several signals aligned against compute records. A defined evidence process supports this deeper examination. Telemetry access then becomes a practical due-diligence capability rather than unrestricted system access.
Incident Attribution Requires Correlated Evidence
A workload problem does not automatically reveal which infrastructure layer contributed to the event. Engineers may need evidence from compute, networking, power, and cooling systems. Those records become more useful when their timelines can be compared. Cooling telemetry can show whether relevant thermal conditions changed around the compute event. Sequence can help narrow possible explanations without automatically proving causation. Technical teams still need engineering analysis before assigning responsibility.
The order of events can materially change how investigators interpret the evidence. Compute activity may decline before the cooling system changes its behavior. Reduced thermal demand could then explain the later cooling response. In another event, a coolant condition might change before compute behavior moves. That sequence could justify deeper investigation into the thermal path. Engineers need the complete evidence before deciding which explanation best fits the event.
Different operational teams may hold separate parts of this evidence. Compute records might sit in one monitoring environment while cooling history sits elsewhere. Retention practices can also differ across those systems. Poor timestamp alignment can make later correlation difficult. A predefined investigation process reduces these practical barriers. Customers can consider this capability before they depend heavily on the deployed capacity.
Cooling Telemetry Cannot Prove Everything
Cooling telemetry can narrow an investigation without becoming an automatic root-cause system. Sensors observe selected conditions at selected physical locations. They do not capture every possible mechanism affecting compute operation. Stable upstream measurements cannot prove every downstream condition remained unchanged. Local deviations also cannot independently prove that cooling caused a workload event. Technical attribution therefore needs evidence from several relevant domains.
Alarm history carries similar limitations during incident analysis. No alarm means no configured alarm condition activated within the monitored logic. It does not prove that every thermal condition remained unchanged. A movement can remain inside configured limits while still appearing in trend data. Another condition may occur beyond the monitored locations. Alarm records should therefore support investigation rather than replace broader evidence.
Normal-looking telemetry needs the same disciplined interpretation. Stable measurements can support conclusions within the boundaries actually observed. Engineers should still acknowledge conditions outside those measurement points. This does not weaken the technical analysis. It makes the conclusion proportional to the available evidence. Due diligence improves when thermal claims remain grounded in what the monitoring system actually observed.
Thermal Transparency Can Shape Capacity Comparison
Two computing environments can offer similar hardware while providing different levels of thermal evidence. One may preserve useful operating history and clear measurement boundaries. Another may provide only limited customer-facing information about cooling behavior. Greater visibility does not prove that one cooling architecture performs better. Physical cooling capability and observability remain separate characteristics. Visibility does affect how easily customers can investigate unexpected infrastructure behavior.
Buyers should avoid turning telemetry into a simple sensor-count comparison. More sensors do not automatically create better cooling or stronger evidence. Measurement location matters because each signal describes a specific physical point. Data quality and historical context also influence its usefulness. Topology determines whether reviewers can understand the relationship among those signals. The better question is what the available evidence can actually explain.
Export capability can influence investigations when thermal records need comparison with compute information. Useful exports preserve timestamps and measurement identities during that process. Physical context should also remain understandable outside the original monitoring interface. Security requirements can still limit direct access to operational systems. Controlled evidence can satisfy many customer needs without weakening those protections. Procurement teams should understand these processes before a serious technical question emerges.
Migration Creates a New Thermal Evidence Model
Moving workloads changes more than the location of the computing hardware. The destination may use a different cooling architecture and monitoring model. Sensor locations can differ even when signal names look familiar. Historical baselines from the previous environment may therefore lose direct relevance. Customers need a new understanding of the destination thermal path. Migration due diligence should include this change in observability.
Similar telemetry labels can create misleading comparisons between different cooling environments. Supply temperature may represent different physical boundaries across two architectures. Flow can also be measured at different levels within separate distribution systems. Buyers should map the physical meaning behind each important field. Direct field matching can otherwise create false equivalence. Functional observability matters more than identical terminology.
The destination environment also needs its own operating reference after the workload arrives. Initial telemetry can help establish how the new cooling path behaves. Engineers can observe conditions as computing activity reaches normal operating patterns. That history creates a reference for future technical investigations. Migration planning can therefore include thermal evidence alongside compute and network considerations. The workload enters a new physical environment, not merely another allocation of processors.
Cooling Due Diligence Should Follow the Capacity Lifecycle
Cooling conditions can change throughout the useful life of an AI deployment. Hardware additions can alter the thermal demand placed on existing distribution paths. Maintenance can introduce another change in physical operating conditions. Control updates may modify how cooling equipment responds. A predeployment review cannot represent every future infrastructure state. Continuing telemetry gives technical teams evidence for examining these changes later.
The same data can support different questions at different stages. During acceptance, engineers can examine readiness under relevant operating conditions. Routine operation can use historical trends to identify behavior requiring investigation. Maintenance teams can compare conditions before and after significant work. Expansion can create a reason to establish another baseline. Incident analysis uses the same evidence to reconstruct events and test possible explanations.
C-level oversight should remain focused on evidence quality rather than raw cooling dashboards. Executives do not need every thermal signal during normal operation. They need confidence that technical teams can investigate important conditions when necessary. Escalation paths should remain clear when thermal issues threaten capacity or deployment commitments. Decision rights should also identify who evaluates the technical evidence. Telemetry creates business value when it improves accountability without creating unnecessary operational noise.
Hardware Refreshes Reopen the Cooling Question
New computing hardware can change the thermal conditions presented to an existing cooling environment. Rack configurations may change alongside the hardware. Coolant interfaces can also differ across successive computing designs. Previous thermal evidence may therefore become less representative after a major refresh. Engineers should reassess the cooling path supporting the updated equipment. Telemetry can provide evidence for that reassessment once the new configuration enters service.
Cooling boundaries may change during the refresh as distribution equipment receives modifications. New manifolds or connections can alter the physical path supporting individual racks. Existing sensors may still provide appropriate visibility after those changes. Technical teams should verify that assumption rather than inherit it automatically. Additional instrumentation is not always necessary when existing measurement points remain relevant. The monitoring architecture simply needs to reflect the physical environment actually supporting the new hardware.
Historical continuity requires careful treatment during these transitions. New hardware may create a legitimate operating baseline different from the previous configuration. Old and new telemetry should not become automatically interchangeable. Engineers can document the transition and establish an updated reference. Earlier records remain useful for understanding the cooling environment’s history. Current due diligence should rely on evidence relevant to the equipment actually operating now.
Cooling Telemetry Is Becoming Part of AI Customer Due Diligence
AI capacity depends on more than the processors assigned to a customer. Power must reach the hardware under the required operating conditions. Networks must support the workload’s communication requirements. Cooling must remove heat produced while that computing equipment operates. Customers increasingly need evidence about these physical dependencies when evaluating usable capacity. Thermal observability adds another layer to that evaluation.
This does not mean every customer needs a live cooling console. Selected reports may provide enough evidence for some deployment models. Scoped telemetry exports can support deeper review when necessary. Incident processes can provide additional records after significant operating events. The appropriate mechanism depends on the architecture and commercial relationship. What matters is whether meaningful evidence exists before customers urgently need it.
Procurement can address that question before workloads become dependent on the infrastructure. Technical teams can identify which thermal variables matter to their deployment. They can also understand measurement locations and historical retention practices. Commercial teams can define suitable information and investigation processes. Executives then gain clearer evidence about the physical environment behind committed compute. Cooling telemetry becomes due diligence without turning customers into cooling-system operators.
The Shift Is From Assurance Toward Evidence
Cooling has often remained abstract from the customer’s perspective during infrastructure procurement. Buyers could review designs and rely heavily on operational assurances. Liquid-cooled AI infrastructure gives customers reasons to examine that abstraction more closely. The thermal path now interacts directly with high-value computing equipment inside the rack. Its operating behavior can therefore become relevant to capacity decisions. Telemetry provides one practical method for making selected conditions observable.
The standard should remain proportional because customers do not need every available measurement. They need evidence that answers relevant technical questions. Direct observations should remain distinct from engineering conclusions built from those observations. Monitoring gaps should remain visible rather than disappearing inside simplified reports. Historical records should retain enough context for meaningful investigation. This creates transparency without turning telemetry into an unnecessary data-volume exercise.
Cooling telemetry cannot eliminate infrastructure risk or guarantee future operating performance. It cannot independently predict every failure or establish every root cause. Its practical value lies in providing evidence that technical teams can examine. Engineers can use that evidence to test assumptions, timelines, and explanations. C-level buyers can then make infrastructure decisions with better visibility into an important physical dependency. Cooling telemetry due diligence is ultimately about making AI capacity more technically understandable throughout its operating lifecycle.